

Fix Acrobat Pro 2017 Crashing During OCR from Scanner

Question details
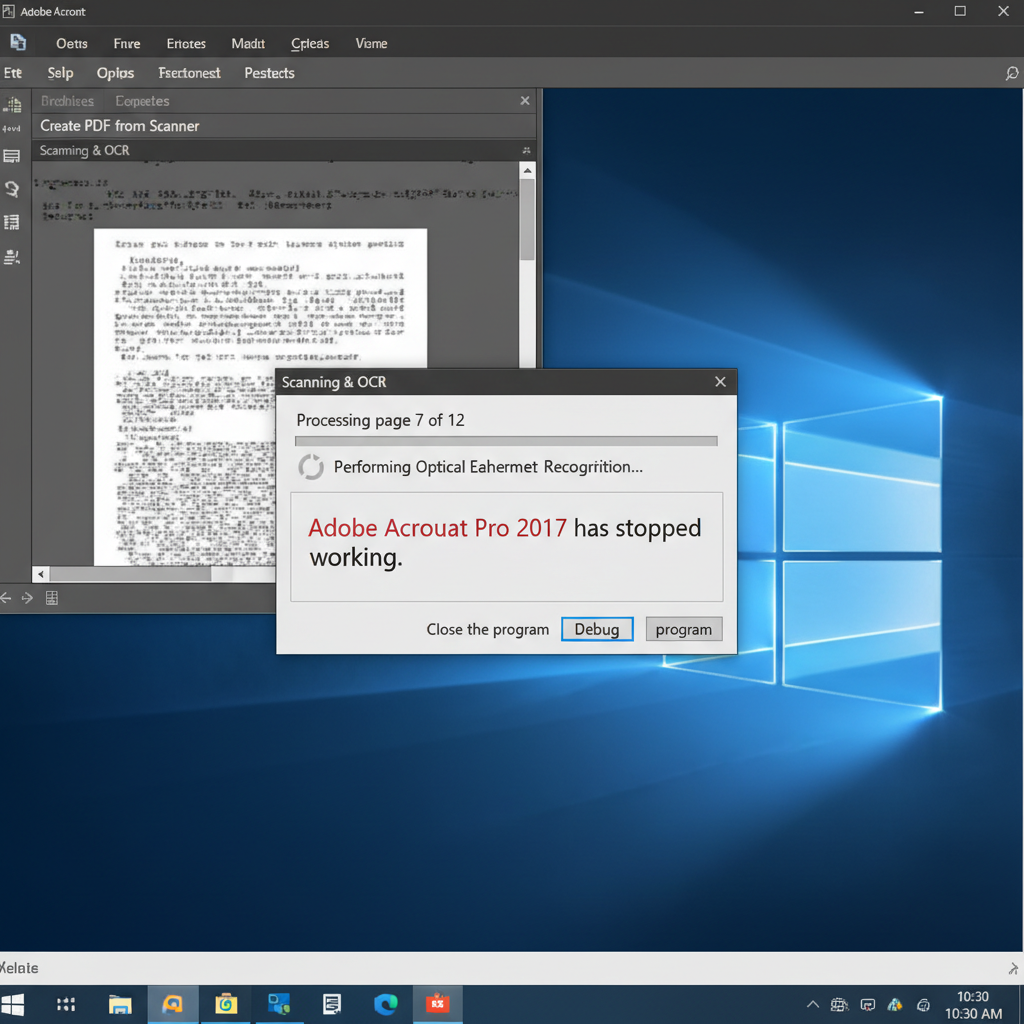
Adobe Acrobat Pro 2017 crashes intermittently while performing Optical Character Recognition (OCR) directly from a scanner.
- Product
- Adobe Acrobat Pro 2017
- Device & OS
- Windows 10
- Scenario
- Using the 'Create PDF from Scanner' feature with automatic OCR enabled.
- Observed behavior
- The application closes unexpectedly or freezes during the OCR process, often after several pages have successfully scanned, resulting in lost work.
Save any open documents, ensure your scanner is properly connected to your computer, and check that the scanner is powered on before beginning troubleshooting.
Update Software and Drivers
Outdated scanner drivers or older builds of Acrobat 2017 often cause memory conflicts during intensive OCR tasks.
Keeping your operating system, application software, and hardware drivers on the exact same update cycle prevents miscommunication between the scanner and the PDF editor.
Open Acrobat Pro 2017, click on 'Help' in the top menu bar, and select 'Check for Updates'. Install any available patches.
Right-click the Windows Start button and open 'Device Manager'. Expand 'Imaging devices', right-click your scanner model, and select 'Update driver'.
Go to Windows Settings > Update & Security > Windows Update, and click 'Check for updates' to ensure system stability.
Separate the Scanning and OCR Processes
Disabling automatic OCR during the scan and applying it afterward reduces the immediate processing load on your computer.
Repair the Acrobat Installation
Corrupted application files or missing registry keys can trigger crashes when accessing the scanner interface.
Perform OCR on Scanned Documents Reliably with WPS PDF
If your current PDF software continues to crash during intensive scanning tasks, switch to WPS PDF. It offers a highly stable, built-in OCR engine that smoothly extracts text from scanned documents without freezing, ensuring you never lose your scanned pages.
- 1. Open WPS PDF: Launch WPS Office and switch to the PDF tools section.
- 2. Import Your Scanned File: Open the scanned PDF document that requires text extraction.
- 3. Access the OCR Tool: Navigate to the 'Tools' tab and click on the 'OCR' or 'Picture to Text' button.
- 4. Configure OCR Settings: Select your document's language and choose whether you want to extract text or convert it into a searchable PDF.
- 5. Extract and Save: Click 'Start' to process the document. Once completed, save the newly searchable file to your local drive.

Frequently Asked Questions
Why does OCR cause my PDF software to crash?
Optical Character Recognition (OCR) is a resource-intensive process. If your computer lacks sufficient RAM, the scanned resolution (DPI) is too high, or there is a miscommunication between the scanner driver and the software, the PDF editor can freeze or crash.
Can I recover the pages I scanned before the crash happened?
Unfortunately, if the application crashes before the PDF is fully generated and saved to your hard drive, the temporary scanned data is usually lost. Scanning without automatic OCR and saving frequently in smaller batches is the best way to prevent data loss.
Does my scanner's DPI setting affect OCR stability?
Yes, scanning at a very high DPI (such as 600 DPI or above) creates massive temporary image files that can easily overwhelm the OCR engine. For most text documents, setting your scanner to 300 DPI is the ideal balance for stable performance and accurate OCR results.


