

Fix Adobe Acrobat Pro 2020 OCR and Recognize Text Not Working

Question details
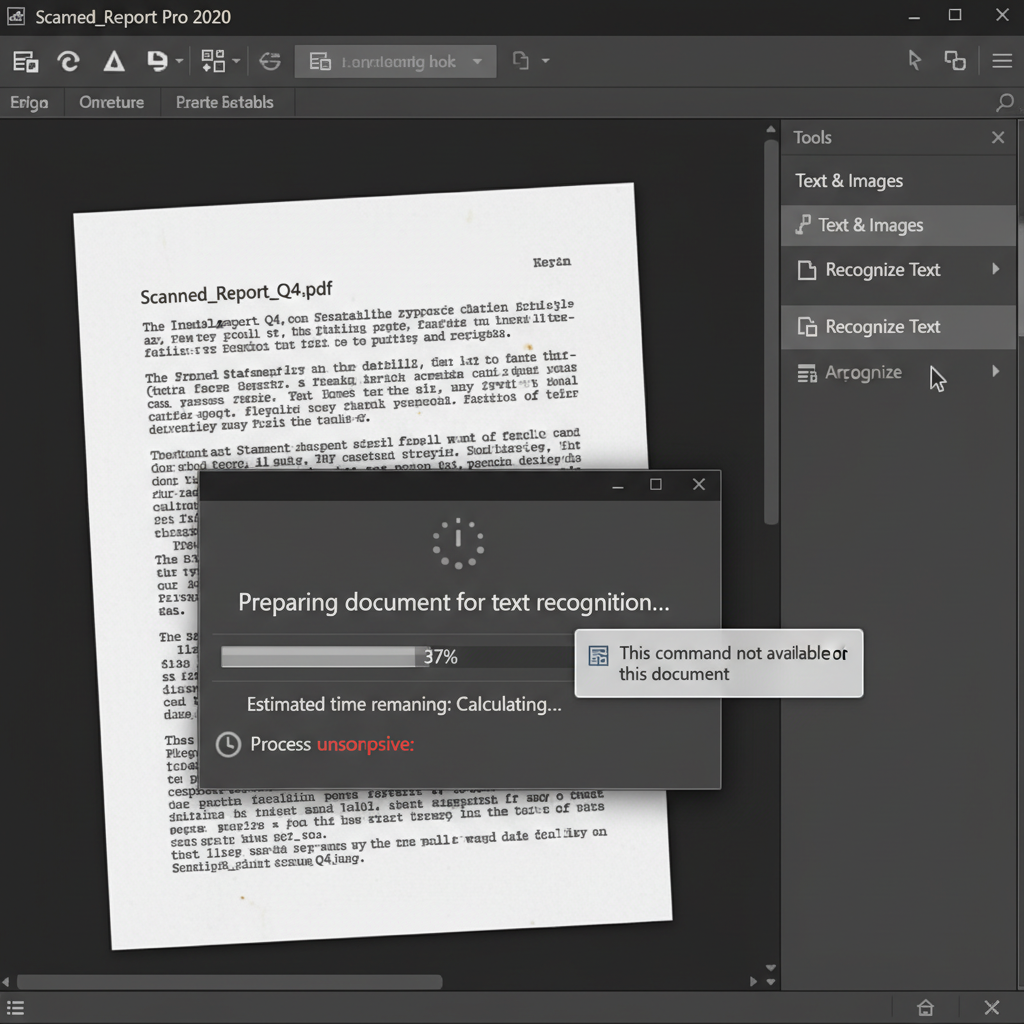
Users are experiencing issues where Adobe Acrobat Pro 2020 fails to recognize text in PDF files. The Recognize Text command is either unavailable or the preparation process gets stuck indefinitely.
- Product
- Adobe Acrobat Pro 2020
- Device & OS
- not provided
- Scenario
- Attempting to extract or edit text from a scanned PDF document using the Optical Character Recognition (OCR) feature.
- Observed behavior
- The Recognize Text command is greyed out, or the text recognition preparation process hangs and remains stuck without completing.
Check if the text in your PDF document is already selectable using your mouse cursor. If you can highlight individual words, the document already contains recognized text, which is often why the OCR command becomes unavailable.
Run Manual OCR via the Scan & OCR Tool
If Acrobat's automatic Edit mode fails to trigger OCR, manually initiating the process through the dedicated Scan & OCR tool can force the document to process.
Acrobat Pro usually attempts to automatically perform OCR when you enter Edit mode. When this background process fails, switching to the manual tool allows you to bypass the hang and configure language settings explicitly.
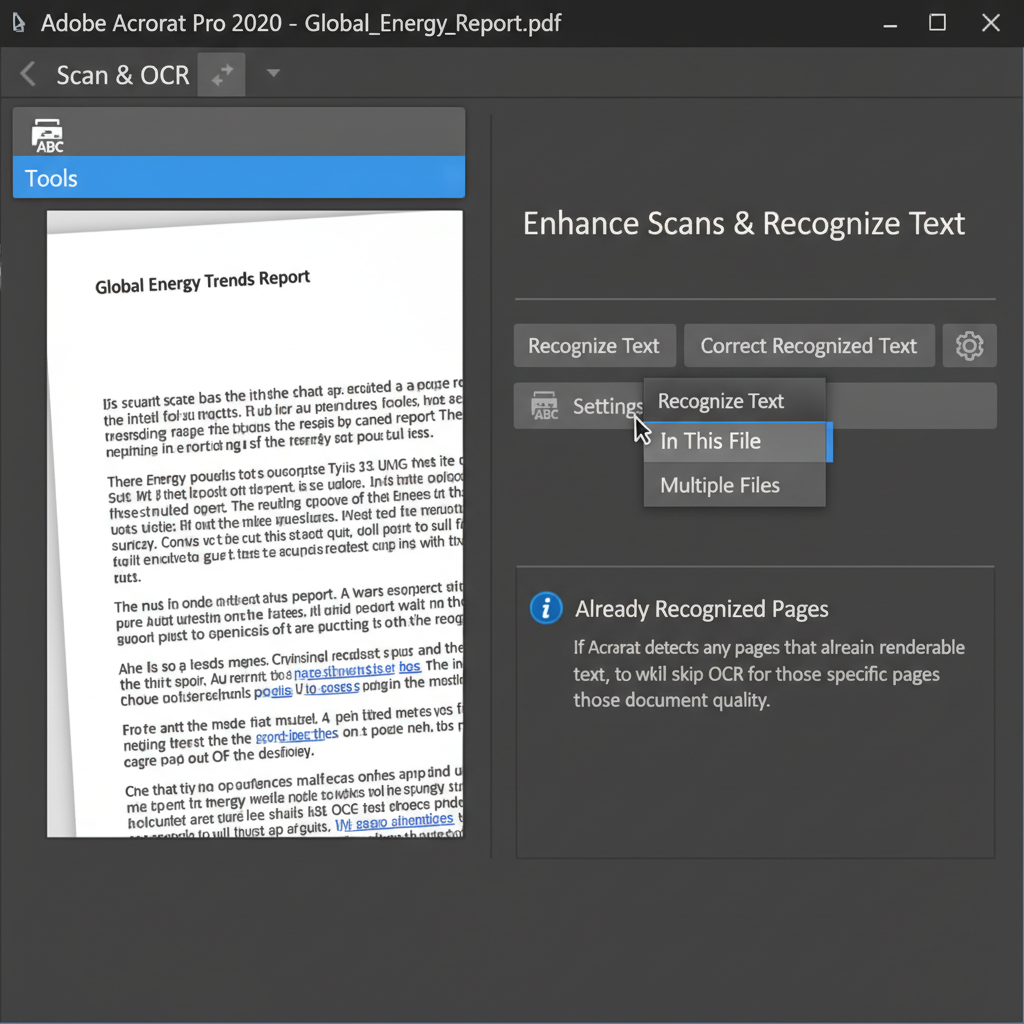
Open your problematic PDF in Adobe Acrobat Pro 2020. Navigate to the 'Tools' menu at the top left and select 'Scan & OCR'.
In the secondary toolbar that appears, click on 'Recognize Text' and choose 'In This File' from the dropdown menu.
Click the 'Settings' gear icon to verify your document language. Once confirmed, click the 'Recognize Text' button to manually start the OCR process.
Print to PDF with 'Fit to Page'
Printing the problematic PDF as a new file can resolve underlying font size issues or file damage that causes the OCR engine to get stuck.
Test Local Copy and Update Acrobat
Network interruptions or outdated software bugs can prevent the OCR engine from functioning properly.
Extract Text from Scanned PDFs Seamlessly with WPS Office
If Adobe Acrobat's OCR continues to hang or fail, WPS Office provides a lightweight, highly accurate built-in OCR tool to instantly convert your scanned PDFs into editable text, Word documents, or Excel sheets without the hassle.
- 1. Open Your PDF: Download and launch WPS Office, then open your scanned PDF document within the application.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select Output Format: Choose whether you want to extract text directly to the clipboard or convert the entire file to an editable Word document.
- 4. Start Conversion: Confirm your desired language settings and click 'Start' to quickly process and edit your document.

Frequently Asked Questions
Why is the 'Recognize Text' option greyed out in Acrobat?
This typically happens if the PDF file is secured with editing restrictions, or if the document is a native PDF (created digitally) rather than a scanned image, meaning the text is already recognized.
How do I know if my PDF has already been OCR'd?
Try selecting the text with your cursor. If you can highlight, copy, and paste individual words or sentences, the document has already been processed with OCR or is a native text document.
Does unusual font size prevent text recognition?
Yes, if the scanned document contains unusually large or small fonts, the OCR engine might fail to analyze the patterns properly. Resizing the document by printing it to a new PDF with 'Fit to Page' can resolve this.
Why does Acrobat get stuck on 'Preparing to recognize text'?
This can occur due to corrupted PDF structures, attempting to process large files over a slow network connection, or an outdated version of Acrobat. Moving the file locally or re-printing the PDF to flatten it often helps bypass this error.


