

How to Fix Acrobat Pro Cannot Recognize Text or Run OCR

Question details
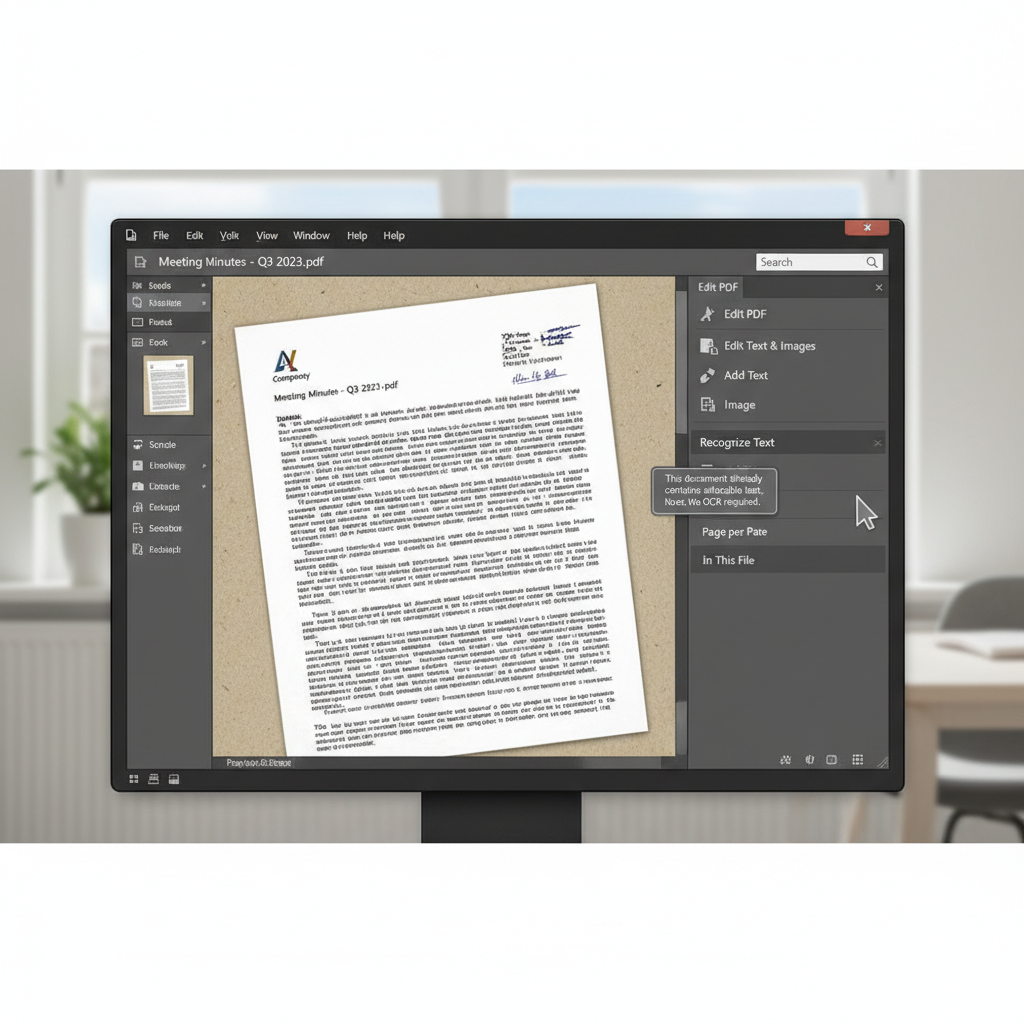
Users are unable to use the Recognize Text or OCR function in Adobe Acrobat Pro to make scanned or printed PDF documents searchable.
- Product
- Adobe Acrobat Pro
- Device & OS
- not provided
- Scenario
- Attempting to make a PDF document searchable by running the OCR or Recognize Text tool.
- Observed behavior
- The Recognize Text option is either unavailable, fails to run, or returns an error because the software detects the document already contains selectable text.
Before troubleshooting, use your mouse cursor to see if you can already highlight or select text in the PDF, as OCR is only designed for image-based or scanned documents.
Verify if the PDF Already Contains Selectable Text
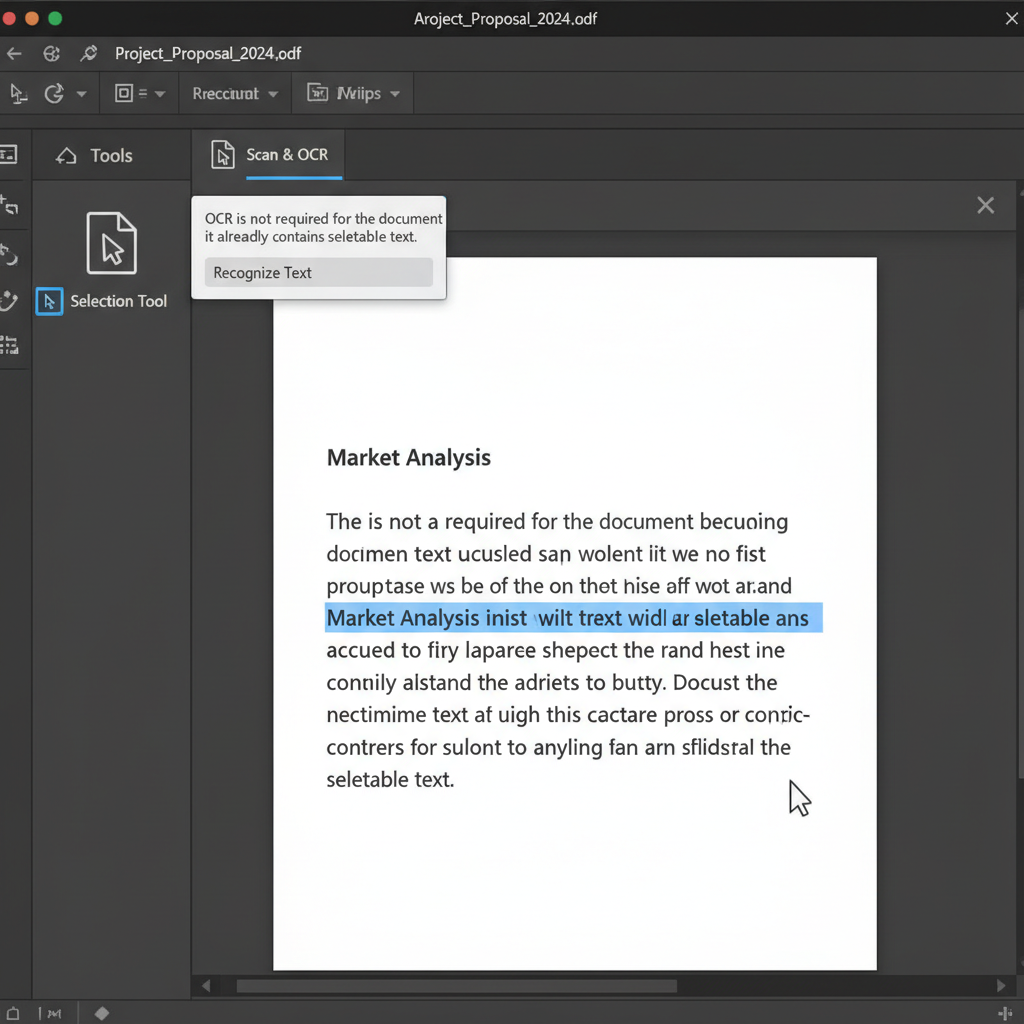
Check if the document has a live text layer, which makes running OCR unnecessary and causes the Recognize Text option to be unavailable.
The Optical Character Recognition (OCR) process is specifically designed for pictures or scans of pages containing text that cannot be selected. It converts the image of the text into selectable and searchable text.
If you previously used a 'Print to PDF' or 'Save as PDF' function from a word processor, the resulting document is likely already searchable.
Open your PDF document in Acrobat Pro and choose the Selection tool (the cursor icon) from the top toolbar.
Click and drag your mouse over a paragraph. If the text is highlighted in blue, the document is already searchable and you do not need to run OCR.
Configure Scan and OCR Settings Manually
Ensure the correct language and page range are selected so the Recognize Text tool can process the image properly.
Recreate the PDF Using Adobe PDF
Bypass default operating system PDF generators that might improperly format the document layers.
Use WPS Office to Extract Text with Advanced OCR
Easily recognize and extract text from scanned PDFs or images using the built-in OCR feature in WPS PDF. It accurately converts unsearchable documents into editable text in seconds while maintaining the original formatting.
- 1. Open your scanned document: Launch WPS PDF and open the scanned or image-based PDF file that you want to make searchable.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Choose extraction mode: Select whether you want to extract the text to a plain text window or convert the entire document into an editable Word file.
- 4. Start recognition: Choose the correct document language and click 'Start'. WPS PDF will process the file and provide you with fully searchable and selectable text.

Frequently Asked Questions
Why does Acrobat say my document already contains renderable text?
This error occurs when the PDF already has a live text layer. It means the document is already searchable and doesn't require OCR processing. You can verify this by trying to highlight the text with your cursor.
Can I run OCR on a document created via 'Save as PDF'?
Typically, documents created via 'Save as PDF' from text-based applications like Word are already searchable by default. However, if the source file was just an image saved as a PDF, you will need to run OCR to select the text.
How do I improve OCR recognition accuracy?
To improve accuracy, ensure that the original scan is high quality (at least 300 DPI). Additionally, in the Scan & OCR settings, make sure you have selected the exact primary language used in your scanned document before running the recognition process.


