

Fix Adobe Export PDF Conversion Producing Incorrect Text
Question details
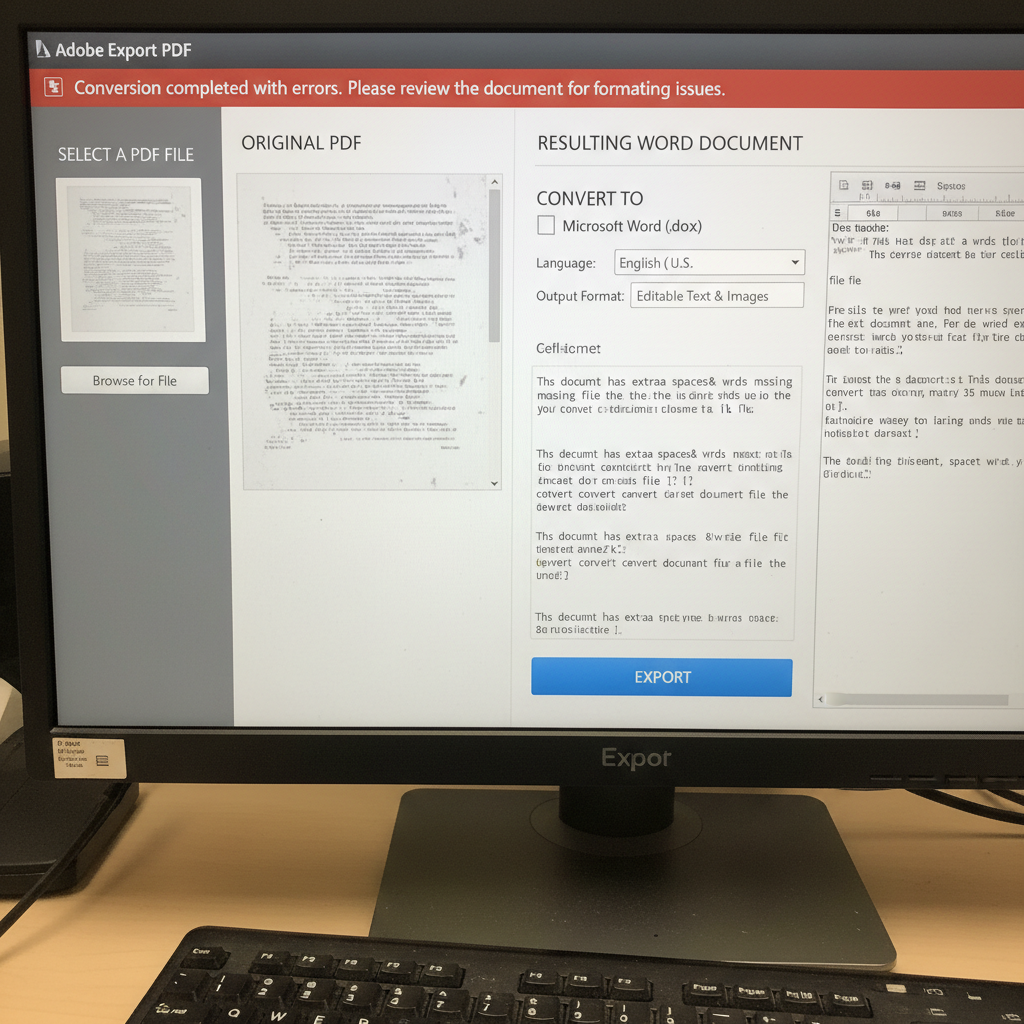
The user is experiencing incorrect text rendering, extra spaces, and missing words when converting a PDF file to a Word document.
- Product
- Adobe Export PDF
- Device & OS
- not provided
- Scenario
- Converting a scanned or complexly formatted PDF into an editable Microsoft Word document using Adobe's export tool.
- Observed behavior
- The resulting Word document contains added words, changed words, missing text, or irregular spacing that makes the document unreadable or heavily distorted.
Verify that your Adobe ID subscription is active and you are signed in. Ensure the original PDF document is clear, upright, and well-lit, as low-resolution scans significantly decrease conversion accuracy.
Run OCR Before Exporting the PDF
Use Optical Character Recognition (OCR) to convert scanned images into readable text before attempting to export the document to Word.
If your PDF is essentially an image (like a scanned document), the export tool might misinterpret the visual artifacts as letters or spaces. Running OCR forces the software to identify the text characters first, creating a much cleaner baseline for the Word conversion.
Launch Adobe Acrobat and open the problematic scanned PDF file.
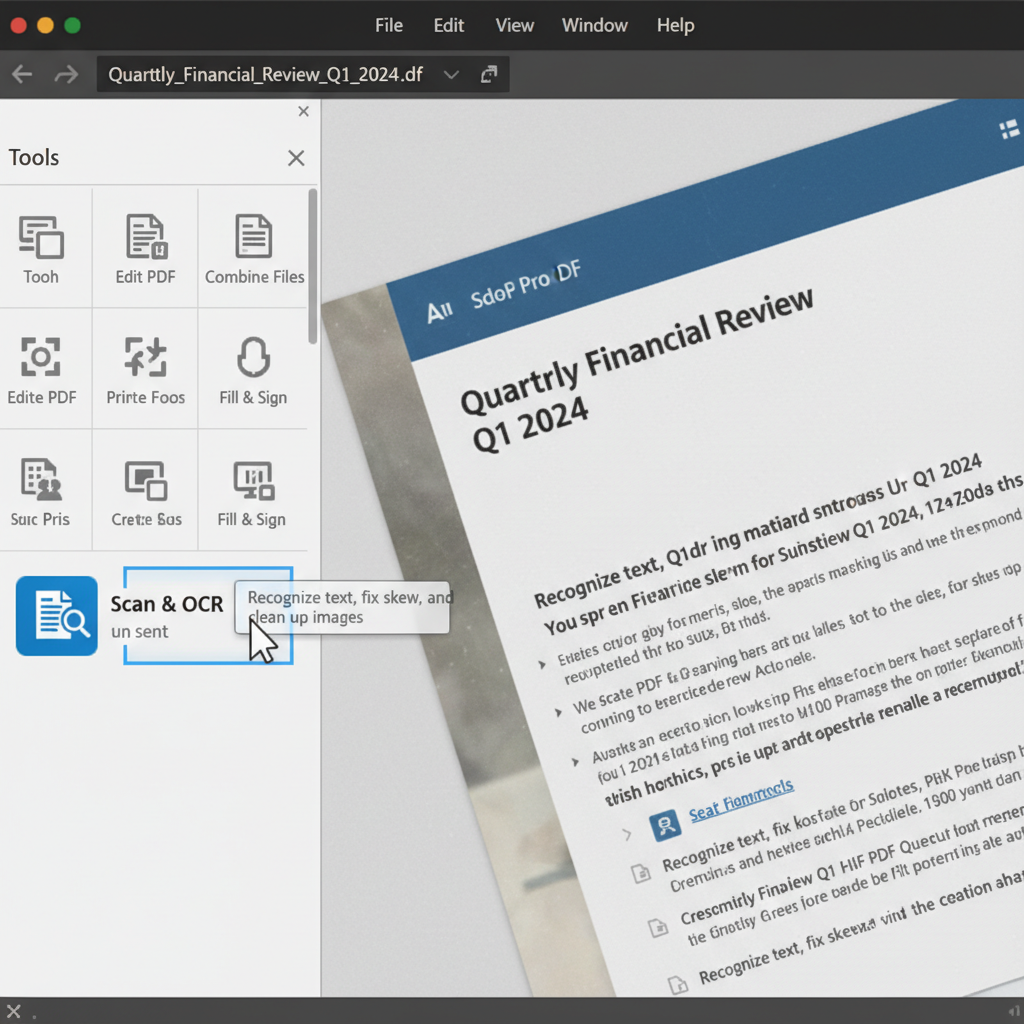
Navigate to Tools and select 'Scan & OCR' (labeled as 'Enhance Scans' in older versions).
Click on 'Recognize Text' in the toolbar and select 'In this File'.
After the OCR process is complete, go to File > Export To > Microsoft Word and check if the output text is accurate.
Convert the Document in Smaller Sections
Extract and convert complex PDFs page by page to isolate formatting issues and reduce conversion errors.
Convert PDF to Word Accurately with WPS Office
If you are struggling with messy PDF conversions, WPS Office offers a highly accurate PDF to Word converter equipped with advanced OCR capabilities. It intelligently detects text and layout, ensuring your Word document looks just like the original PDF.
- 1. Open WPS Office: Launch the WPS Office application and click on the 'PDF Edit' module.
- 2. Select PDF to Word: Open your PDF file, go to the 'Tools' tab, and click the 'PDF to Word' button.
- 3. Adjust Settings: Choose your desired page range and document language. The built-in OCR will automatically activate for scanned images.
- 4. Start Conversion: Click 'Start'. The document will be accurately converted and will open directly in WPS Writer as an editable document.
Frequently Asked Questions
Why does my converted Word document have weird formatting and extra spaces?
This happens when the original PDF uses complex layouts, overlapping text boxes, or low-quality fonts that the conversion engine misinterprets. The software attempts to recreate the exact visual position of text, which often results in excessive spacing or incorrect line breaks in Word.
How can I fix a PDF that exported with incorrect words?
Once exported, you must manually proofread and edit the Word document. To prevent this issue beforehand, improve the scan quality of the original PDF, ensure the text is upright, and run an OCR enhancement before converting.
What does it mean if Adobe Export PDF isn't working at all?
If the export fails completely, your session may have timed out or your subscription might be inactive. Sign out of Adobe Acrobat, restart the program, sign back in with your active Adobe ID, and try the export again.
Does OCR work effectively on handwritten PDFs?
Standard OCR engines struggle significantly with handwriting because they are optimized for uniform, printed text. Handwritten notes might convert as uneditable images or result in gibberish text in the final Word document.


