



Fix PDF to Word Conversion Producing Lines Instead of Text
Question details
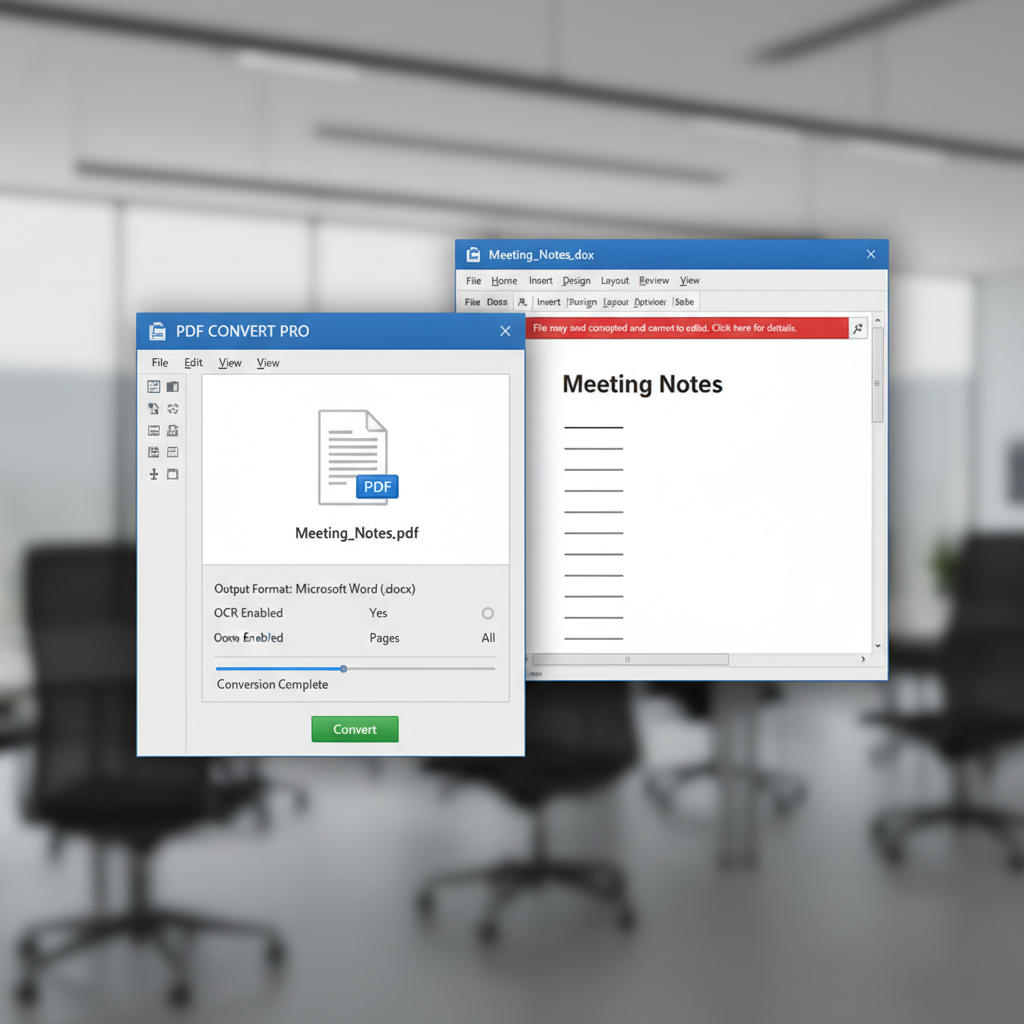
The user is attempting to convert a PDF document into Microsoft Word format, but the resulting file only contains a title and blank lines without any editable text.
- Product
- PDF Converter
- Device & OS
- not provided
- Scenario
- Exporting or converting a PDF document into an editable Word document for formatting and editing.
- Observed behavior
- The conversion completes, but the Word document fails to extract the text, outputting only blank lines or the main title.
Before troubleshooting the software, verify if your original PDF is a scanned image or a standard text-based document, as scanned files require specialized OCR technology to convert into editable text.
Verify Document Type and Apply OCR
Determine if the PDF is an image-based scan and use an OCR-capable converter to extract the text.
Standard PDF-to-Word converters only read text layers. If your PDF was created via a scanner or is image-based, there is no text layer to read, resulting in blank lines or formatting errors in Word.
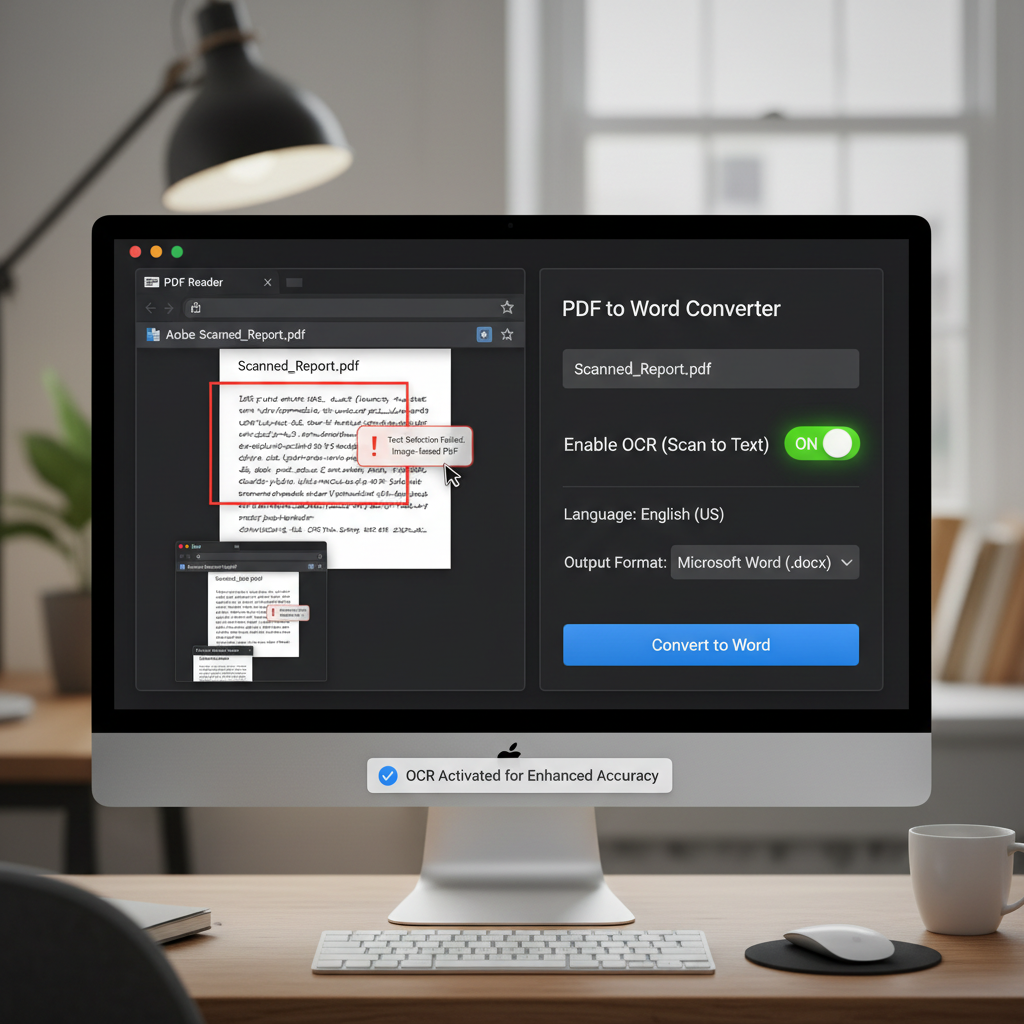
Open the original PDF in any PDF reader. Click and drag your mouse cursor over the paragraphs. If you cannot highlight individual words, your document is an image-based scanned PDF.
Switch to a PDF converter that specifically offers OCR (Optical Character Recognition) functionality. Ensure the 'Enable OCR' or 'Scan to Text' toggle is activated before starting the conversion.
To confirm the converter itself is working, try converting a simple, text-based PDF (like an exported Word document). If it converts successfully, your software is functioning, and the issue was strictly with the original scanned file.
Change Your Conversion Platform or Clear Cache
Resolve conversion engine errors by switching between web-based tools and desktop applications.
Convert Scanned PDFs to Word Flawlessly with WPS Office
WPS Office offers a robust PDF-to-Word conversion tool equipped with advanced OCR technology. It easily identifies text in scanned or complex PDFs, ensuring your resulting Word documents are fully editable and retain their original formatting without producing blank lines.
- 1. Open PDF Tools: Launch WPS Office and navigate to the 'PDF' tab on the homepage.
- 2. Select PDF to Word: Click on 'PDF to Word' from the toolkit and add your problematic PDF file.
- 3. Enable OCR: If the document is scanned, make sure to select the OCR option in the conversion settings to extract the image text.
- 4. Convert and Save: Click 'Start'. WPS Office will process the document and automatically open a fully editable Word file for you.
Frequently Asked Questions
What does it mean if my PDF is an image-based file?
An image-based PDF is essentially a digital photograph or scan of a document. It does not contain actual text data layers, which means standard converters will treat the text as a picture, often resulting in blank lines or uneditable image blocks in Word.
Why do some PDF converters fail to extract text accurately?
Converters can fail if the original PDF is damaged, highly complex with overlapping elements, or if it lacks a text layer. Without OCR (Optical Character Recognition) enabled, converters cannot 'read' images to produce editable words.
How do I know if the problem is my file or the PDF converter?
The easiest way to diagnose the issue is by testing the converter with a different, simple text-based PDF file. If the simple file converts correctly into Word, the converter is working fine, and the problem lies with the complex or scanned nature of your original document.
Is OCR technology required to convert all PDFs?
No, OCR is only required for scanned documents or image-based PDFs. If your PDF was originally created by saving a Word document or typing into a digital editor, a standard PDF converter will easily extract the text without OCR.


