



Fix PDF to Word Conversion Producing Disconnected Lines and Digits
Question details
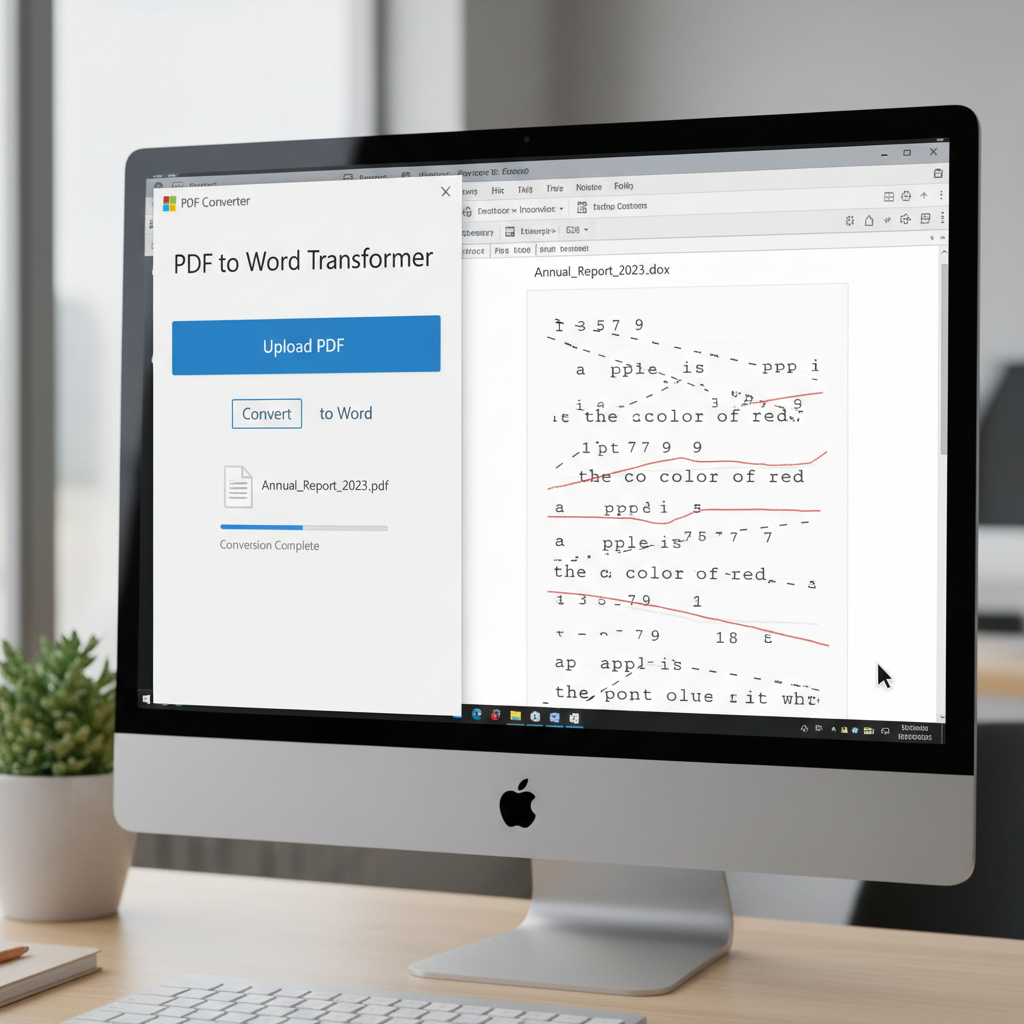
The user is experiencing severe formatting issues where converting a PDF to a Word document results in disconnected lines and numbers rather than readable text.
- Product
- PDF Converter
- Device & OS
- not provided
- Scenario
- Converting a PDF document into an editable Microsoft Word format.
- Observed behavior
- The resulting Word document displays unreadable text, broken lines, and random digits instead of the original textual content.
Open the original PDF file and try selecting a line of text with your cursor. This helps determine if the document contains selectable text or is a scanned image, which dictates the troubleshooting method.
Use OCR for Scanned or Image-Based PDFs
Standard conversion tools cannot extract text from scanned images without Optical Character Recognition (OCR) technology.
When a PDF is created using a scanner, it is essentially a photograph of a document. Converting it directly to Word without an OCR engine often forces the software to guess the layout, resulting in strange symbols, disconnected lines, or blank spaces.
Open the PDF in your PDF reader and attempt to highlight individual words. If the entire page selects as one large block, it is an image-based PDF.
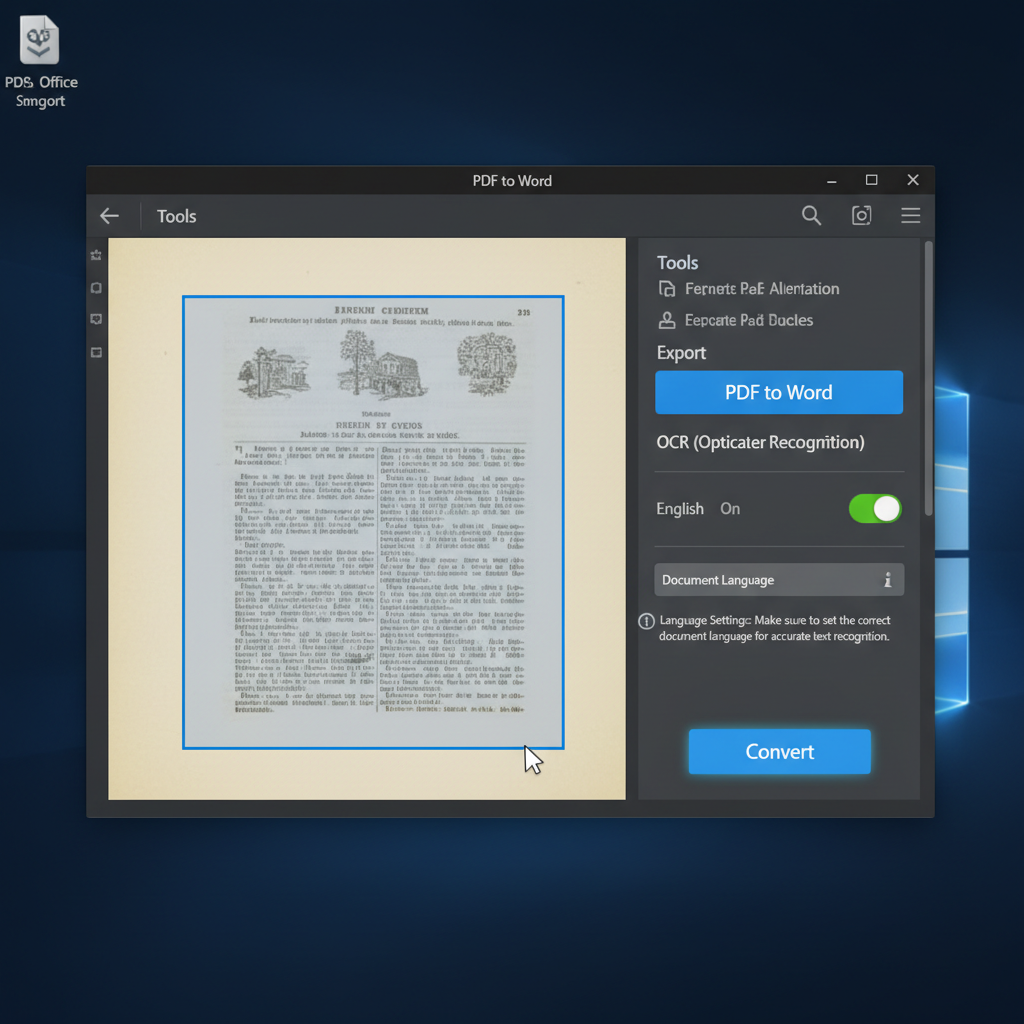
Open your PDF software (such as WPS Office or Adobe Acrobat) and navigate to the 'Tools' or 'Export' menu.
Choose 'PDF to Word' and ensure the 'OCR' (Optical Character Recognition) setting is enabled before starting the conversion.
Click 'Convert' or 'Export' to allow the software to scan and convert the image text into editable Word characters.
Check for Unsupported Fonts and Complex Layouts
Custom fonts or complex vector graphics can break during conversion if they aren't embedded properly in the original PDF.
Convert PDFs to Word Seamlessly with WPS Office
WPS Office features a powerful built-in PDF to Word converter equipped with advanced OCR technology. It accurately extracts text from scanned documents and preserves your original layout, ensuring you avoid formatting errors and disconnected lines.
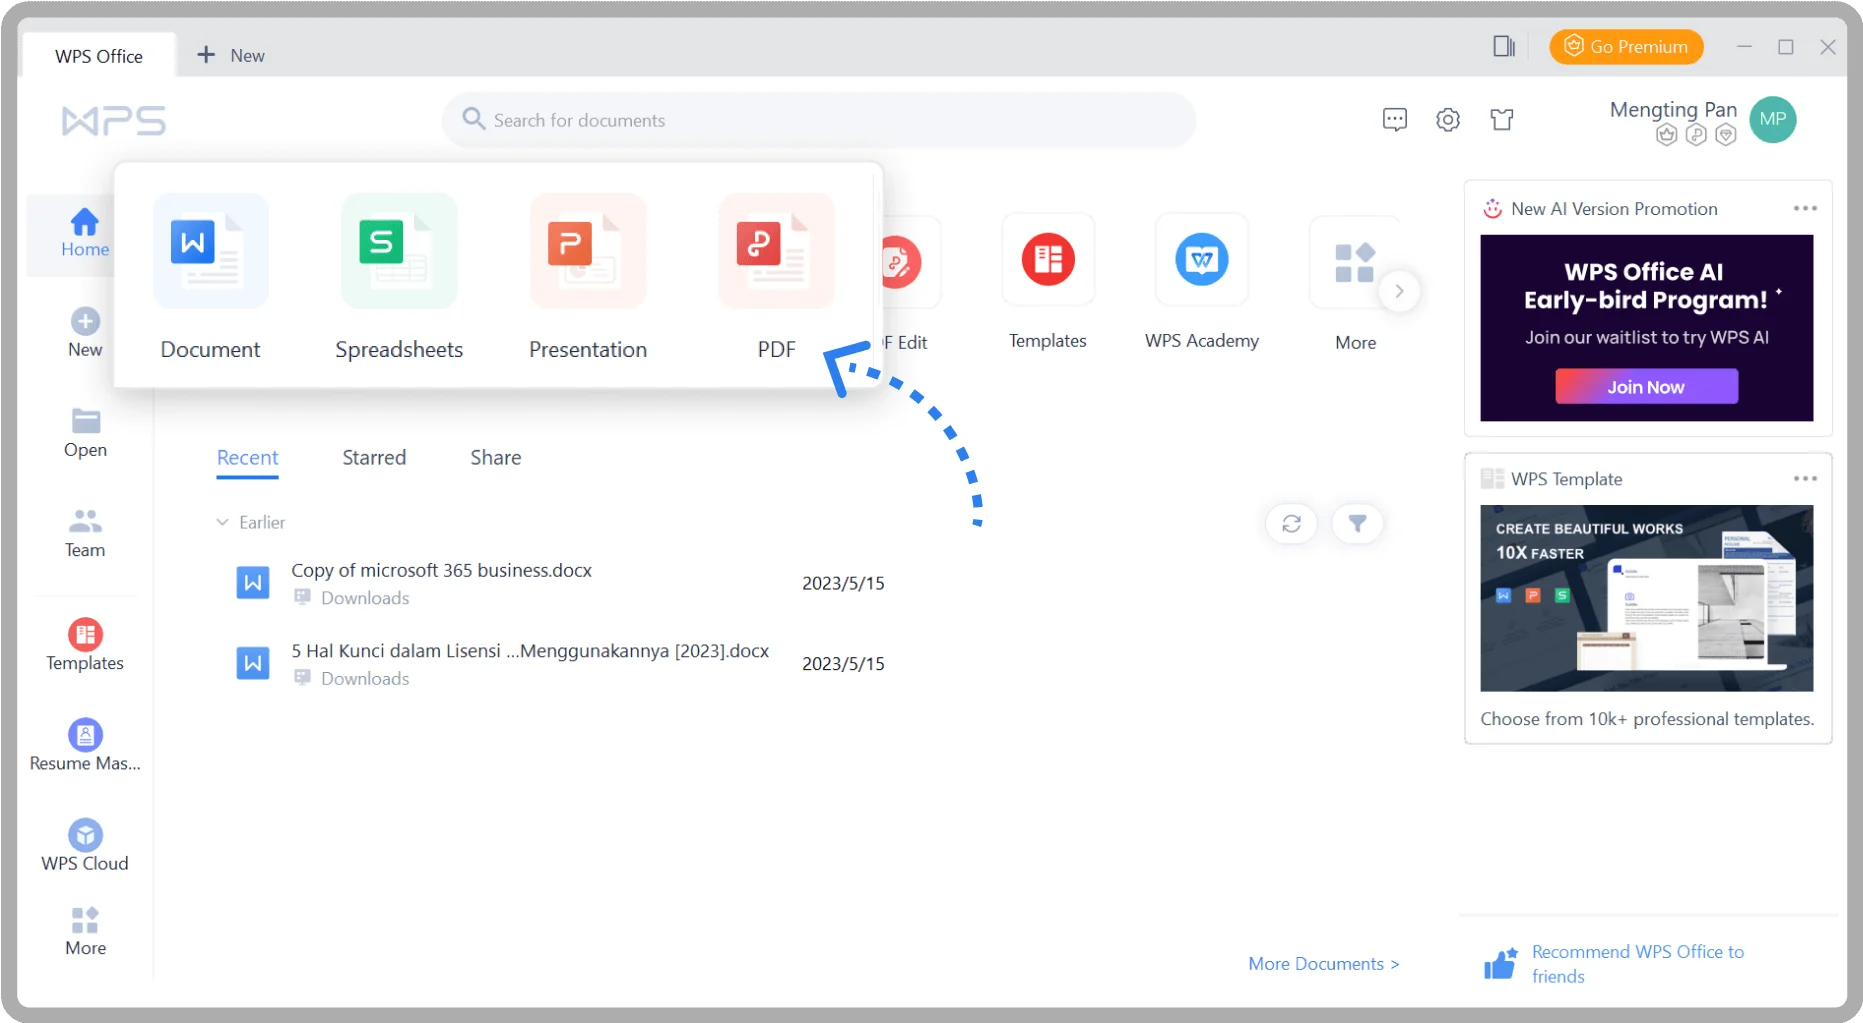
- 1. Open the PDF in WPS Office: Launch WPS Office and open the problematic PDF document.
- 2. Access the Converter tool: Go to the 'Tools' tab on the top ribbon and select 'PDF to Word'.
- 3. Enable OCR: If dealing with a scanned document, check the OCR option in the conversion dialog box.
- 4. Convert to Word: Click 'Start' to process the file and save your new, properly formatted Word document.
Frequently Asked Questions
Why does my converted Word document look like a bunch of symbols?
This usually happens when the original PDF used non-standard fonts that weren't embedded, or if the PDF is a scanned image and the conversion software attempted to translate it without utilizing Optical Character Recognition (OCR).
How can I tell if my PDF needs OCR processing?
Open the PDF in any viewer. If you cannot highlight, copy, or paste individual words using your mouse cursor, the document is an image rather than text. It requires OCR to be converted into a readable Word file.
Does WPS Office support converting scanned PDFs?
Yes, WPS Office includes advanced OCR features natively. When using the PDF to Word tool, it can read scanned PDFs and convert them into fully editable Word documents while preserving the layout.
Can password protection cause PDF conversion errors?
Yes. If a PDF has strict permission passwords or encryption applied, it can restrict text extraction algorithms. This often leads to corrupted output, blank pages, or broken lines during conversion. You must remove the permissions before converting.


