



How to Fix PDF Conversion Producing Invalid Characters or Blank Documents
Question details
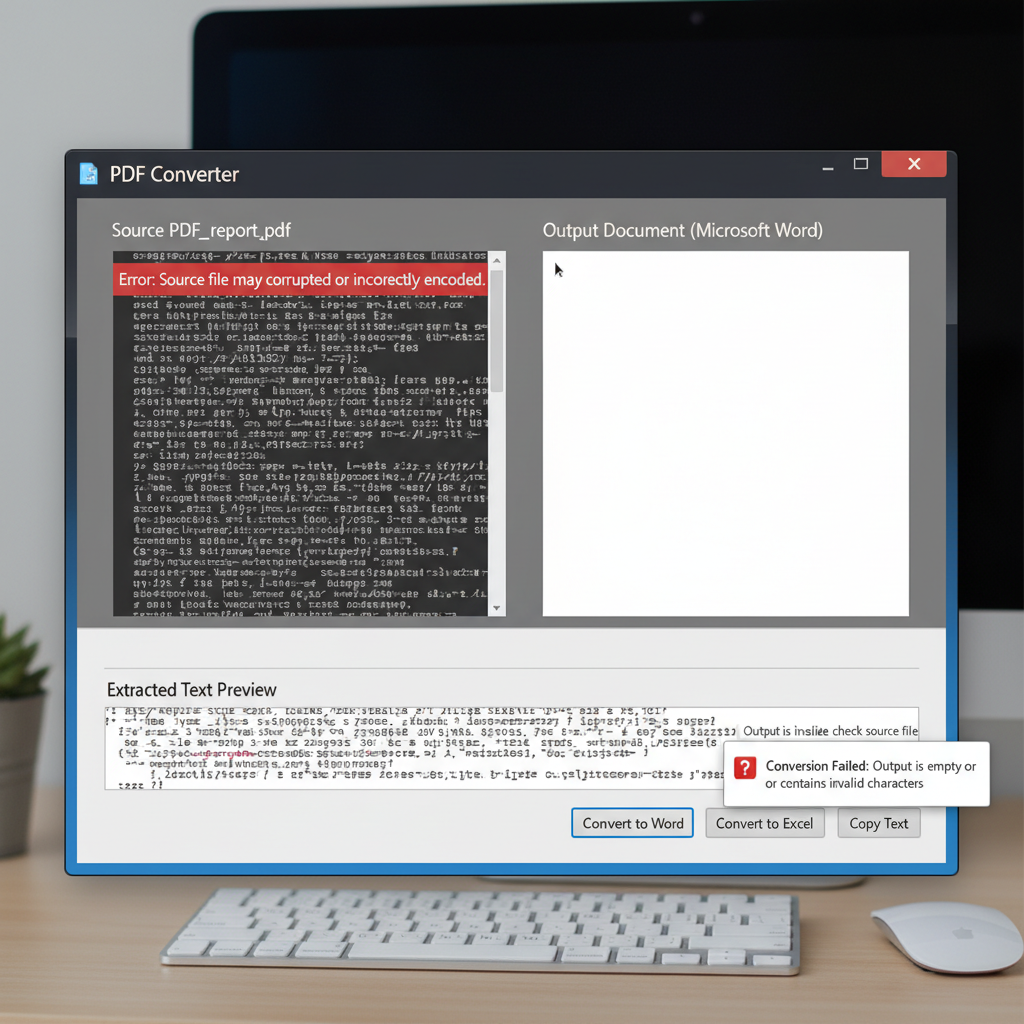
Converting a PDF or copying text from it results in a blank output document or text consisting of invalid, garbled characters.
- Product
- PDF Converter
- Device & OS
- not provided
- Scenario
- The user is attempting to convert a PDF file into another format (like Word or Excel) or copy text directly from the PDF.
- Observed behavior
- The resulting output document is completely blank, or the extracted text displays as unreadable gibberish and invalid symbols due to source corruption or faulty encoding.
Before troubleshooting, try opening the original PDF in a different PDF reader or a web browser to verify if the file displays correctly or if the original document itself is inherently corrupted.
Repair or Recreate the Corrupted Source PDF
Since invalid characters or blank pages often stem from missing font encodings or file corruption during the original PDF creation, flattening or recreating the file is the most effective fix.
If a PDF was generated using custom fonts without embedding the encoding data, standard converters will fail to translate the characters accurately. Generating a fresh, flattened copy forces the system to map standard text.
If you received the PDF from someone else, contact the sender and ask them to re-export the document from the original source file (e.g., Word or InDesign).
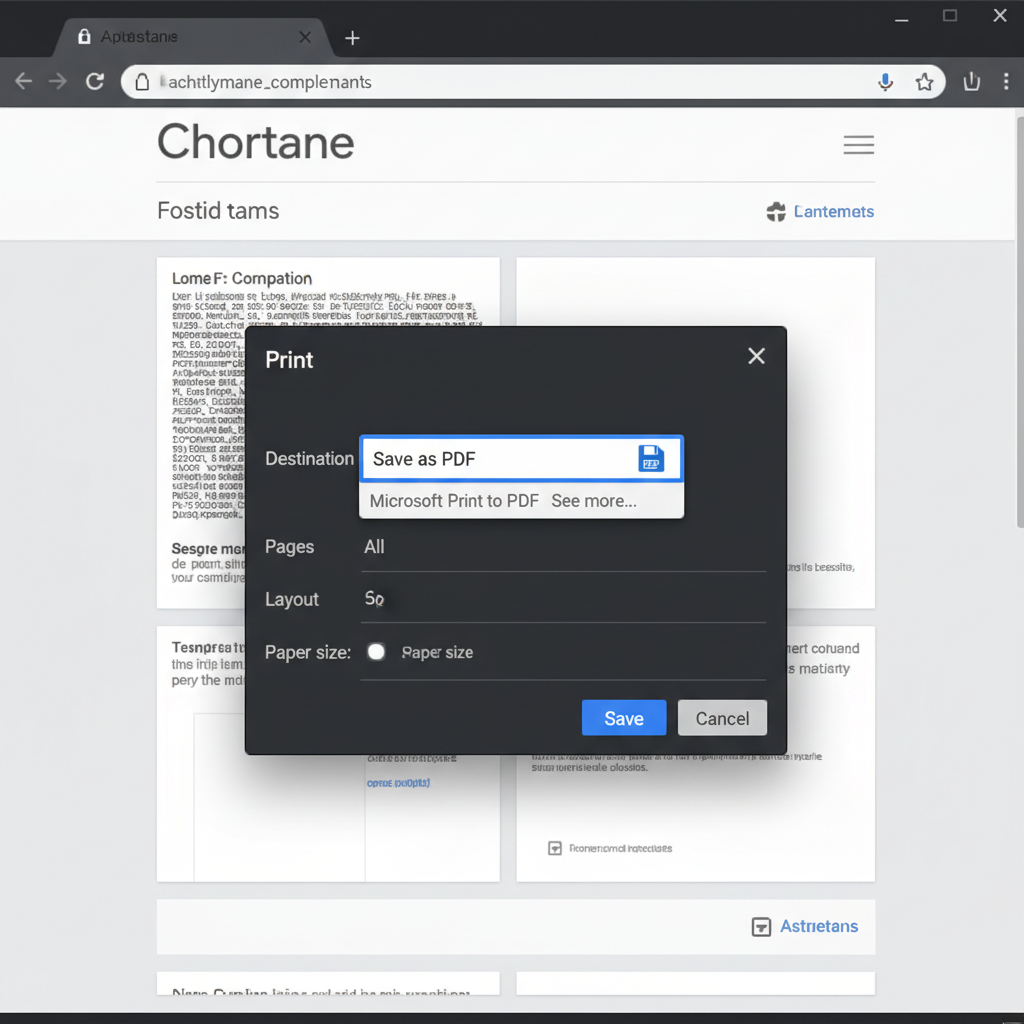
Open the problematic PDF in a web browser like Chrome or Edge. Press Ctrl+P (or Cmd+P on Mac) to open the print dialog.
Change the printer destination to 'Save as PDF' or 'Microsoft Print to PDF' and save the new file to your computer. This action flattens the file and frequently repairs underlying encoding errors.
Open the newly created PDF and attempt the conversion or text-copying process again.
Use Optical Character Recognition (OCR)
If the internal text encoding is completely broken but the document is visually readable, using OCR will bypass the broken code by reading the visual text directly.
Ensure Accurate PDF Conversions with WPS Office
WPS Office features a powerful, built-in PDF toolkit equipped with advanced OCR technology. It seamlessly bypasses broken encodings and minor file corruptions, ensuring your converted documents are completely accurate and editable.
- 1. Download WPS Office: Download and install WPS Office for free from the official website.
- 2. Open your PDF: Launch WPS Office and open the problematic PDF document.
- 3. Access PDF tools: Navigate to the 'Tools' tab on the top ribbon and select 'PDF to Word' or your desired format.
- 4. Enable OCR: If the document is poorly encoded, check the 'OCR' option to ensure the text is visually scanned and accurately translated.
- 5. Convert and save: Click 'Convert'. Once finished, your new document will open automatically without blank pages or invalid characters.
Frequently Asked Questions
Why does copied text from my PDF paste as weird symbols or gibberish?
This usually happens when the original PDF was created without embedding the proper font encoding (or used custom subset fonts). While your PDF reader knows how to draw the shapes of the letters, the underlying map connecting those shapes to actual text characters is broken.
Can a blank PDF conversion be fixed without asking for the original file?
Yes. You can often bypass the issue by 'flattening' the PDF—using the 'Print to PDF' feature in your web browser or system print dialog to create a fresh copy. Alternatively, using an OCR tool will treat the document as an image and extract the text visually.
Does standard PDF to Word conversion work on scanned documents?
Standard conversion only extracts underlying digital text. If your PDF is a scanned image, a standard converter will output a blank page or a document containing only images. You must use OCR (Optical Character Recognition) software to recognize and extract editable text from scanned PDFs.


