

How to Fix PDF Text Not Searchable or Replaceable Due to Font Encoding

Question details
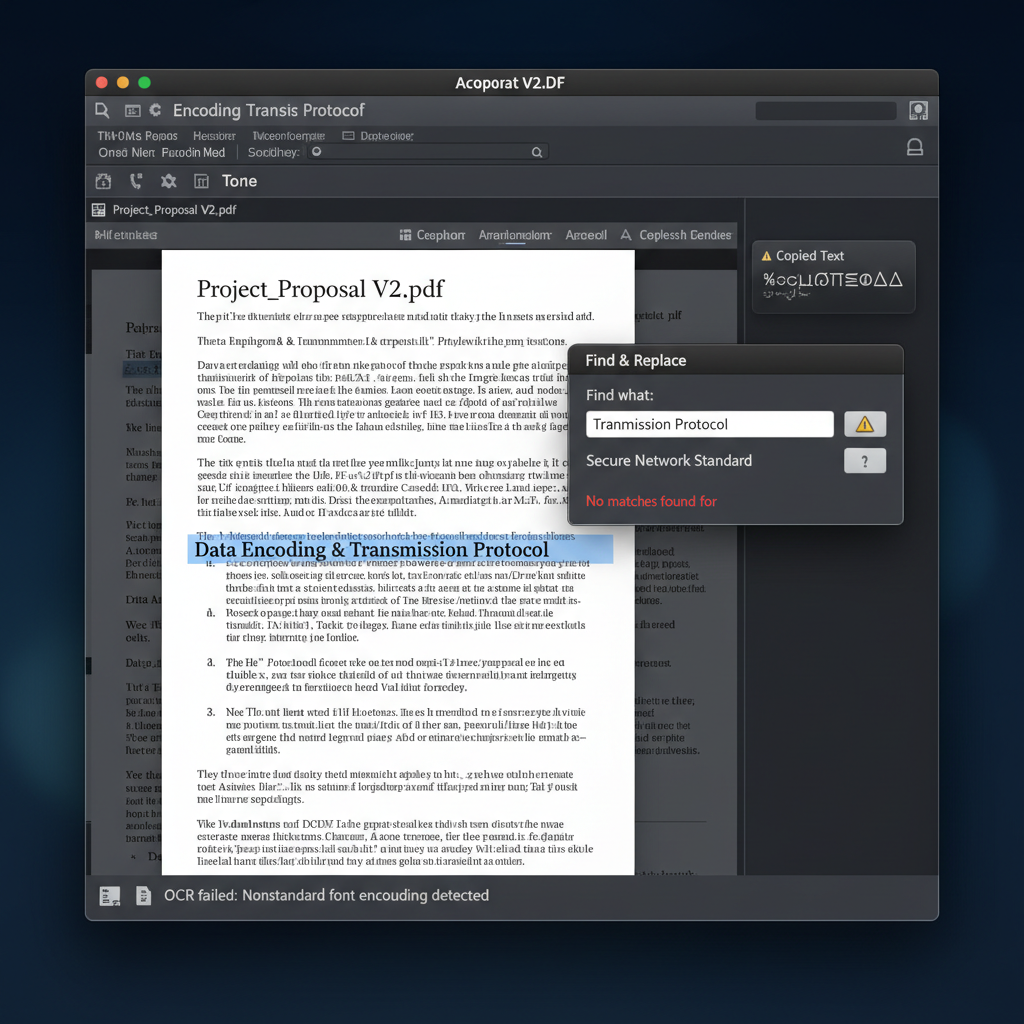
The user is unable to search, copy, or replace selectable text in an InDesign-generated PDF due to custom font encodings and multiple partially embedded font subsets.
- Product
- Device & OS
- not provided
- Scenario
- Attempting to search, copy, or replace specific text content within a large PDF document.
- Observed behavior
- Text can be visually selected, but the search and replace functions fail, copied text is garbled, and OCR produces inaccurate results due to nonstandard character mappings.
Verify if you have access to the original authoring file (such as the InDesign document), as re-exporting the PDF is the most reliable way to resolve deep-rooted font encoding errors.
Re-export the PDF from the Original Source File
The most effective way to resolve severe font encoding issues is to bypass the corrupted PDF entirely and generate a new one with correct font embedding settings.
Incorrect or nonstandard character mappings cannot easily be fixed by modifying the PDF or extracting embedded fonts. Generating a fresh export ensures the text layer is built correctly.
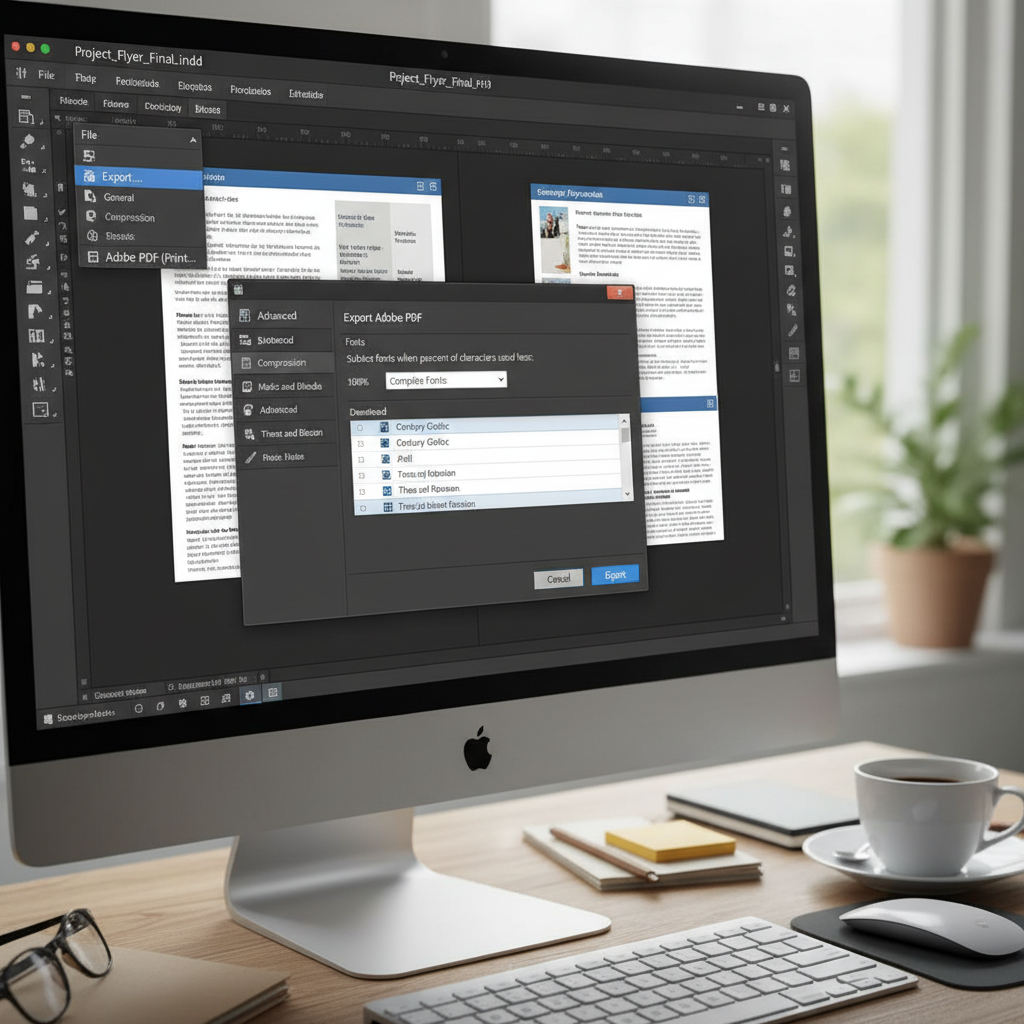
Launch Adobe InDesign (or the software originally used to create the file) and open the source document.
Ensure all fonts used in the document (such as Century Gothic) are properly installed and active on your local operating system.
Navigate to 'File' > 'Export' and choose 'Adobe PDF (Print)' as your output format.
In the export settings, go to the 'Advanced' tab and ensure font subsetting is set properly to allow standard text encoding.
Save the new PDF, open it in your PDF reader, and test the 'Find' tool to ensure the text is now searchable.
Use OCR to Re-encode the Text
If you cannot obtain the source file, use Optical Character Recognition (OCR) to read the visual text and create a brand new, searchable text layer.
Recreate the Document by Extracting Elements
When OCR yields inaccurate results, extracting raw text and images to rebuild the document manually may be the only fallback.
Fix PDF Text Issues with WPS Office
WPS PDF provides powerful built-in OCR and conversion tools to help you reconstruct documents or make unsearchable PDFs fully searchable and editable.
- 1. Open your PDF: Launch WPS Office and open the unsearchable PDF document using WPS PDF.
- 2. Use the OCR Tool: Navigate to the 'Tools' tab and click on 'OCR' to recognize the text on the page.
- 3. Convert to Editable Format: Alternatively, select 'PDF to Word' to convert the document, allowing you to easily find, replace, and edit the text.
- 4. Save as a New PDF: Once your edits are complete, export the document back to PDF format with fully searchable text.

Frequently Asked Questions
Why can I select text in my PDF but not search or copy it?
This happens when the PDF uses a custom or corrupted font encoding. The PDF viewer recognizes that a character exists at that specific location (which allows you to highlight it), but it lacks the correct mapping to translate that character into a readable letter or symbol for search and copy functions.
Will extracting and installing the embedded fonts fix the text search issue?
Usually, no. If the embedded font subsets use incorrect character mappings or nonstandard encoding, installing those exact fonts locally will not magically restore the searchable text layer in the existing PDF. The internal mapping within the file is already flawed.
How does font subsetting cause PDF encoding problems?
To save file space, PDF creation software often embeds only a 'subset' of a font, which includes just the specific characters used in the document. If a document embeds multiple subsets of the same font with conflicting encodings, PDF editors struggle to read, search, or replace the text accurately.


