

Fix PDF Text That Is Readable but Not Searchable (Copies as Gibberish)

Question details
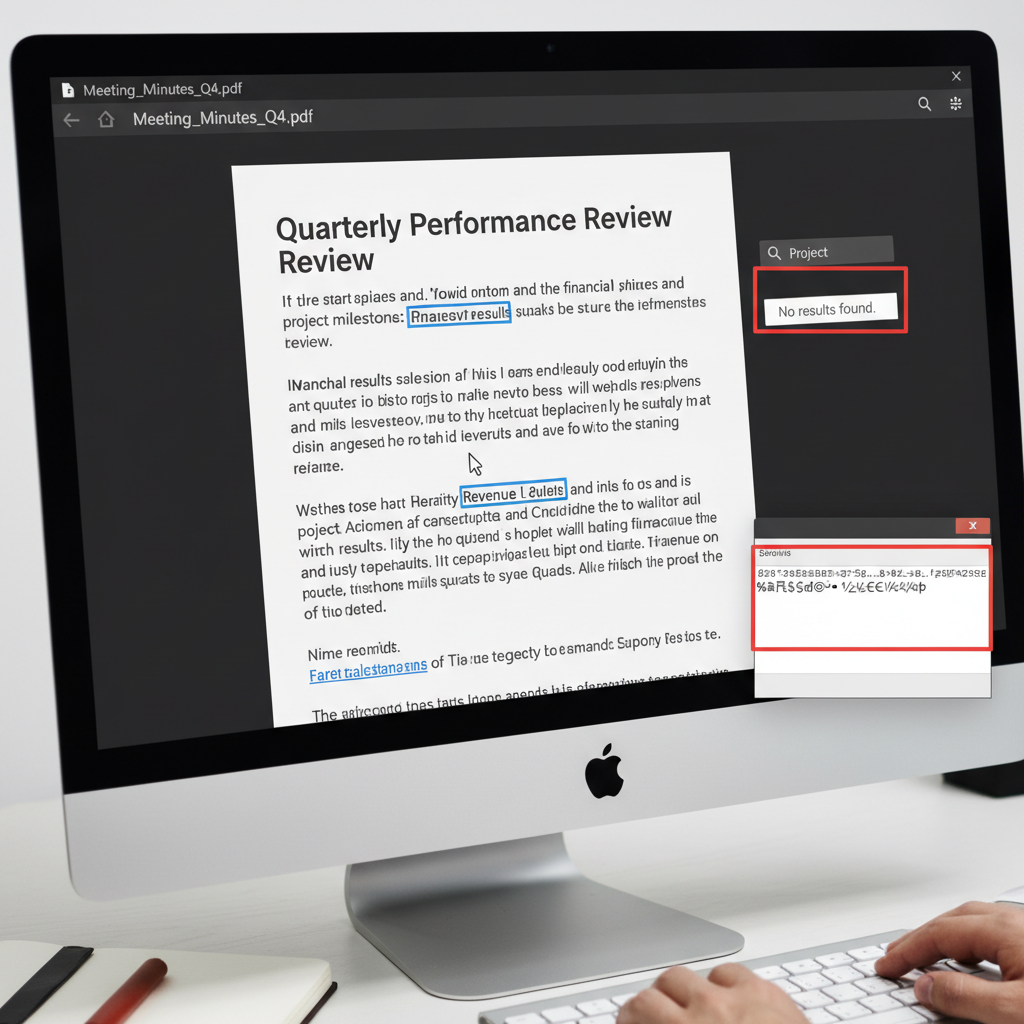
The user is experiencing an issue where text within a PDF is visible and readable, but cannot be found using the search function, and copying the text results in gibberish.
- Product
- Device & OS
- not provided
- Scenario
- Attempting to search for specific words or copy text from an existing PDF document.
- Observed behavior
- The text appears normal on the screen but is unsearchable. When copied and pasted, it outputs corrupted or gibberish characters because the document contains an invalid or incomplete character mapping.
Ensure you have a backup of the original PDF file before applying text recognition or converting document formats to prevent any accidental data loss.
Run OCR to Rebuild the Text Layer
Using Optical Character Recognition (OCR) is the most effective way to replace improperly encoded text with a fresh, searchable text layer.
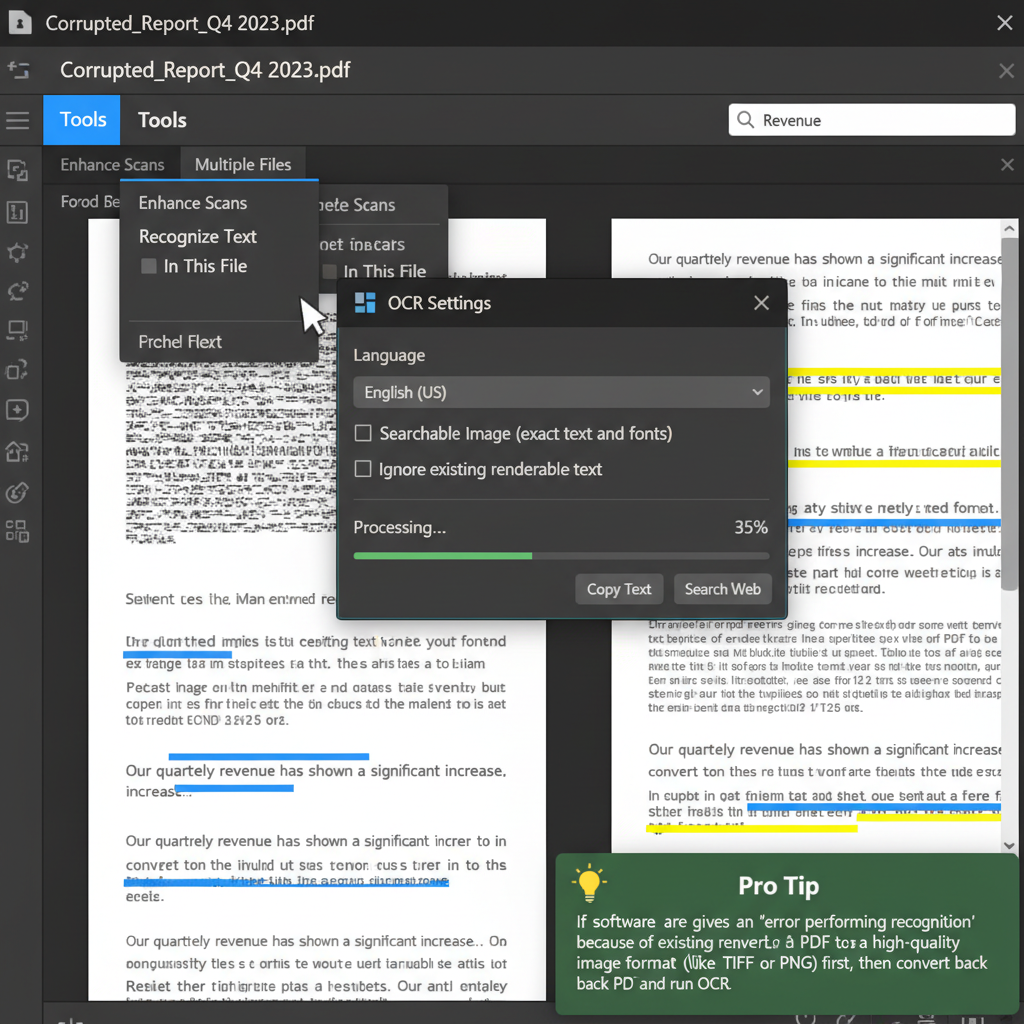
When a PDF has 'renderable text' with broken encoding, standard text tools fail. Running OCR forces the software to analyze the visual shapes of the words and generate a brand-new underlying text layer with standard character mapping.
Open the problematic PDF in a capable PDF editor. Navigate to the 'Tools' or 'Edit' menu and select 'Recognize Text' or 'OCR'.
Choose the appropriate language for the document. If your software allows, select the option to 'Searchable Image' or force it to ignore existing renderable text.
Initiate the OCR process. Once completed, press Ctrl+F (or Cmd+F on Mac) to search for a word, or highlight and copy a sentence to verify it is no longer gibberish.
Recreate the PDF from the Original Source Document
If you have access to the original Word, Excel, or text file, exporting a fresh PDF often bypasses encoding issues entirely.
Fix Unsearchable PDF Text Easily with WPS PDF
WPS Office includes a powerful, lightweight PDF editor with built-in Optical Character Recognition (OCR). You can quickly convert improperly encoded, unsearchable PDFs into fully readable documents without relying on expensive software.
- 1. Open your PDF: Launch WPS Office and open your problematic PDF file.
- 2. Access the OCR feature: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Process the text: Choose the 'Extract Text' or 'Convert to Word' option depending on whether you want to fix the PDF or export it for editing. Click confirm to start scanning.
- 4. Save the searchable file: Once the recognition process finishes, save your newly corrected and searchable document.

Frequently Asked Questions
Why does copied PDF text turn into strange characters or gibberish?
This happens when a PDF contains 'renderable text' with an invalid or missing character mapping (font encoding). While the visual shapes of the letters are drawn correctly on your screen, your computer does not know which actual Unicode characters they represent. When you copy it, the system guesses or outputs raw placeholder codes, resulting in gibberish.
Can I fix this issue if I don't have the original Word document?
Yes. You can fix this by using a PDF editor that features OCR (Optical Character Recognition). The OCR tool scans the visual shapes of the text on the page and creates a completely new, properly encoded text layer over it, allowing you to search and copy normally.
Why does the search function fail when I can clearly read the words?
The search function relies on the document's underlying invisible text data layer, not the visual appearance. If the document's font encoding is broken, the search tool only 'sees' unrecognizable symbols instead of the words you are reading.
How can I prevent text encoding issues when creating my own PDFs?
When exporting documents to PDF from programs like Microsoft Word, use the built-in 'Save as PDF' or 'Export' function rather than 'Print to PDF' through older third-party virtual printers. Additionally, always ensure the option to embed fonts is checked in your PDF export settings.


