

Fix PDF to Word Conversion Showing Unreadable Letters and Numbers
Question details
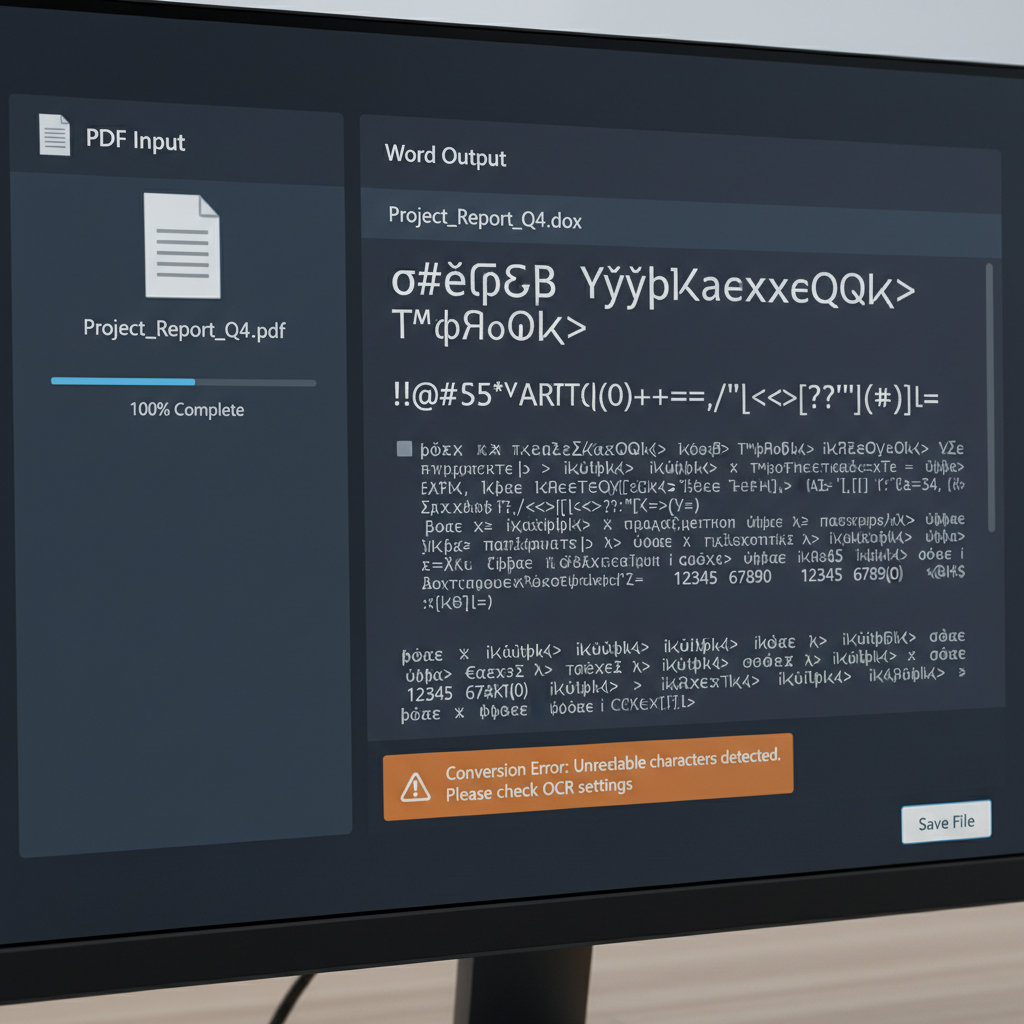
Converting a PDF document to Microsoft Word results in a file filled with random letters, numbers, or gibberish text instead of readable content.
- Product
- PDF to Word Converter
- Device & OS
- not provided
- Scenario
- Converting a PDF file to a Word document for text editing and reuse.
- Observed behavior
- The output Word document displays unreadable characters, random letters, and numbers rather than the original document's text, often due to OCR misinterpretation or font encoding failures.
Check whether your original PDF contains standard selectable text or if it is a scanned image by trying to highlight a few words in your PDF viewer.
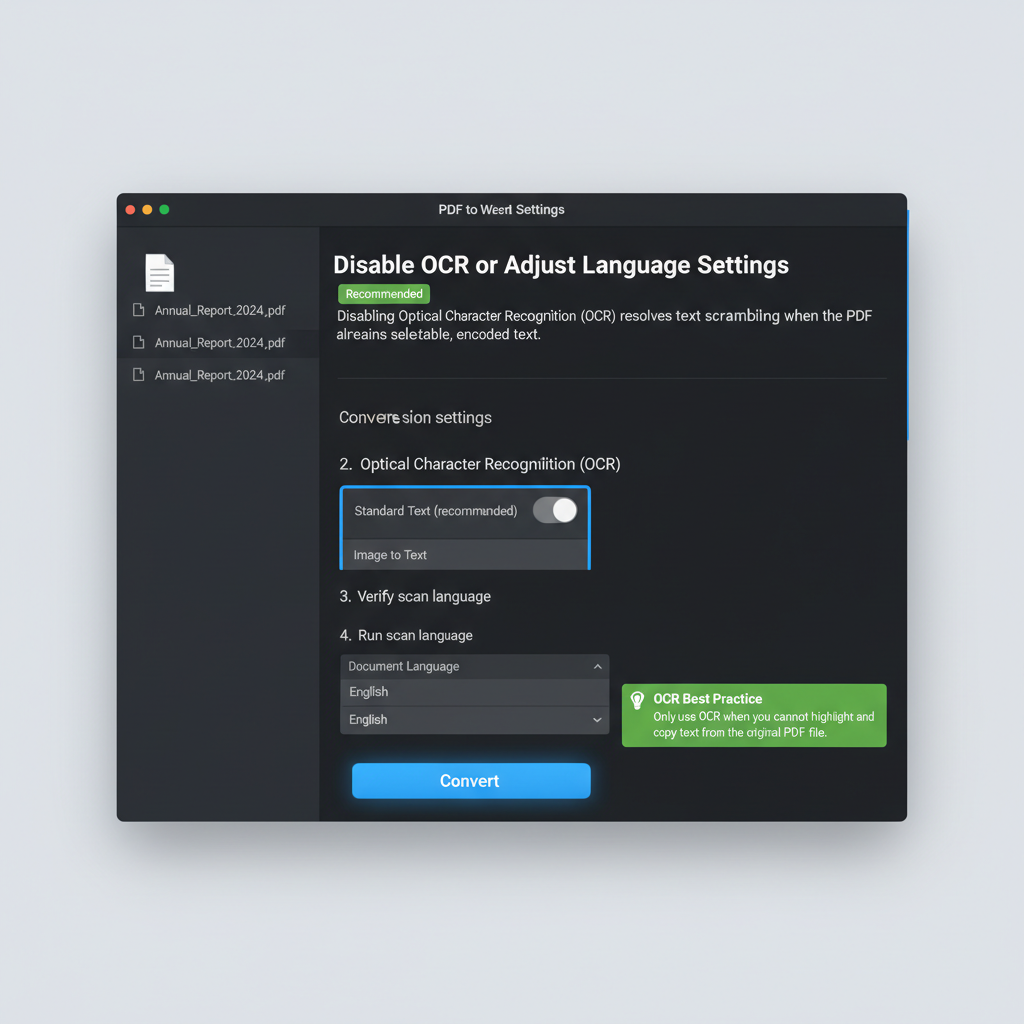
Disable OCR or Adjust Language Settings
Disabling Optical Character Recognition (OCR) resolves text scrambling when the PDF already contains selectable, encoded text.
Many PDF converters automatically run OCR on documents, which can misinterpret standard text as images and produce random characters. Disabling it forces the converter to read the embedded text directly.
Launch your PDF to Word converter tool and look for a 'Settings', 'Options', or 'Advanced' gear icon before initiating the conversion.
Locate the 'Optical Character Recognition' (OCR) checkbox or toggle and disable it. If your software prompts you, choose to convert as 'Standard Text' instead of 'Image to Text'.
If your original document is actually a scanned image that requires OCR, leave it enabled but ensure the correct document language (e.g., English) is selected in the OCR dropdown.
Click 'Convert' or 'Start' to run the conversion process again and open the resulting Word file to check the text.
Re-save or Print to PDF to Fix Encoding
If the PDF uses unusual fonts or broken character encoding, 'printing' it to a new PDF can flatten the file and resolve subsequent conversion errors.
Use WPS Office for Flawless PDF to Word Conversions
WPS Office features an advanced, built-in PDF to Word converter that preserves original formatting, handles scanned documents with high-accuracy OCR, and ensures standard font encoding to prevent unreadable text issues.
- 1. Access the PDF toolkit: Open WPS Office and navigate to the 'PDF' tab on the main interface to access the PDF toolkit.
- 2. Select PDF to Word: Click on the 'PDF to Word' icon and click 'Add Files' to import the PDF document you wish to convert.
- 3. Configure OCR settings: Choose your desired output format (.docx). If your document is scanned, click 'Settings' to enable OCR and select the correct document language.
- 4. Start conversion: Click 'Start' to convert your document. Once finished, it will automatically open in the WPS Writer for immediate editing.

Frequently Asked Questions
Why does my converted Word document look like gibberish?
This typically happens due to missing embedded fonts in the original PDF, corrupted character encoding, or incorrect Optical Character Recognition (OCR) settings misinterpreting the visual shapes of letters.
How do I know if I should use OCR for my PDF?
Try selecting the text in your original PDF. If you can highlight individual words and copy them, you do not need OCR. If the text acts like a flat photograph and cannot be selected, you must enable OCR to extract the text.
Can a password-protected PDF cause unreadable text during conversion?
Yes, if a PDF has restrictions on copying or extracting content, converters might output blank pages or random characters to enforce the security. You must unlock or remove the password protection before converting.
What should I do if my scanned PDF conversion still fails after enabling OCR?
Ensure your scanned PDF has a high resolution (at least 300 DPI) and good contrast. Blurry, faint, or low-quality scans cannot be accurately processed by OCR, resulting in random letters and numbers.


