

How to Fix PDF to Word Conversion Resulting in Gibberish Text
Question details
The user is experiencing garbled or unreadable text when converting a PDF file to a Word document, despite the formatting and graphics appearing correctly.
- Product
- PDF Converter
- Device & OS
- not provided
- Scenario
- Converting a PDF document into an editable Word file for modification.
- Observed behavior
- The text in the resulting Word document appears as gibberish or weird symbols, likely due to font incompatibility or incorrect Optical Character Recognition (OCR) processing.
Check if the original PDF contains custom or restricted fonts, and try simply changing the font of the gibberish text in Word to a standard font like Arial before attempting reconversion.
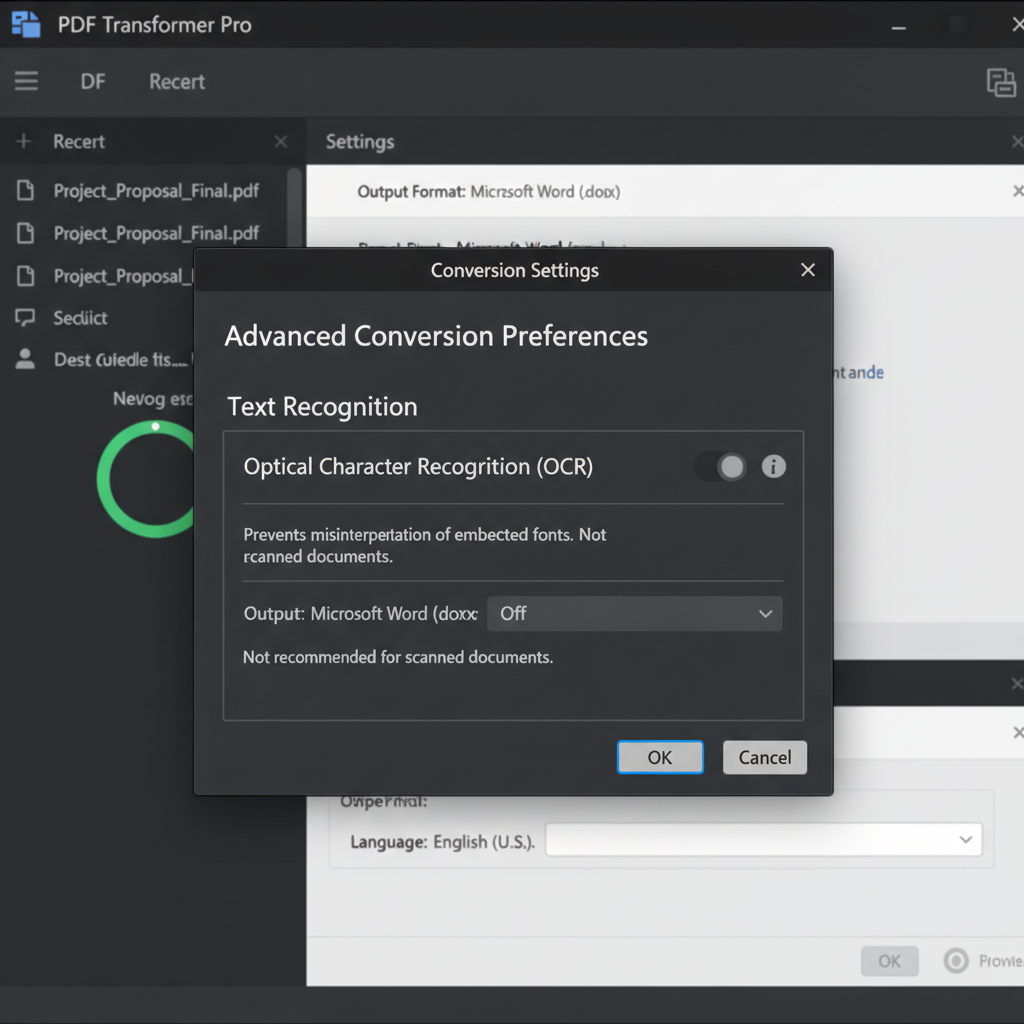
Disable OCR (Optical Character Recognition) During Conversion
Turning off OCR prevents the converter from misinterpreting embedded or custom fonts as incorrect characters, which is a common cause of gibberish text.
When converting a standard text-based PDF (not a scanned image), OCR might unnecessarily try to recognize character shapes. If the PDF has complex embedded fonts, this process can fail and produce garbled symbols.
Launch your PDF conversion software (such as Adobe Acrobat or WPS Office) and open the 'Export PDF' or 'PDF to Word' tool.
Before starting the conversion, click on the settings, options, or gear icon to open the advanced conversion preferences.
Locate the 'Recognize Text' or 'OCR' option and toggle it off. Ensure the converter is set to process standard text only.
Proceed with the conversion to Word and open the new document to verify if the text now renders correctly.
Recreate the Document from the Original Source File
If the PDF uses severely corrupted or strictly embedded fonts, converting it may consistently fail. Re-exporting from the original file is the most reliable workaround.
Convert PDF to Word Accurately with WPS Office
WPS Office offers a robust PDF to Word converter that intelligently handles embedded fonts and complex layouts, significantly reducing the chances of gibberish text during conversion.
- 1. Open the PDF to Word tool: Launch WPS Office and click on 'PDF to Word' in the homepage toolkit or under the 'Tools' tab.
- 2. Add your PDF file: Drag and drop the problematic PDF file into the conversion window, or click 'Add Files' to select it.
- 3. Set output preferences: Select '.docx' as your desired output format and choose a destination folder for the converted file.
- 4. Convert the document: Click 'Start' to begin the conversion. WPS Office will intelligently map the fonts, and the accurately rendered Word document will open automatically.
Frequently Asked Questions
Why does my PDF turn into weird symbols when converted to Word?
This usually happens when the original PDF uses custom, embedded, or unsupported fonts. The conversion software attempts to map these fonts to standard Word fonts but fails, resulting in garbled text or wingdings-style symbols.
Can I fix gibberish text in Word after the conversion is done?
Sometimes you can. Try highlighting the gibberish text in Word and changing the font from the drop-down menu to a standard system font like Arial or Calibri. If the character encoding wasn't destroyed during conversion, the text may instantly become readable.
Does OCR cause or fix garbled text in PDF conversions?
It depends on the file. For scanned images, OCR is necessary to extract readable text. However, for a standard text-based PDF with embedded fonts, OCR might misinterpret the vector shapes of the letters, causing gibberish. Toggling the OCR setting off often resolves the issue for text-based PDFs.


