

How to Fix Unicode Text Encoding and Copy-Paste Problems in PDFs

Question details
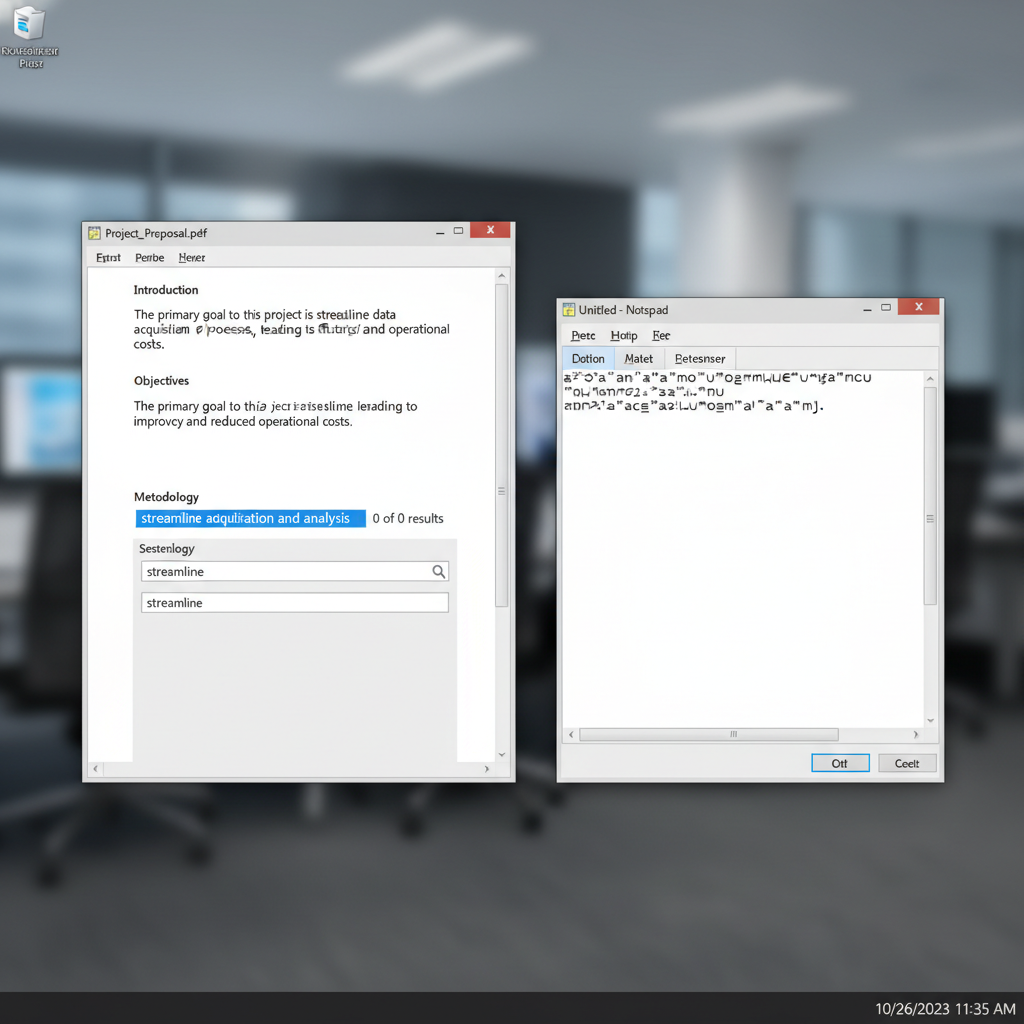
Users are unable to copy and paste text accurately from a PDF or search within it due to broken underlying character mapping, despite the text displaying correctly on the screen.
- Product
- Device & OS
- not provided
- Scenario
- Copying text from a PDF document to a standard text editor (like Notepad) or using the search function within the PDF.
- Observed behavior
- Text appears visually correct in the PDF, but when copied and pasted, it produces incorrect characters, gibberish, or replacement boxes. In-document text searches also fail.
Ensure you have access to the original source document (such as the Microsoft Word file), as the most effective fix involves correcting the fonts before recreating the PDF.
Regenerate the PDF using Genuine OpenType Unicode Fonts
Recreating the PDF from the source file using official fonts prevents invalid ToUnicode character map generation.
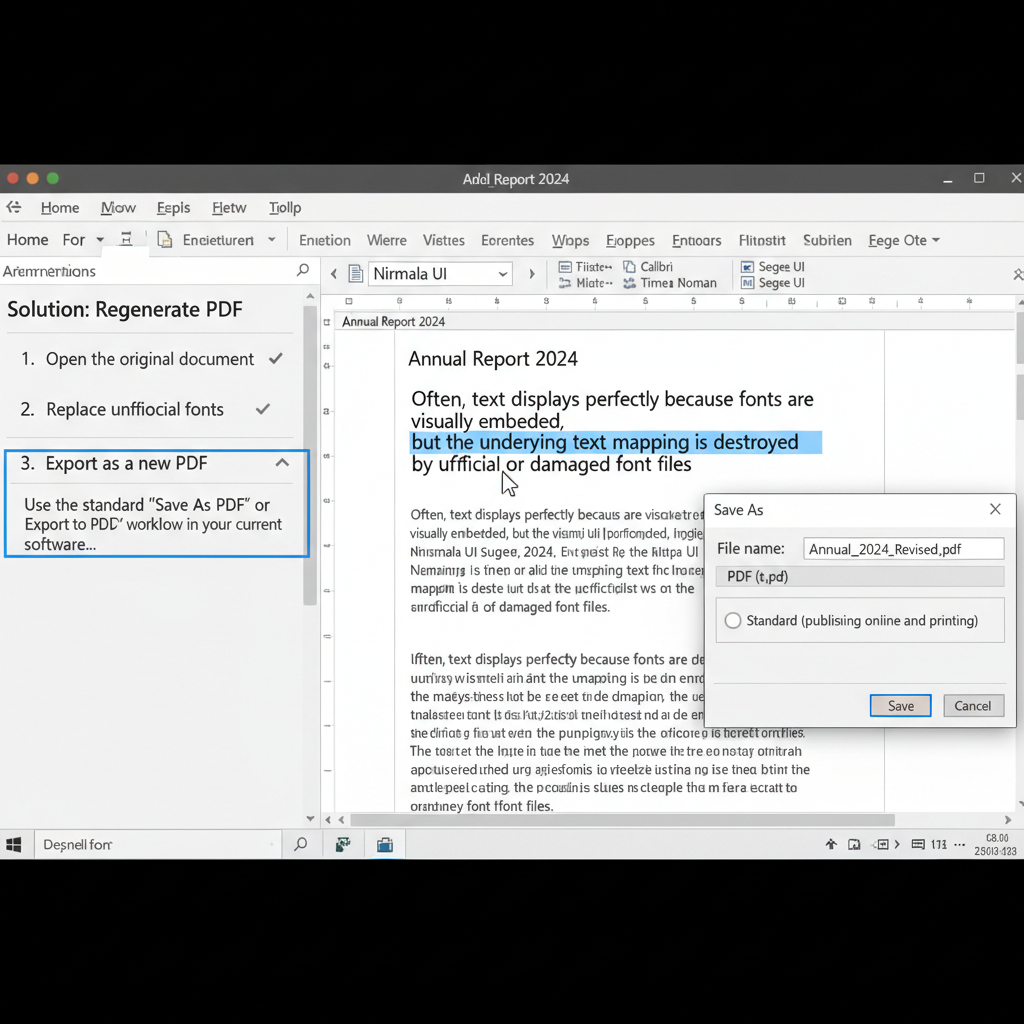
Often, text displays perfectly because fonts are visually embedded, but the underlying text mapping is destroyed by unofficial or damaged font files (e.g., custom versions of Nirmala UI). Regenerating the document with genuine fonts is the cleanest solution.
Open the source document in Microsoft Word or your preferred word processor.
Select the text and change the font to a genuine, system-provided OpenType Unicode font (such as the official Nirmala UI included with Windows).
Use the standard 'Save As PDF' or 'Export to PDF' workflow in your current software to generate a fresh document with correct character mapping.
Use OCR to Reconstruct Searchable Text
If the source file is lost or cannot be modified, Optical Character Recognition (OCR) can visually scan and recreate the text layer.
Use an Advanced Text Editor for Pasting
Sometimes standard Notepad fails to interpret certain clipboard encodings correctly. Trying a more advanced editor can occasionally bypass minor issues.
Effortlessly Manage and Fix PDF Text with WPS Office
WPS Office provides professional-grade PDF tools that ensure pristine text encoding during conversion. With built-in, highly accurate OCR, you can effortlessly extract perfectly mapped text even from incorrectly encoded PDFs.
- 1. Install WPS Office: Download and install the free WPS Office suite on your device.
- 2. Convert source files flawlessly: Use the built-in Word processor to export documents to PDF with perfectly preserved Unicode encoding.
- 3. Extract text with OCR: Open broken PDFs in WPS PDF, click the 'OCR' tool on the ribbon, and instantly extract clean, copyable text.

Frequently Asked Questions
Why does the text look completely normal in the PDF but paste as gibberish?
The PDF relies on two different mechanisms for text: the visual font data (which draws the shape of the letters on your screen) and the ToUnicode character map (which translates those shapes into standard copy-paste characters). If the character map is broken or missing, the text will look fine but copy out incorrectly.
Will embedding the fonts fix my copy-and-paste issue?
Not necessarily. While embedding fonts is good practice to ensure the document looks the same on every computer, it does not fix a corrupted ToUnicode table. If the original font file you used is unofficial or damaged, embedding it will still result in bad character mapping.
Can I manually edit the text encoding inside the broken PDF?
Directly editing the internal ToUnicode map of an existing PDF is incredibly complex and generally requires specialized developer tools. The most practical solutions for standard users are to either recreate the PDF from the original Word file or use OCR software to generate a brand new text layer.


