

Fix Ligature Mapping and Text Extraction Issues in PostScript PDFs

Question details
Users need to resolve an issue where text containing ligatures (like fi or ffi) fails to extract properly from PostScript-distilled PDFs.
- Product
- Device & OS
- not provided
- Scenario
- Copying, pasting, or searching for text within a PDF that was generated or distilled from PostScript.
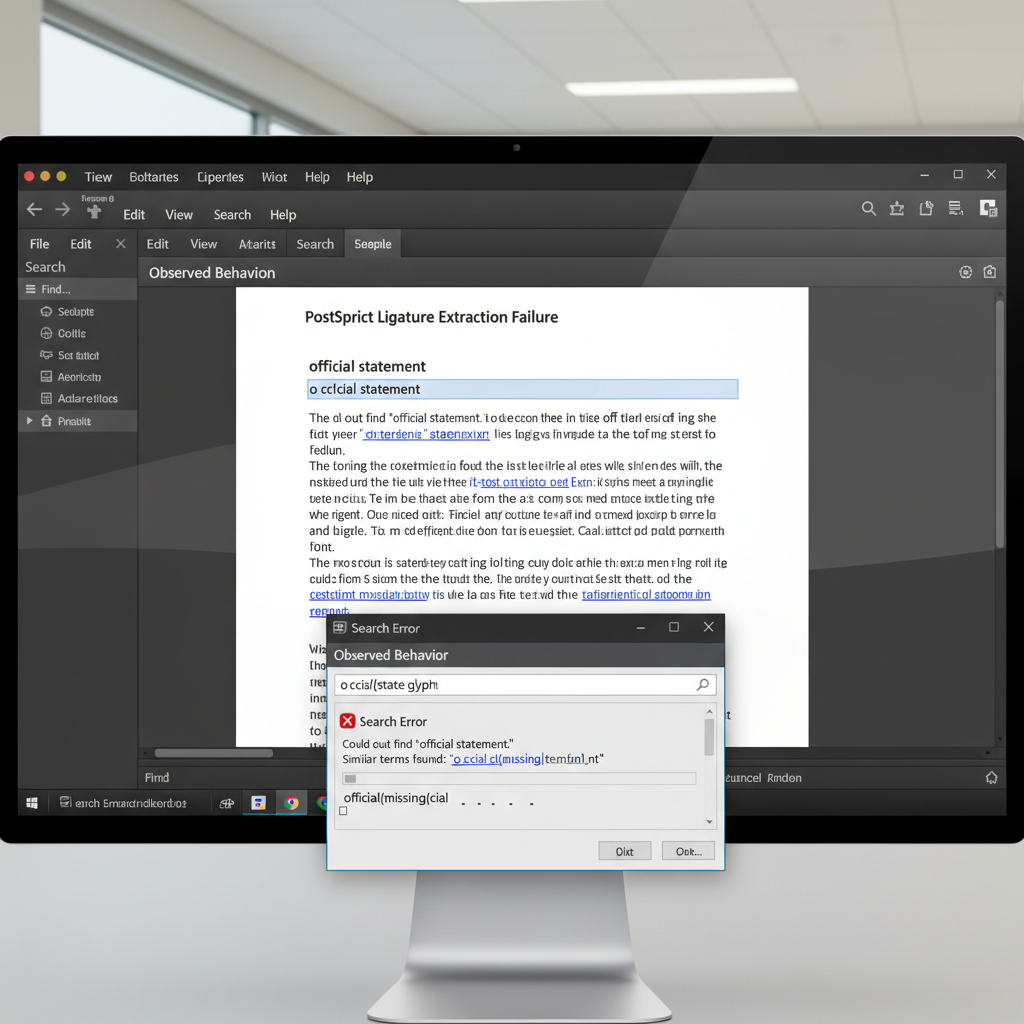
- Observed behavior
- Ligatures display visually correct in the PDF, but when copied or searched, they produce missing glyphs, extra spaces, or control characters (such as U+000E), making the text unsearchable.
Ensure you have access to the original source document and the PDF Distiller or export software, as fixing encoding problems usually requires recreating the PDF with different settings.
Adjust Font Embedding and Unicode Mapping During PDF Distillation
Modify the PDF export or Distiller settings to map ligatures correctly to component characters or standard Unicode, resolving extraction errors at the source.
When distilling PostScript to PDF, software can either export a ligature as a single Unicode glyph (like U+FB01) or map it to its component letters (like 'f' and 'i'). If mapped incorrectly or if the font lacks a ToUnicode table, Acrobat may substitute control characters instead of actual text.
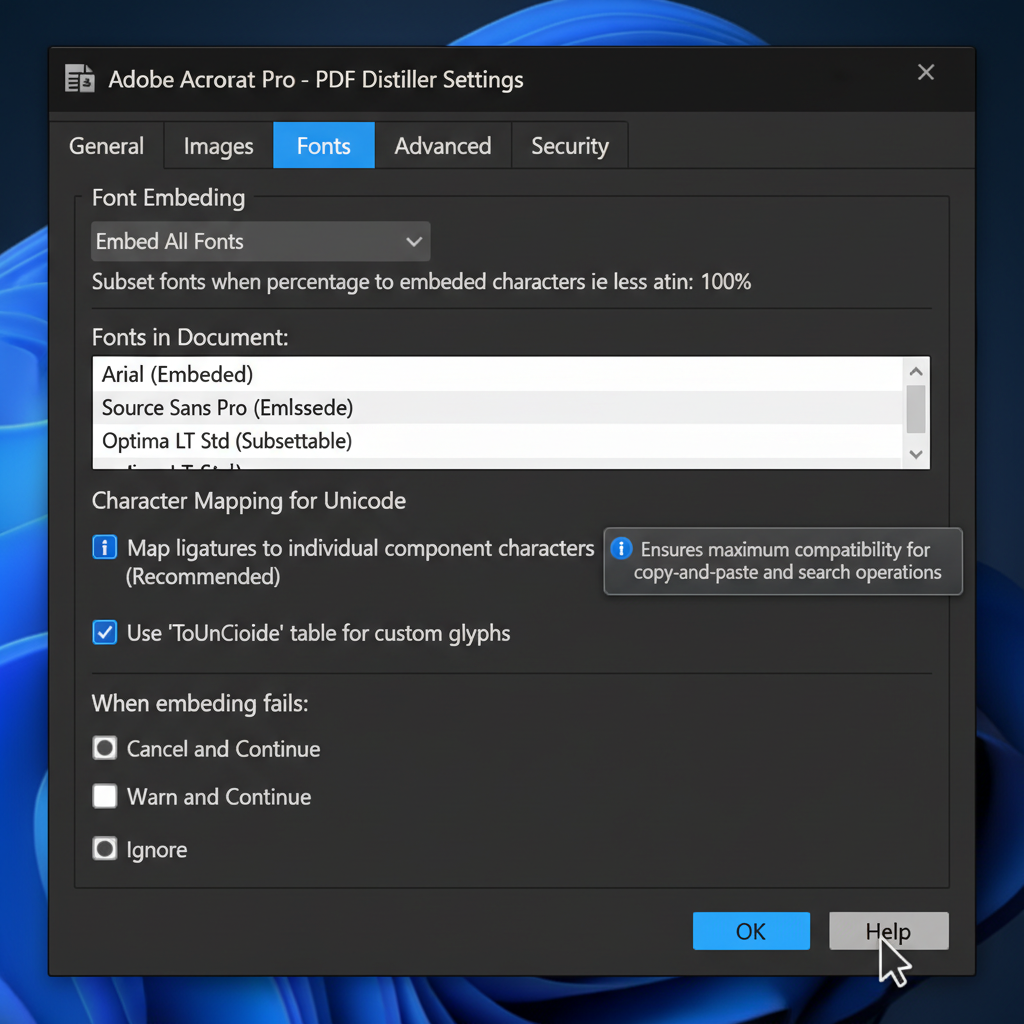
Mapping ligatures to their individual component characters during the PDF generation workflow is highly recommended to ensure maximum compatibility for copy-and-paste and search operations.
Launch the PDF Distiller or the authoring software (e.g., InDesign, Word) where the PostScript file is being converted to PDF.
Navigate to the font embedding or advanced export settings. Ensure that all fonts used in the document are set to be fully embedded rather than subsetted.
Look for an option related to 'ToUnicode' tables or ligature mapping. Adjust the setting to ensure ligatures are mapped to standard Unicode component characters.
Re-export or distill the PostScript file with these new settings, then open the resulting PDF in your viewer to test copying the ligatures.
Use OCR to Extract Text from Problematic PDFs
If you cannot recreate the PDF from the original PostScript file, use Optical Character Recognition (OCR) to visually read and re-encode the text.
Extract and Edit PDF Text Seamlessly with WPS Office
WPS Office provides advanced PDF tools, including accurate OCR and robust text extraction, ensuring that complex ligatures and encodings are handled correctly without generating broken characters.
- 1. Open the Problematic PDF: Launch WPS Office and open the PDF file containing the ligature extraction issues.
- 2. Attempt Direct Extraction: Use the standard text selection tool to copy the text. WPS Office's advanced rendering engine often processes single-glyph ligatures better natively.
- 3. Apply OCR if Necessary: If the text still copies with errors, navigate to the 'Tools' tab and select 'OCR'. Run the process to visually recognize the ligatures and generate fully searchable, correct text.

Frequently Asked Questions
Why do ligatures like 'ffi' copy as blank spaces or boxes?
This occurs when the PDF lacks a proper 'ToUnicode' table mapping for the ligature. The PDF viewer knows how to draw the visual shape of 'ffi' using the font, but it does not know what underlying text characters that shape represents, resulting in a blank space or an error box when copied.
Why does text extraction work in Chrome but fail in Acrobat?
Different PDF viewers use distinct text extraction engines. Chrome has broader built-in fallback support for certain single Unicode ligature glyphs (like U+FB03). Acrobat, however, relies more strictly on the embedded font data; if the ToUnicode table is missing, Acrobat may substitute control characters like SHIFT OUT.
Can I fix ligature issues without access to the original source document?
You cannot directly fix the underlying font encoding of an existing PDF without recreating it. However, you can use OCR (Optical Character Recognition) software to scan the document. The OCR tool will visually read the ligatures and place a new layer of correct, searchable text over the document.
What is the best way to handle ligatures when creating PDFs?
To ensure maximum compatibility for copy-and-paste and text search across all PDF readers, it is generally best to configure your PDF Distiller or export settings to map ligatures to their component characters (e.g., mapping the visual 'fi' shape to the separate letters 'f' and 'i').


