

How to Export Diacritical Marks Correctly from PDF Files
Question details
The user needs to correctly export text containing diacritical marks (such as umlauts) from a PDF file without the characters becoming corrupted.
- Product
- Device & OS
- not provided
- Scenario
- Exporting or copying text from a PDF document that contains accented characters.
- Observed behavior
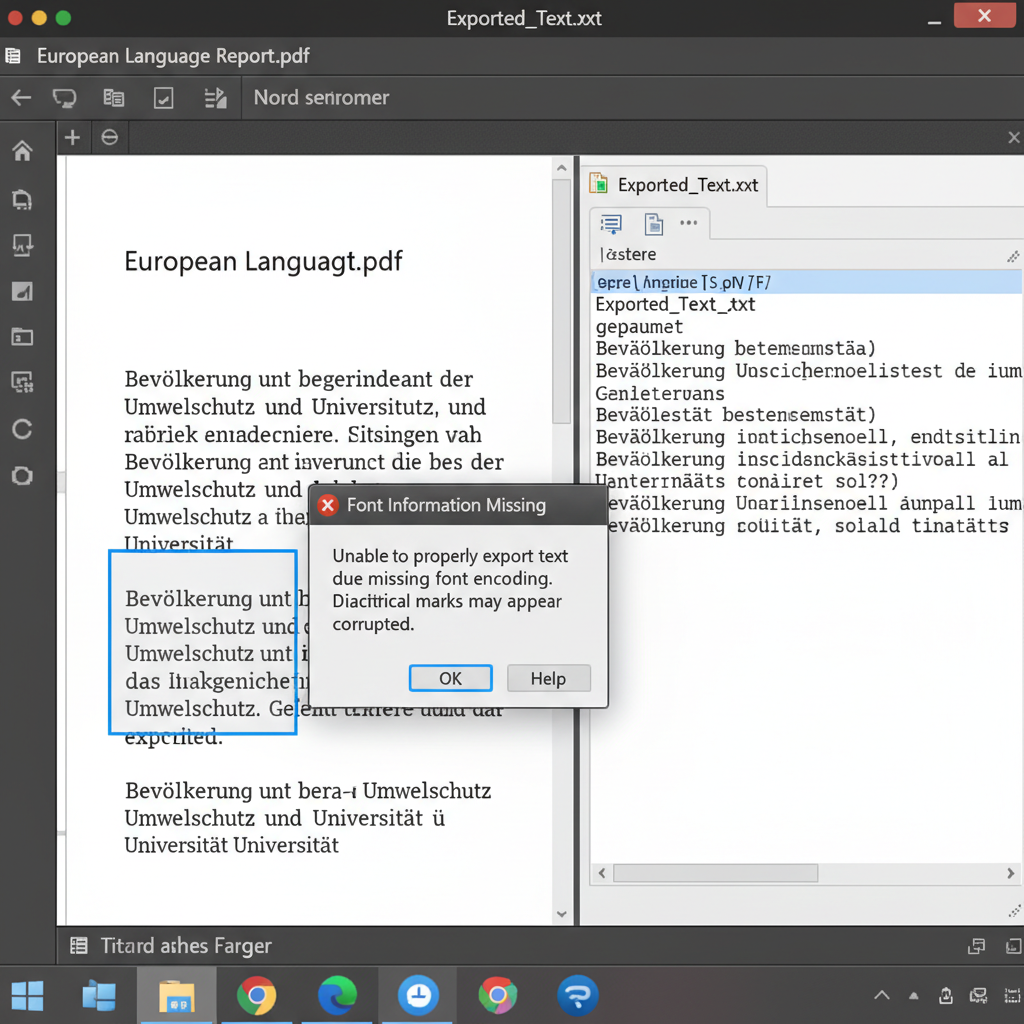
- Standard text exports normally, but diacritical marks export incorrectly or as garbled symbols due to missing font information.
Verify if you have access to the original source document (such as a Word or InDesign file) used to create the PDF, as resolving this issue natively often requires recreating the file with correct font settings.
Recreate the PDF with Embedded Unicode Fonts
The most reliable way to fix character mapping issues is to generate a new PDF with fully embedded, Unicode-compatible fonts from the original source file.
When a PDF is created without properly embedding fonts or using non-standard encoding, extraction tools cannot translate special characters like umlauts back to standard text. This results in standard letters exporting fine, while accents are broken.
Open the original source file in its native application (e.g., Microsoft Word, WPS Writer, or Adobe InDesign).
Select your text and ensure a standard, Unicode-compatible font (such as Arial, Times New Roman, or Calibri) is applied to the diacritical marks.
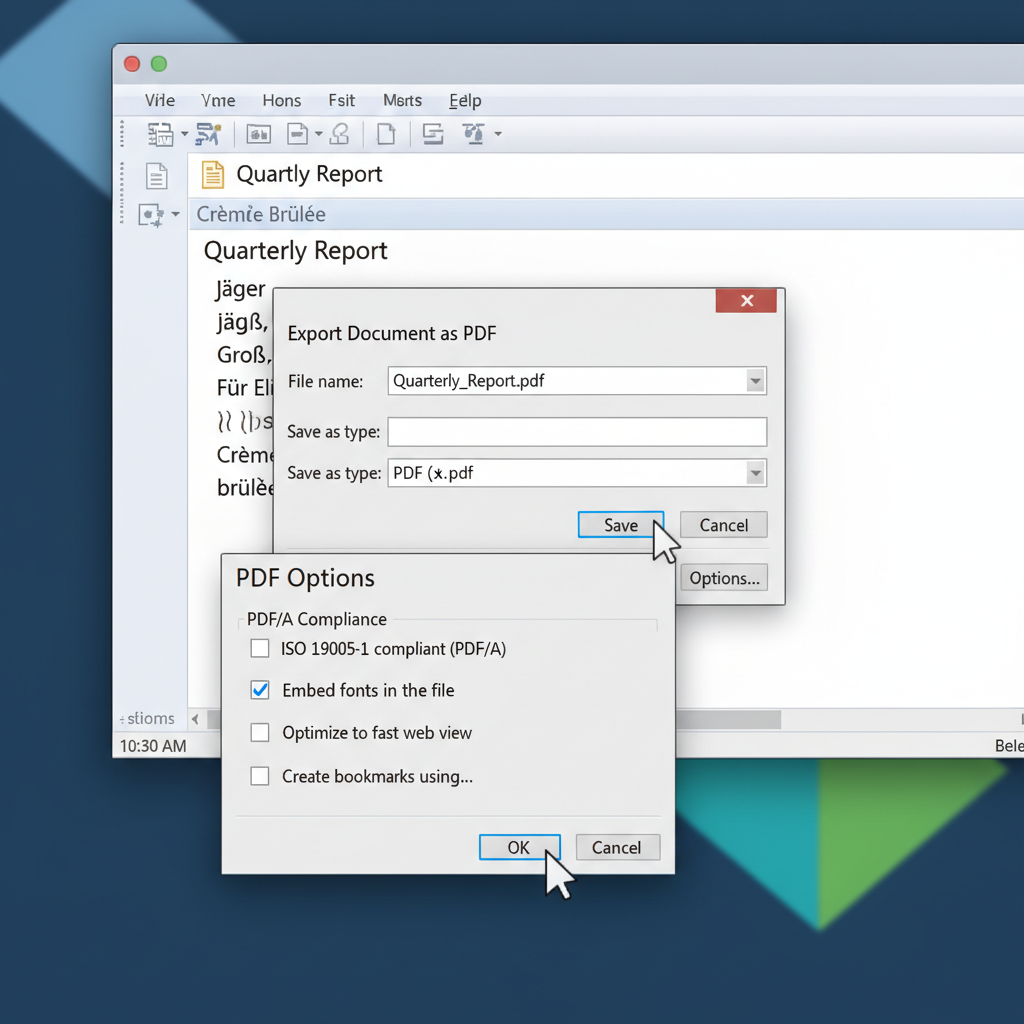
Go to the 'File' menu, select 'Export to PDF' or 'Save As', and locate the 'Options' or 'Settings' button in the save dialog.
Check the box that says 'Embed fonts in the file' or select 'ISO 19005-1 compliant (PDF/A)' to ensure character maps are saved.
Save the new PDF, open it, and attempt the text extraction again to verify the diacritical marks display correctly.
Use OCR to Extract the Text Visually
If you do not have the original file, using an Optical Character Recognition (OCR) tool can recognize the characters visually instead of relying on the corrupted internal font data.
Easily Convert PDFs with Accurate Character Recognition using WPS Office
WPS Office provides a robust PDF toolkit equipped with advanced OCR and high-fidelity conversion capabilities, ensuring that special characters and diacritical marks are perfectly preserved when converting to Word, Excel, or Text.
- 1. Open PDF in WPS Office: Launch WPS Office and open the PDF file containing the diacritical marks.
- 2. Access Conversion Tools: Navigate to the 'Tools' tab and select 'PDF to Word' or the 'OCR' button depending on your needs.
- 3. Configure Language Settings: In the conversion dialog, select the appropriate document language to ensure the engine accurately maps accents and umlauts.
- 4. Convert the Document: Click 'Convert' to extract the text flawlessly into an editable format.
Frequently Asked Questions
Why do umlauts and accents turn into weird symbols when copying from a PDF?
This happens when the PDF was created without proper character mapping or embedded fonts. The PDF viewer knows how to visually draw the shape of the character on the screen, but the underlying text data doesn't map to standard Unicode characters.
Can I fix font encoding issues directly within the PDF?
Fixing encoding directly in a compiled PDF is highly complex and often not possible using standard tools. The best approach is to either recreate the PDF from the original source file with fonts embedded, or use an OCR tool to extract the text visually.
Does the 'Print to PDF' function cause diacritical mark errors?
Yes, it can. Many 'Print to PDF' virtual printers subset fonts or ignore Unicode mapping to reduce the final file size. Using a dedicated 'Export to PDF' or 'Save as PDF' feature inside the authoring software usually provides much better character retention.


