

Fix Converted PDF to Excel (XLSX) Files Showing Unreadable Characters
Question details
The user needs to know why their PDF to XLSX conversion fails and results in corrupted, unreadable text.
- Product
- PDF Converter
- Device & OS
- not provided
- Scenario
- Converting a PDF document into an editable Excel (XLSX) spreadsheet to analyze or extract data.
- Observed behavior
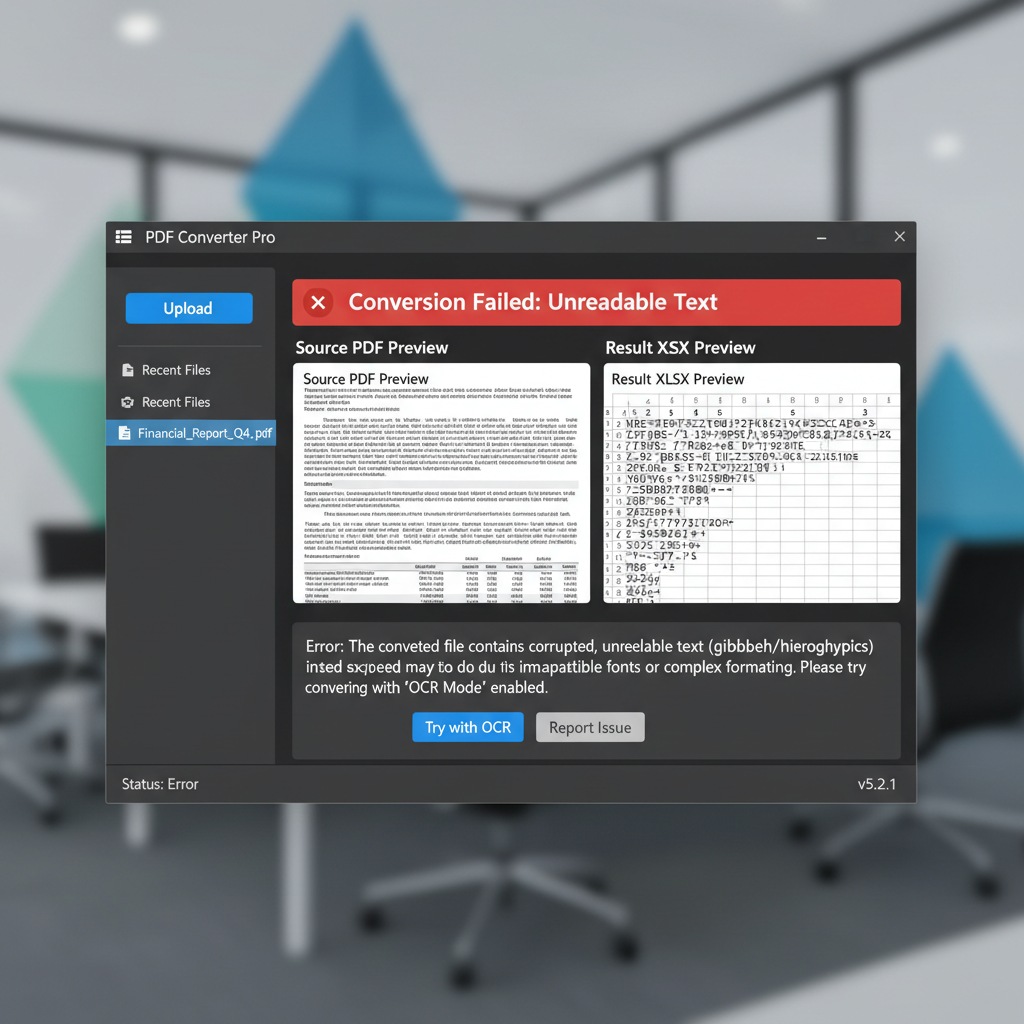
- The resulting XLSX file displays unreadable characters, gibberish, or hieroglyphics instead of the expected textual and numerical data.
Ensure that the original PDF file is not password-protected against copying or extraction, and verify whether the document contains scanned images of text rather than actual machine-readable text layers.
Use OCR to Convert Scanned PDFs
If the original PDF is an image or a scanned document, standard conversion methods will fail. Using an OCR (Optical Character Recognition) tool extracts the text accurately.
Standard PDF-to-Excel converters attempt to map existing text layers into spreadsheet cells. When a PDF is scanned, it lacks these text layers, causing the converter to output misaligned shapes or gibberish. OCR technology bridges this gap by visually reading the characters.
Launch a PDF editor equipped with OCR capabilities, such as Adobe Acrobat or WPS Office, and open the problematic PDF file.
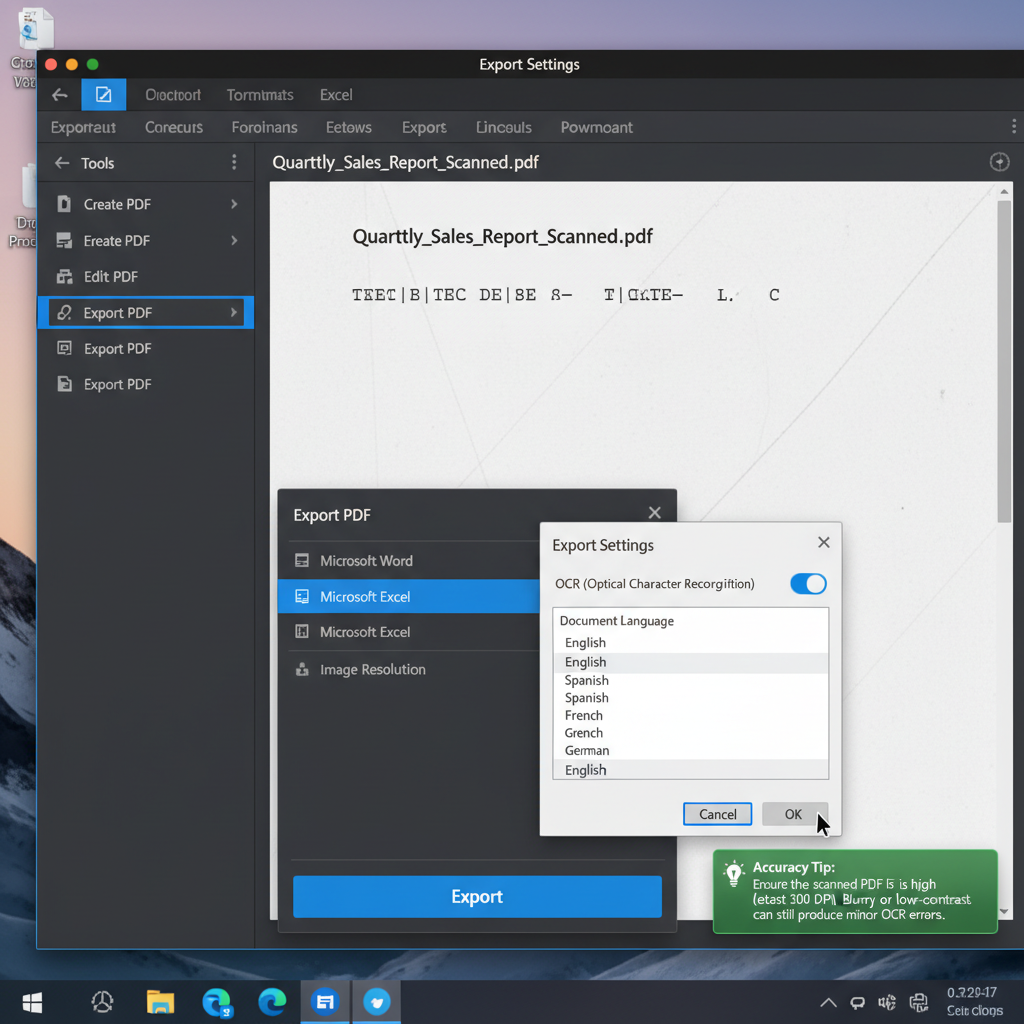
Navigate to the tools menu and select the 'PDF to Excel' or 'Export PDF' conversion option.
Before initiating the conversion, open the settings menu (often a gear icon) and ensure the 'Recognize Text' or 'OCR' feature is toggled on.
Choose the correct language of the document to ensure the OCR engine accurately recognizes specific letters and characters.
Click 'Convert' or 'Export', save the new XLSX file, and open it to verify that the unreadable characters have been resolved.
Flatten the PDF to Resolve Font and Encoding Issues
Unsupported custom fonts or non-standard encoding in the original PDF can cause character misinterpretation in Excel. Flattening the file often normalizes the encoding.
Convert PDF to Excel with High Accuracy Using WPS Office
WPS Office provides a powerful, built-in PDF to Excel converter with advanced OCR technology. It accurately extracts data, tables, and text from standard and scanned PDFs, eliminating formatting errors and unreadable characters effortlessly.
- 1. Download and open: Install WPS Office and open your PDF file using the built-in WPS PDF tool.
- 2. Select PDF to Excel: Navigate to the 'Tools' tab on the top ribbon and select the 'PDF to Excel' option.
- 3. Configure OCR: If your document is scanned, ensure the OCR option is enabled and set the correct document language in the pop-up window.
- 4. Start conversion: Select your desired page range and click the 'Convert' button to begin the extraction process.
- 5. Edit seamlessly: Once completed, the exported XLSX file will instantly open in WPS Spreadsheet for seamless editing.
Frequently Asked Questions
Why does my converted Excel file look like hieroglyphics?
This happens when the PDF uses non-standard text encoding, lacks embedded fonts, or is a scanned image without a native text layer. The conversion software attempts to map unknown character codes, resulting in unreadable gibberish instead of actual letters and numbers.
How do I know if my PDF needs OCR for conversion?
Open your PDF reader and try selecting individual words with your mouse cursor. If you cannot highlight text, or if the entire page is selected as a single image box, it is a scanned document and requires OCR to be converted properly.
Can I fix the unreadable characters directly within Excel?
Usually, no. Once the file is converted with incorrect encoding, the original data structure is lost. You cannot reverse the gibberish natively in Excel. It is highly recommended to resolve the issue during the PDF conversion stage by using better software or enabling OCR.
Are there specific fonts that cause conversion issues?
Yes, proprietary fonts, custom corporate typography, or heavily stylized fonts that are not embedded correctly within the PDF can fail to translate into standard Excel fonts like Calibri or Arial, directly causing character rendering errors upon conversion.


