



Fix PDF Converts to Unreadable Greek Characters in Word and Excel
Question details
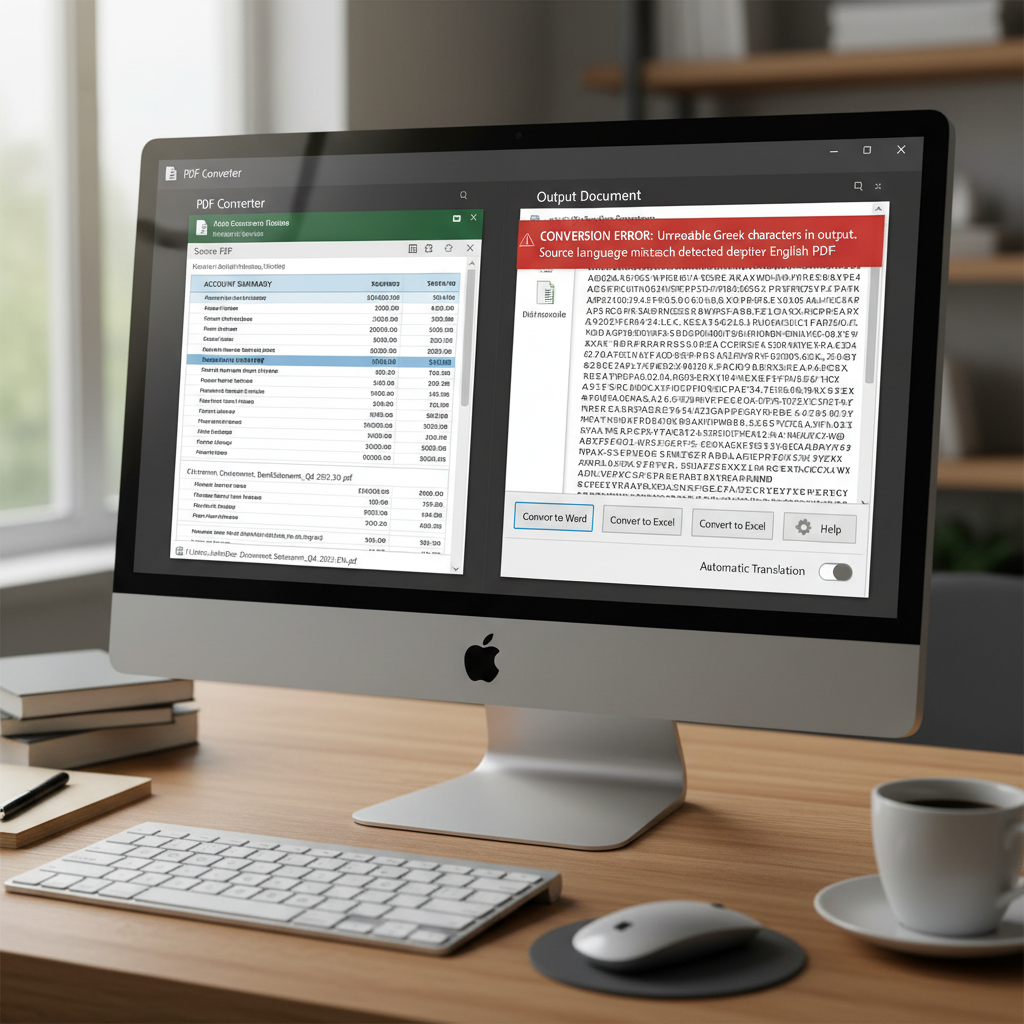
The user is attempting to convert English bank PDF files into Word or Excel, but the resulting document displays unreadable Greek characters instead of English text.
- Product
- PDF Converter
- Device & OS
- not provided
- Scenario
- Extracting financial data and text from downloaded bank statements into editable Microsoft Word or Excel formats.
- Observed behavior
- The converted document outputs garbled, unreadable Greek characters despite the source PDF being in English and automatic translation settings being disabled.
Check if your original PDF contains nonstandard, custom, or heavily protected embedded fonts, as these commonly cause text extraction engines to read the character encoding incorrectly.
Use Optical Character Recognition (OCR) to Extract Text
Bypassing the corrupted embedded fonts by using OCR forces the software to read the visual shapes of the letters instead of relying on broken internal font encoding.
Bank PDFs often use subset fonts or custom encoding for security reasons. When a standard PDF converter tries to read the text layer, it fails to map the characters to standard English letters, resulting in Greek or wingding symbols.
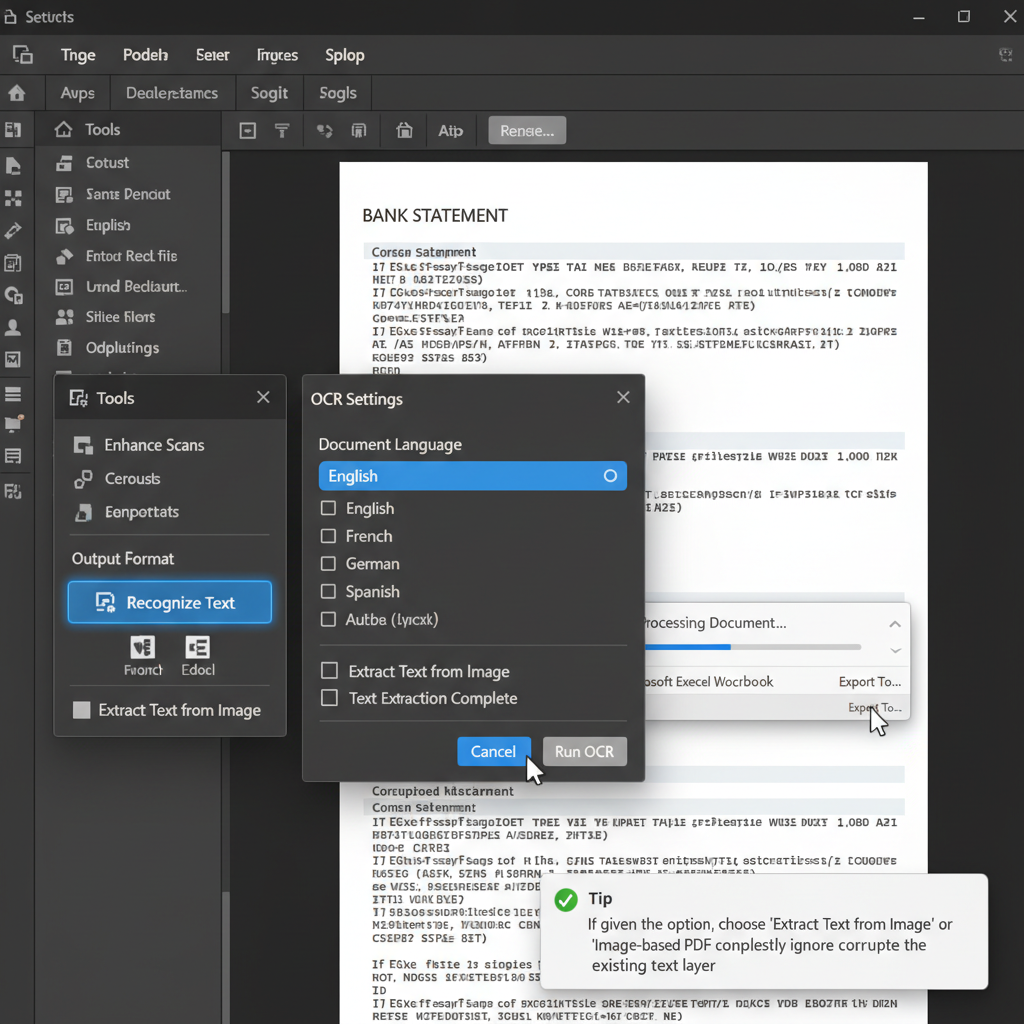
Open your PDF document in your preferred PDF editor or converter and navigate to the OCR (Optical Character Recognition) feature in the Tools menu.
In the OCR settings menu, manually select 'English' as the recognition language to ensure it does not attempt to interpret the garbled font encoding.
Execute the OCR process to convert the document into a scanned text layer, and then export or save the file as a Microsoft Word or Excel document.
Flatten the PDF Before Conversion
Flattening the PDF by "printing" it as a new PDF removes the problematic digital text layer entirely, creating an image-based PDF that is cleaner for OCR processing.
Accurately Convert Bank Statements to Word and Excel with WPS Office
WPS Office features a robust, built-in PDF conversion engine with highly accurate OCR technology. It easily bypasses broken font encodings in financial documents to extract clean, perfectly formatted English text.
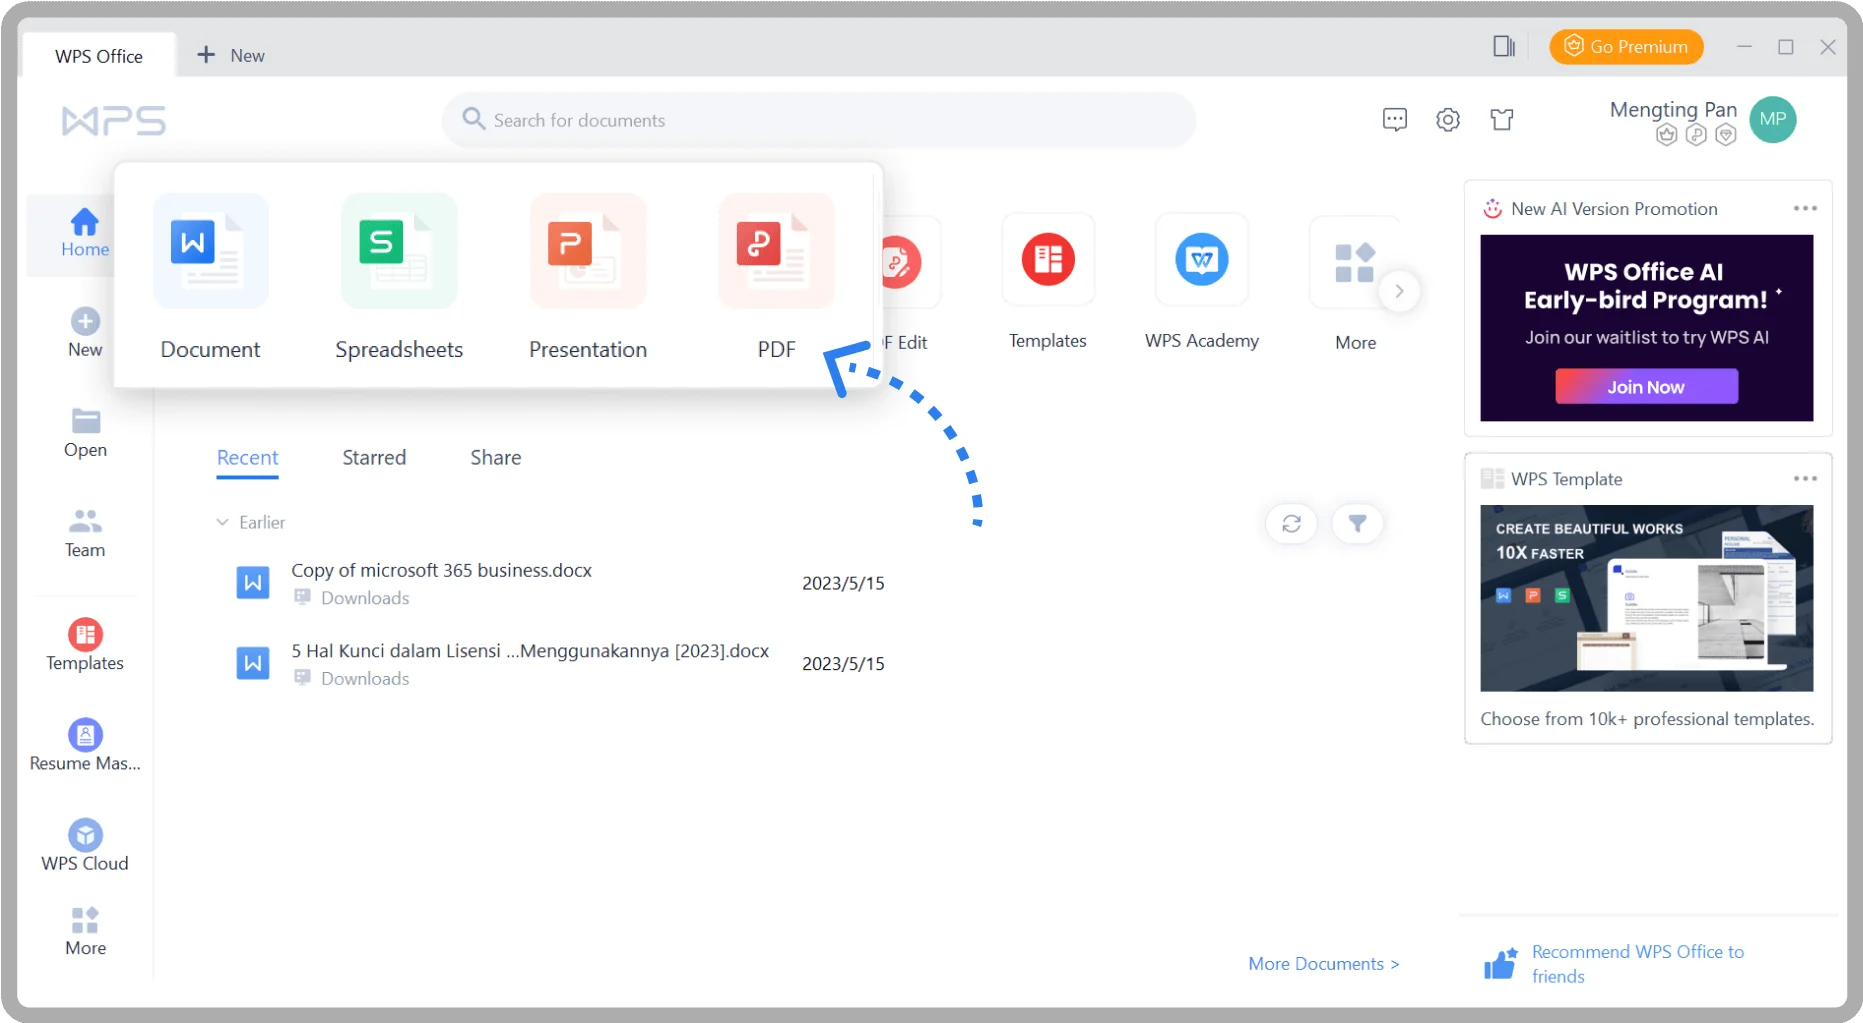
- 1. Open the PDF in WPS Office: Launch WPS Office, go to the PDF tab, and open your bank statement.
- 2. Select the Conversion Tool: Click on 'PDF to Word' or 'PDF to Excel' located in the top toolbar.
- 3. Enable OCR Settings: In the conversion dialog box, check the option for OCR and ensure the language is set to English.
- 4. Convert and Save: Click 'Convert' to securely process the document and immediately open the editable, error-free file.
Frequently Asked Questions
Why do my PDF fonts turn into weird symbols when converted?
This happens when the original PDF was created with embedded custom fonts, subset fonts, or DRM protection. The converter cannot map the original internal codes to standard Unicode characters, resulting in a display of weird symbols or Greek letters.
Will enabling OCR fix the garbled text?
Yes. Optical Character Recognition (OCR) ignores the digital text layer and instead scans the visual shapes of the letters on the page. This bypasses the corrupted font encoding entirely and reconstructs the text accurately.
Is there a way to prevent encoding issues when saving bank statements?
If your banking portal allows it, download statements directly in CSV or Excel format instead of PDF. Alternatively, use your browser's 'Print to PDF' feature rather than the bank's direct download button, as this often flattens the file and simplifies the fonts.


