



How to Fix Scanned PDF Converting to Unreadable Text in Word
Question details
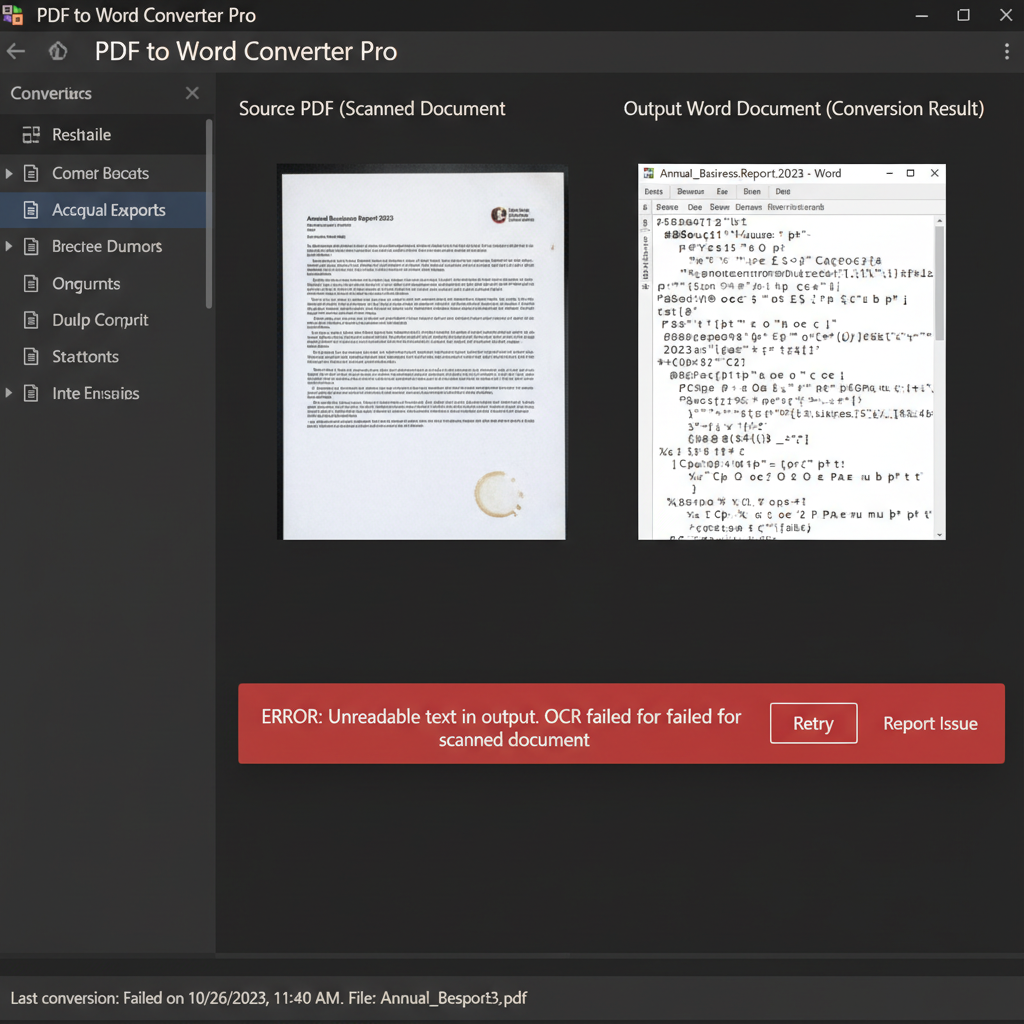
The user is experiencing garbled or unreadable text when attempting to convert a scanned PDF document into a Microsoft Word file.
- Product
- PDF to Word Converter
- Device & OS
- not provided
- Scenario
- Converting a scanned PDF to an editable Microsoft Word document for text extraction and editing.
- Observed behavior
- The resulting Word document produces unreadable text, strange symbols, or garbled characters instead of the original scanned content.
Ensure you have the original scanned PDF file saved locally on your device and check if the document contains reasonably clear, legible text without heavy blurring or watermarks.
Improve Scan Quality and Configure OCR Language
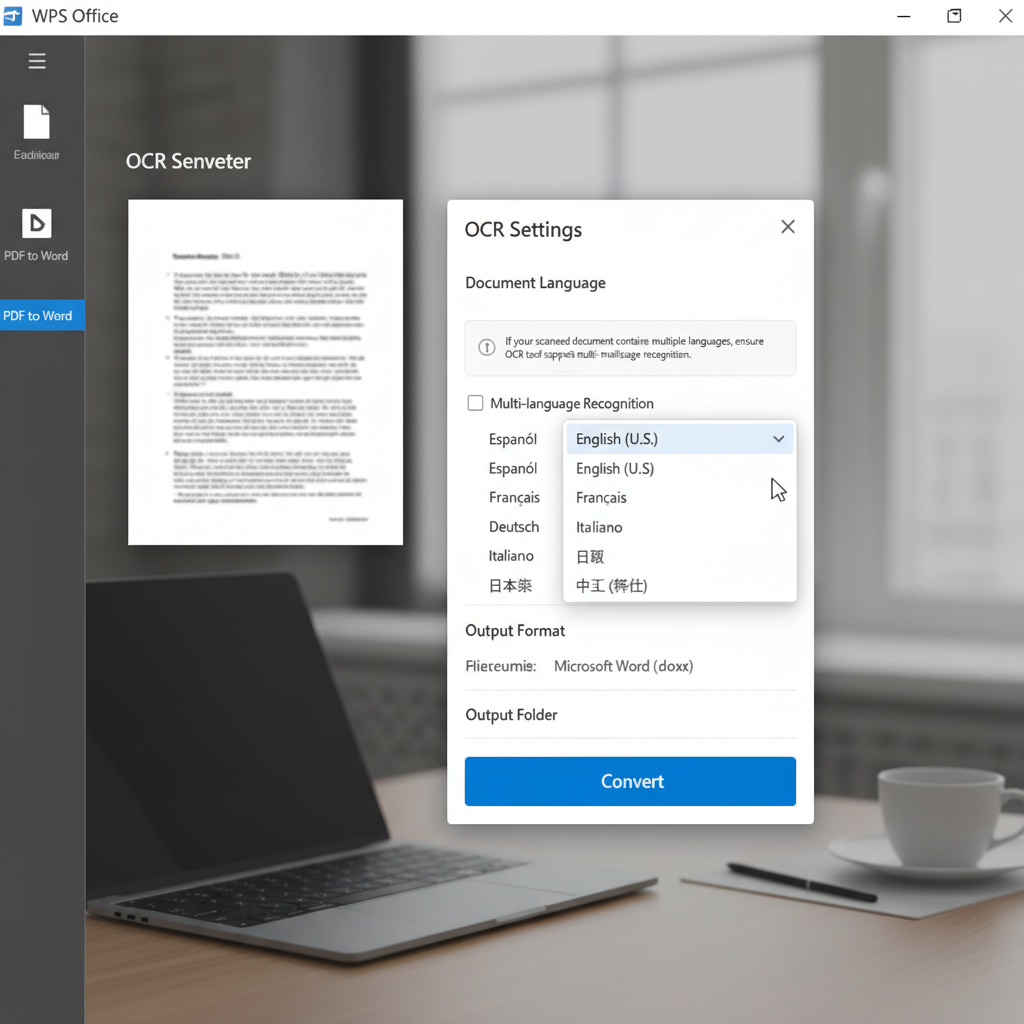
Since scanned PDFs rely on Optical Character Recognition (OCR), providing a high-quality scan and selecting the correct document language is crucial for accurate text extraction.
A PDF converter must 'read' the image using OCR technology. Poor scan quality, low resolution, or mismatched OCR language settings are the most common reasons for garbled output.
If you have the physical file, open your scanning software and re-scan the document at a higher resolution (preferably 300 DPI or higher).
Ensure the physical document is flat and well-lit to avoid shadows, skewed angles, or blurred text in the resulting PDF.
Launch your PDF software (such as Adobe Acrobat or WPS Office) and access the 'Export PDF' or 'PDF to Word' feature.
Before clicking the convert button, open the 'Settings' or 'Document Language' menu within the OCR options and manually select the exact language used in the scanned document.
Run the conversion process again and open the output Word file to verify that the text is now legible and properly formatted.
Resolve Missing or Unembedded Font Issues
Garbled text can occur if the original PDF uses custom fonts that were not properly embedded into the file during creation.
Use WPS Office for Accurate PDF to Word Conversion
WPS Office features an advanced, built-in OCR engine that accurately recognizes text from scanned images, allowing you to seamlessly convert scanned PDFs into fully editable Microsoft Word documents without garbled text.
- 1. Open your PDF in WPS Office: Download and launch WPS Office on your device, then open the scanned PDF document you want to convert.
- 2. Access PDF to Word tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'PDF to Word' button.
- 3. Enable OCR recognition: In the conversion dialog box, ensure the OCR option is enabled so the software knows to extract text from images, and verify the correct language is selected.
- 4. Start conversion: Click 'Start' to begin the process. The clean, fully editable Word document will automatically open in WPS Writer once finished.
Frequently Asked Questions
What is OCR and why is it necessary for scanned PDFs?
OCR stands for Optical Character Recognition. It is a technology used to identify and extract text characters from images or scanned documents. Without OCR, a converter treats a scanned PDF as a flat picture, which makes extracting editable text impossible.
Why do some letters look like strange symbols after converting my PDF to Word?
This usually happens due to missing fonts or a poor-quality scan. If the OCR engine cannot clearly see a letter, or if the original font is not recognized by your system, the converter guesses the character and substitutes it with incorrect symbols or garbled text.
Can I accurately convert a handwritten PDF document to Word?
Yes, but the accuracy depends heavily on the legibility of the handwriting and the quality of your OCR software. Standard OCR engines work incredibly well with printed text, but messy or overlapping cursive handwriting may still result in unreadable conversions.
How can I check if my PDF is a scanned image or a standard text document?
Open the PDF and try to highlight a single word using your mouse cursor. If you can select individual letters and words, it is a text-based PDF. If clicking highlights the entire page as one single block, it is a scanned image.


