



Fix Scanned PDF Converts to Word with Garbled Text and White Areas
Question details
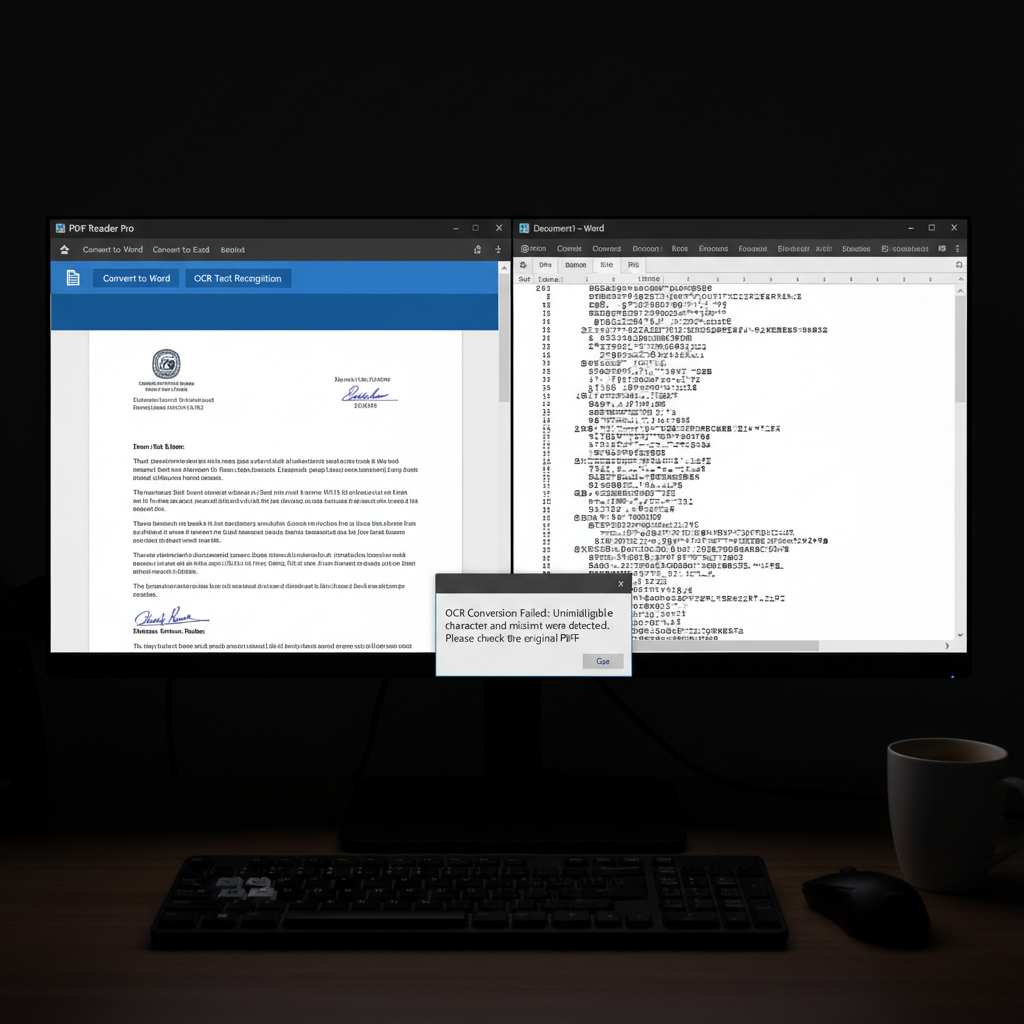
The user is experiencing garbled characters and missing content (blank white areas) when attempting to convert a scanned PDF document into a Microsoft Word file.
- Product
- PDF Reader/Editor
- Device & OS
- not provided
- Scenario
- Converting a scanned PDF containing images, signatures, or dates into an editable Word document using optical character recognition (OCR).
- Observed behavior
- The resulting Word document displays unintelligible, garbled text and blank white spaces where actual text or images should appear.
Ensure your original scanned PDF is clear, high-resolution, and free of dark shadows, as poor scan quality is the leading cause of Optical Character Recognition (OCR) failures.
Verify OCR Capabilities and Document Type
Confirm that your PDF application supports OCR and check whether the PDF contains flat images instead of selectable text.
Standard PDF readers cannot process scanned text. If you are using a basic reader, the conversion will either fail or export a blank image. You must use a premium PDF editor equipped with Optical Character Recognition (OCR) to convert scanned pixels into editable Word characters.
Open the scanned PDF in your viewer and attempt to highlight the text with your cursor. If the entire page highlights as one large box, the document is an image and requires OCR.
Open the document in a comprehensive PDF editor (like WPS Office or Adobe Acrobat Pro) rather than a basic PDF reader.
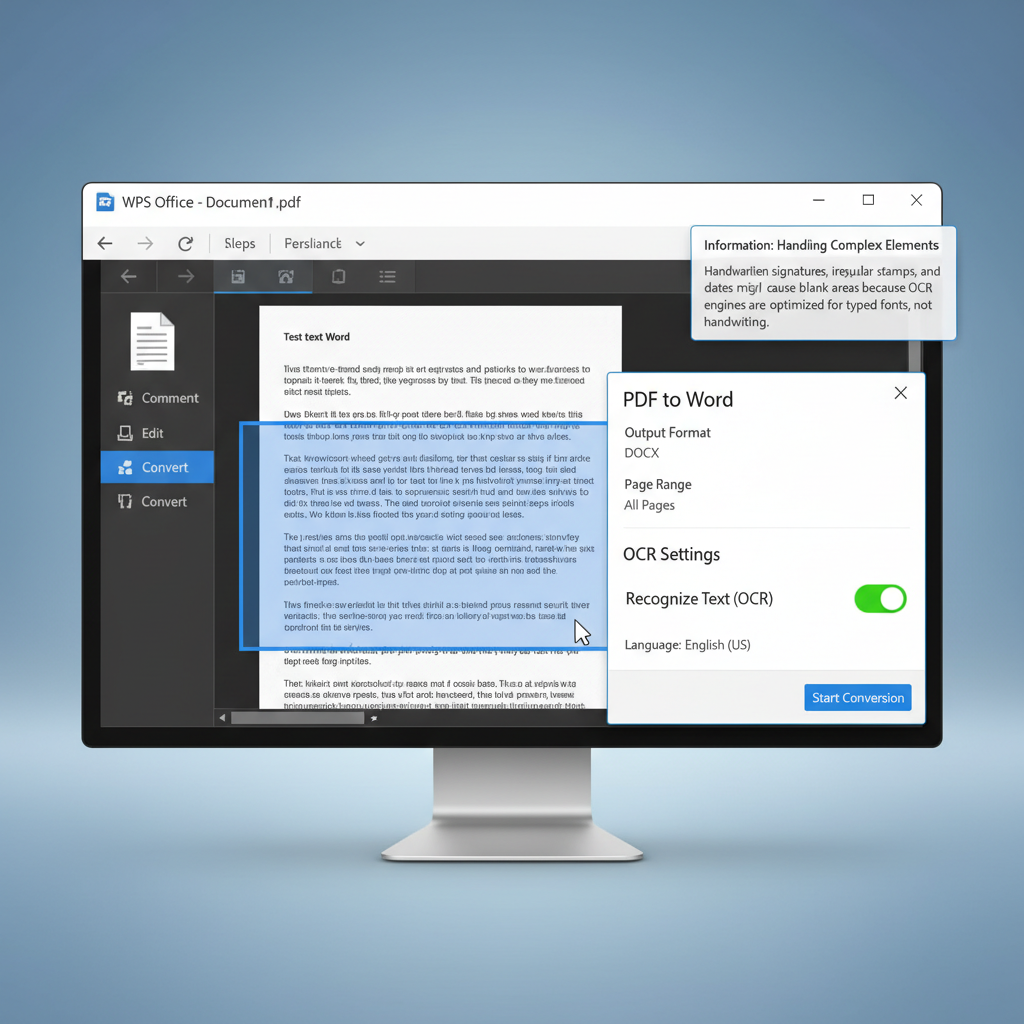
Navigate to the 'Export to Word' or 'PDF to Word' feature and ensure the 'Recognize Text' or 'OCR' settings toggle is enabled before starting the conversion.
Improve Source Scan Quality Before Conversion
Re-scan or enhance the contrast of the original document to give the OCR engine cleaner text to read.
Use WPS Office to Convert Scanned PDFs to Word Automatically
WPS Office features advanced, built-in OCR technology that seamlessly identifies and converts text from scanned PDFs into highly accurate, fully editable Word documents, eliminating garbled text and retaining your original layout.
- 1. Open your scanned PDF: Launch WPS Office and open your scanned PDF document.
- 2. Select PDF to Word: Navigate to the 'Tools' tab and select 'PDF to Word' from the menu ribbon.
- 3. Enable OCR Settings: In the conversion prompt, make sure the 'OCR' (Optical Character Recognition) option is checked and select the correct document language.
- 4. Convert Document: Click the 'Convert' button to generate a clean, editable Word document without garbled characters.
Frequently Asked Questions
Why do signatures and dates disappear when converting a PDF to Word?
Optical Character Recognition (OCR) is designed to recognize standard typed fonts. Handwritten elements like signatures and handwritten dates are often unrecognized and may render as blank white spaces in the final Word document.
Can a free PDF reader convert scanned documents to Word?
Most free or basic PDF readers lack the required OCR technology to process scanned documents. Converting a scanned file with a basic reader will usually result in a Word document filled with uneditable flat images instead of real text.
How do I know if my PDF requires OCR before converting?
Try to select a single word with your mouse cursor. If you can highlight individual letters or words, it contains real text. If clicking and dragging only selects the entire page as a single image box, it is a scanned document that requires OCR for conversion.
What is the best resolution for scanning documents to ensure accurate OCR conversion?
For the best OCR accuracy and to prevent garbled text, it is highly recommended to scan your physical documents at a minimum of 300 DPI (Dots Per Inch) in black and white or grayscale.


