

How to Fix Identity-H Font Encoding Issues in PDFs for Text Extraction

Question details
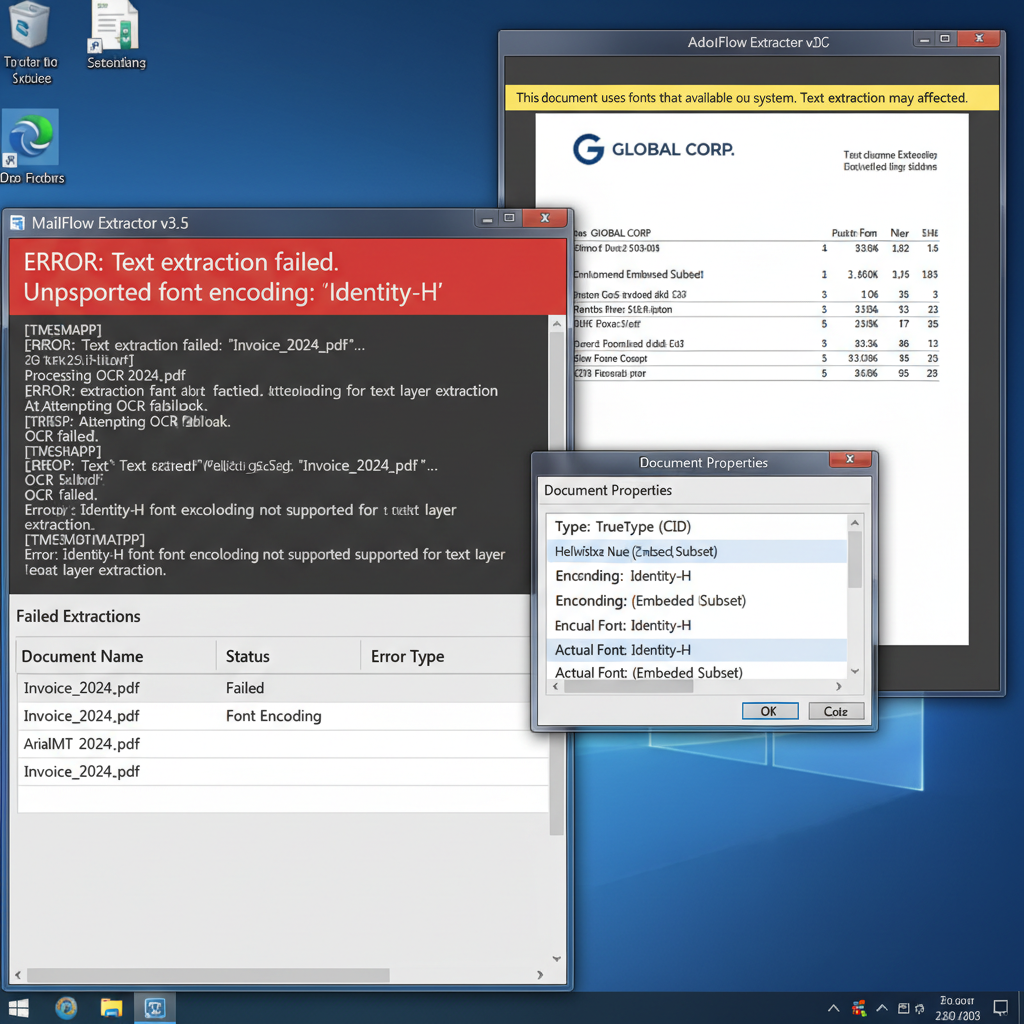
The user needs to resolve an issue where a mailroom application cannot extract text from PDFs due to Identity-H font encoding.
- Product
- Device & OS
- Windows 10
- Scenario
- Extracting text from PDF files for a mailroom application after upgrading to Windows 10.
- Observed behavior
- The text extraction tool fails because the newly created PDFs use TrueType CID fonts with Identity-H encoding, which the application does not natively support.
Confirm whether your text extraction or mailroom software has any available updates, as Identity-H is a standard PDF encoding that modern applications should natively support.
Update the Receiving Application to Support CID Fonts
Since Identity-H is a valid and standard PDF encoding, the most reliable fix is ensuring the extracting application supports it.
Identity-H encoding is standard for TrueType CID fonts in modern PDF creation tools. It cannot normally be disabled through standard Acrobat or Distiller settings without causing text rendering issues.
Locate the contact information or support portal for the vendor of your mailroom or text extraction software.
Reach out to their technical support team and report the text extraction failure.
Ask if they have a software update, patch, or recommended workaround that adds support for TrueType CID fonts and Identity-H encoding.
Change to Fonts with a Limited Character Set
Switching to simpler fonts can sometimes bypass the automatic application of Identity-H encoding during PDF creation.
Disable Local Fonts in PDF Viewer Preferences
Modifying how your PDF software handles local fonts can occasionally resolve reading or extraction conflicts.
Use WPS PDF to Convert or Extract Text Seamlessly
If your current mailroom application struggles with Identity-H encoded PDFs, you can use WPS Office to convert these PDFs into Word or plain text formats, ensuring 100% text extraction compatibility without font encoding errors.
- 1. Open the PDF in WPS Office: Launch WPS Office and open the Identity-H encoded PDF file.
- 2. Navigate to PDF Tools: Click on the 'Tools' tab located in the top menu bar to access the conversion options.
- 3. Select the conversion format: Click on 'PDF to Word' or 'PDF to Text', depending on the input format required by your mailroom software.
- 4. Convert the file: Select your desired output destination and click 'Convert' to generate a new document with easily extractable text.

Frequently Asked Questions
What is Identity-H font encoding in a PDF?
Identity-H is a standard encoding method used in PDFs for TrueType CID (Character Identifier) fonts. It allows the PDF to support complex and extensive character sets, making it highly common in files created on modern operating systems like Windows 10.
Can I disable Identity-H encoding in Adobe Acrobat?
No, Identity-H cannot normally be disabled directly in Acrobat or Distiller settings. It is automatically applied to TrueType CID fonts during PDF creation to ensure all characters are properly rendered and embedded in the document.
Why does my text extractor output gibberish from Identity-H PDFs?
If your text extraction software does not support CID fonts or Identity-H encoding, it cannot accurately map the encoded characters back to standard text. This results in gibberish, blank spaces, or total extraction failures.
Does upgrading to Windows 10 change how PDFs encode fonts?
Yes, Windows 10 handles fonts and printing differently than older systems like Windows 7. Print-to-PDF drivers and modern PDF creators in Windows 10 are more likely to utilize TrueType CID fonts with Identity-H encoding for better international character support.


