

How to Fix Unsearchable OCR Text and Identity-H PDF Encoding

Question details
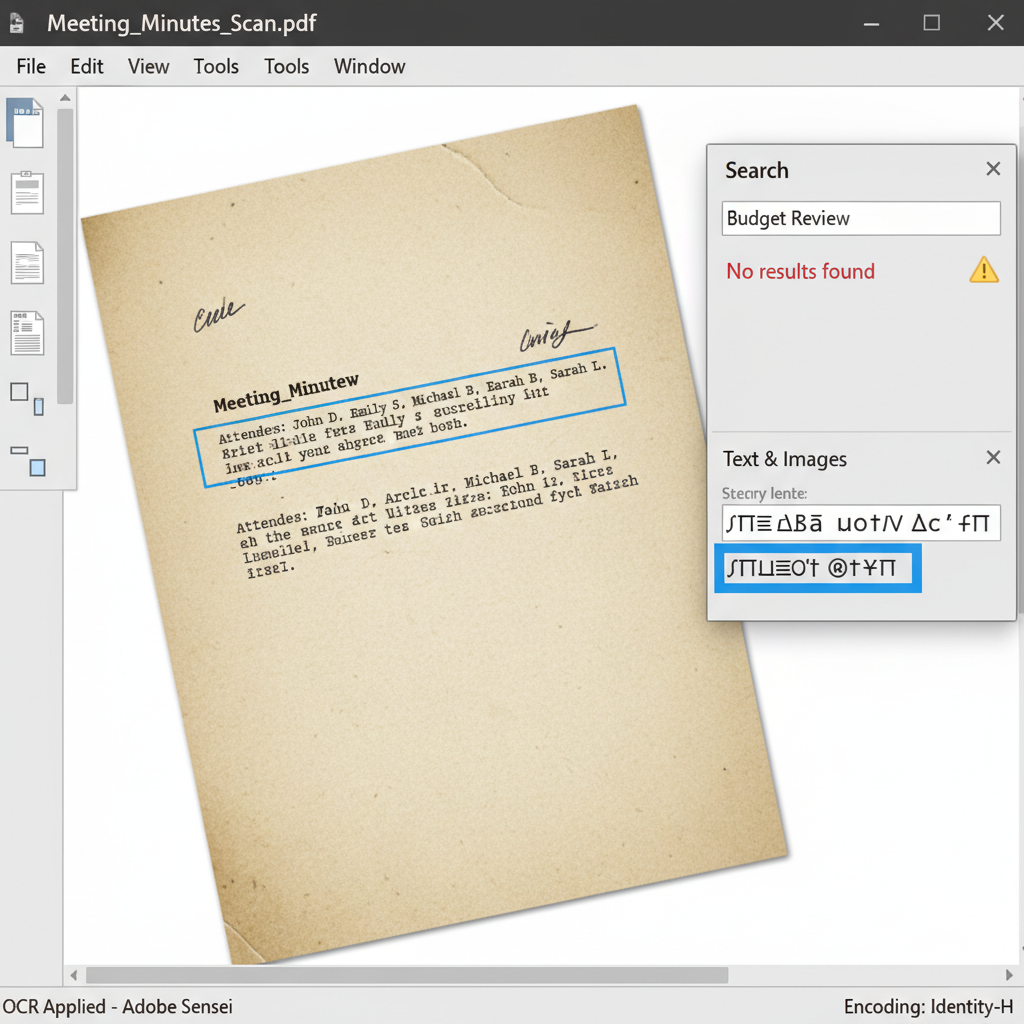
The user needs to fix scanned PDFs where text can be selected but cannot be searched or copied accurately after applying OCR.
- Product
- Acrobat Pro DC
- Device & OS
- not provided
- Scenario
- The user is attempting to run OCR on scanned documents to make the text searchable and extractable.
- Observed behavior
- Text can be highlighted, but search queries fail and copied text yields incorrect characters. The user suspects Identity-H font encoding or inaccurate text mapping is causing the issue.
Before proceeding, verify the visual clarity of your original scanned document. Ensure there are no heavy smudges, low contrast areas, or extreme skewing, as OCR accuracy depends entirely on a clean source image.
Improve Scan Quality and Re-run OCR
Enhance the source document's resolution and contrast before running text recognition again to ensure the OCR engine maps characters accurately.
Identity-H is simply a font encoding format used in PDFs for complex scripts or subset fonts. It does not mean the OCR process failed. Most unsearchable text issues stem from poor original scan quality, skewing, or low resolution. When the scan is poor, the OCR engine misinterprets words (for example, reading 'apple' as 'aple'), rendering the hidden text layer unsearchable.
Rescan the original physical document at a higher resolution, ideally 300 DPI or higher, ensuring the page is perfectly aligned and flat on the scanner glass.
Launch Acrobat Pro DC (or your preferred PDF editor) and open the newly scanned, high-quality PDF.
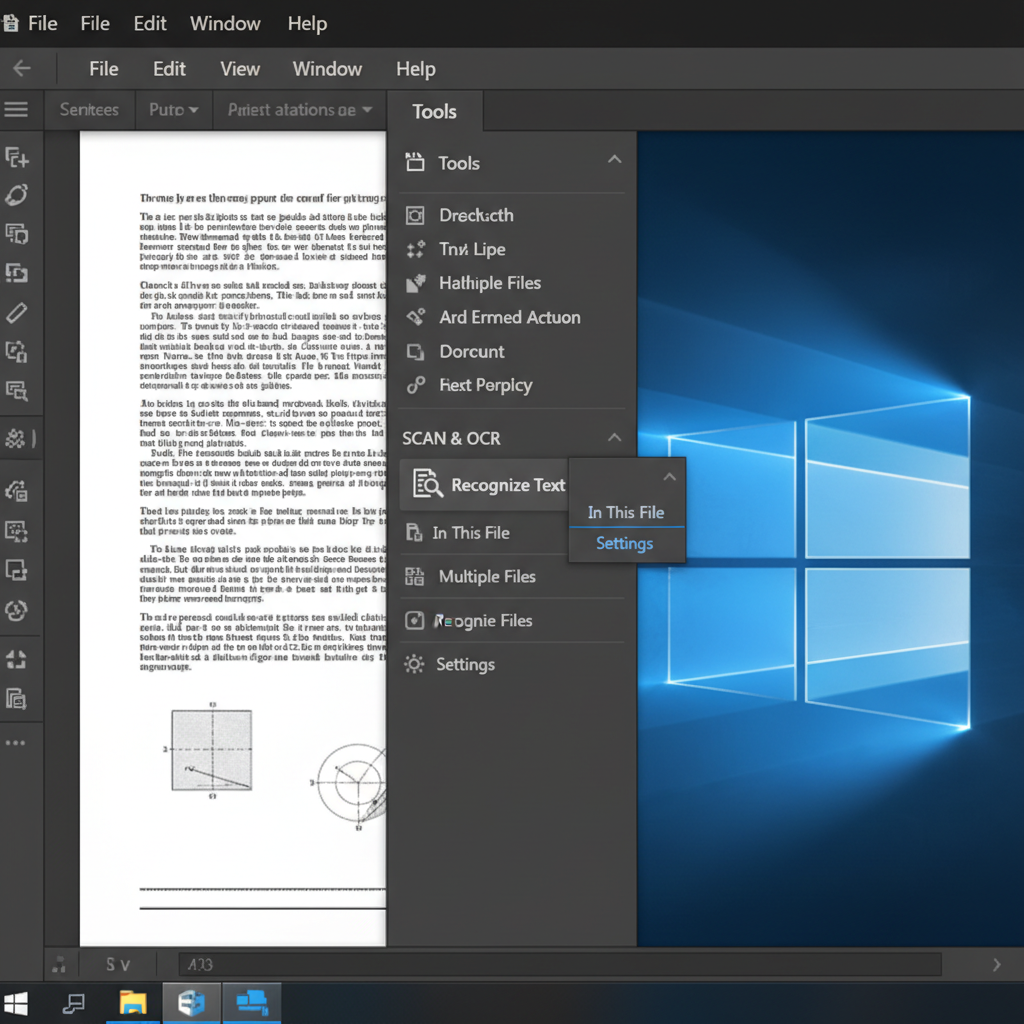
Navigate to the Tools menu and select 'Scan & OCR', then choose the 'Recognize Text' option.
Check the recognition settings to ensure the selected language perfectly matches the language of the document's text, then start the OCR process.
Press Ctrl+F (or Cmd+F on Mac) to open the Find tool, and search for a word that is clearly printed in the document to confirm the text is now searchable.
Accurately Extract and Search Text with WPS Office PDF OCR
WPS Office features a powerful, built-in OCR engine designed to accurately recognize text from scanned PDFs. It allows you to easily search, copy, and convert document content without dealing with complex Identity-H encoding issues or hidden text layer errors.
- 1. Open the PDF: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR feature: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Choose the extraction mode: Select your desired output, such as 'Extract Text' to grab raw text or 'Convert to Word' to retain formatting.
- 4. Start recognition: Ensure the correct document language is selected, then click 'Start' to process and create a searchable document.

Frequently Asked Questions
What does Identity-H encoding mean in a PDF?
Identity-H is a custom font encoding system used in PDF files, typically applied when embedding subset fonts or dealing with complex characters. While often noticed when text copying fails, it is not an error itself but rather a sign that the PDF lacks the correct Unicode mapping for the characters.
Why can I highlight text in my PDF but not search for it?
When you run OCR, a hidden, invisible text layer is placed over the scanned image so you can select text. If the search yields no results, it means the OCR engine mapped the visual characters to incorrect or garbled letters due to low scan quality, so the hidden word is spelled wrong.
How do I improve OCR accuracy on bad scans?
To significantly improve OCR accuracy, rescan your physical document at a minimum of 300 DPI. Ensure the page is straight, increase the contrast between the text and the background, and clear away any visual noise or shadows before running the text recognition tool.


