

How to Fix Acrobat OCR Not Making Scanned PDF Searchable

Question details
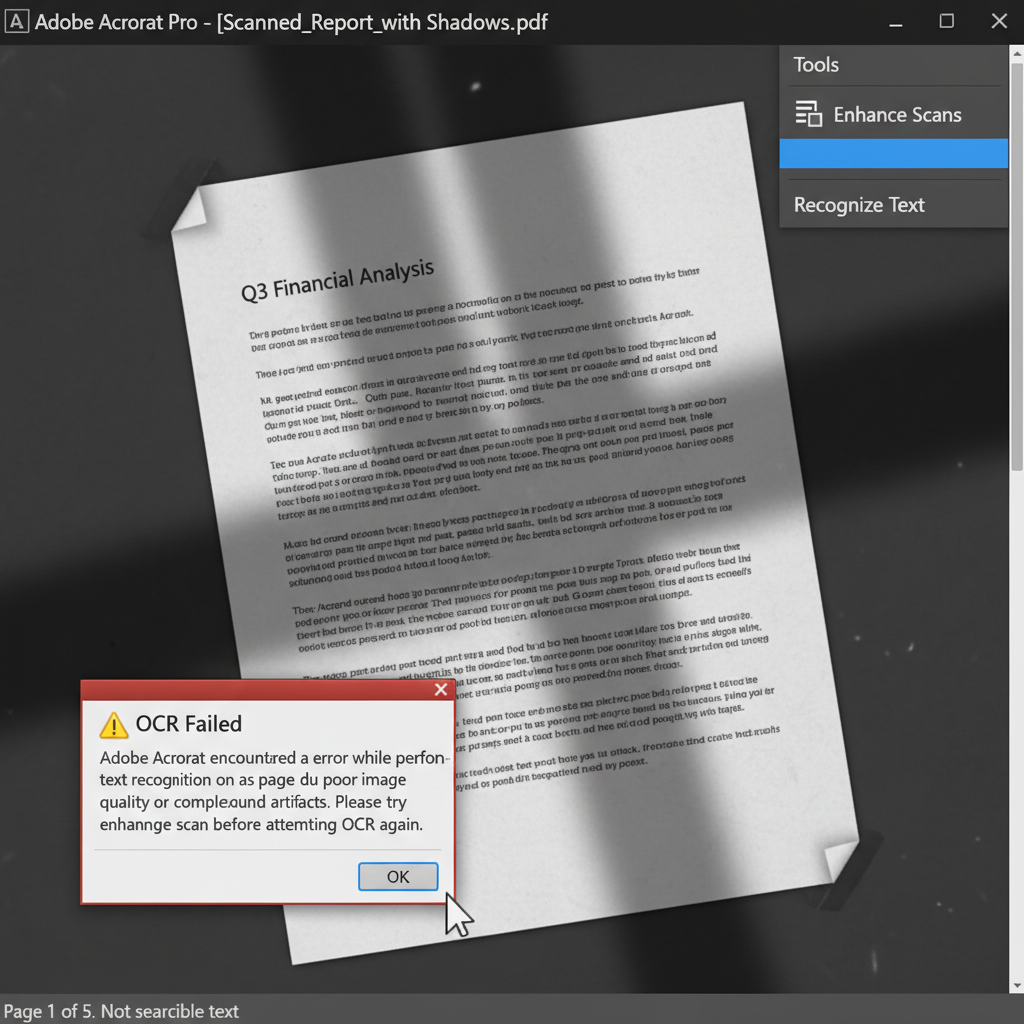
The user is unable to make a specific scanned PDF document searchable using the OCR function, likely due to background shadows or poor image quality.
- Product
- Adobe Acrobat Pro
- Device & OS
- not provided
- Scenario
- Attempting to perform OCR on a scanned PDF document to make the text searchable and selectable.
- Observed behavior
- OCR fails on one specific file despite working on others, leaving the text unsearchable due to background artifacts.
Before applying any fixes, save a backup copy of your original scanned PDF. Ensure that your PDF does not have security restrictions preventing content extraction or editing.
Enhance PDF Image Quality Before OCR
Since background shadows and low contrast interfere with text recognition, improving the image quality is the most effective way to make OCR work.
Optical Character Recognition (OCR) engines require clear contrast to distinguish letters from the background. Shadows, smudges, and skewed text lines significantly degrade accuracy.
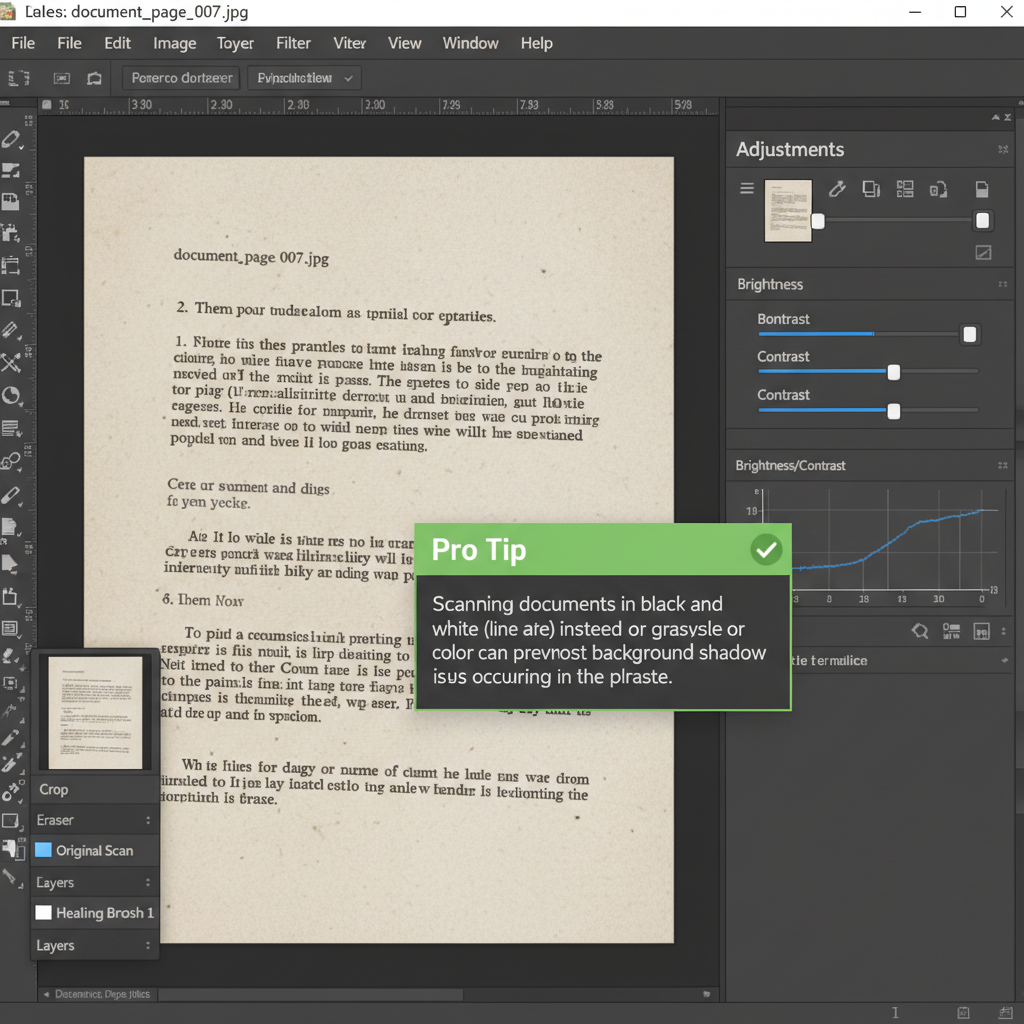
Export or extract the problematic pages of the PDF as high-resolution images (JPEG or PNG) to allow for detailed editing.
Open the images in an image-editing application. Increase the contrast and brightness to make the text stand out clearly against the background.
Use a crop or cleanup tool to remove dark borders, background shadows, and smudges. Ensure the text is perfectly horizontal, fixing any slanted angles.
Save the cleaned images and combine them back into a single PDF document, then run the OCR tool again.
Modify OCR Output Settings
Changing the OCR style or downsampling settings can sometimes bypass recognition errors on difficult scans.
Make Scanned PDFs Searchable with WPS Office
If your current software struggles with background shadows, try WPS Office. WPS PDF includes a highly accurate, built-in OCR engine that easily extracts text from scanned images and converts them into editable, searchable formats.
- 1. Open WPS PDF: Launch WPS Office and open your scanned PDF document in the WPS PDF editor.
- 2. Select OCR: Navigate to the 'Tools' tab and click on the 'OCR' button in the top toolbar.
- 3. Choose Conversion Option: Select 'Extract Text' or 'Convert to Searchable PDF' depending on your specific needs.
- 4. Start Recognition: Confirm your language settings and click 'Start' to process the document and make it fully searchable.

Frequently Asked Questions
Why does OCR fail on certain scanned PDFs?
OCR relies on clear contrast between text and background. Shadows, low resolution (under 300 DPI), skewed pages, or handwritten text can confuse the recognition engine, causing it to fail or produce gibberish.
Can I remove background shadows directly in a PDF editor?
Some advanced PDF editors have an 'Enhance Scan' or 'Background Removal' feature. However, severe shadows often require extracting the page as an image and using dedicated photo editing software to adjust levels and contrast before running OCR.
What is the optimal resolution for PDF OCR?
For the best OCR accuracy, scanned documents should be digitized at 300 DPI (dots per inch). Resolutions lower than 200 DPI often lead to poor text recognition, while extremely high resolutions increase file size without significantly improving OCR results.


