

Fix OCR Not Making Text Selectable in Acrobat XI Pro
Question details
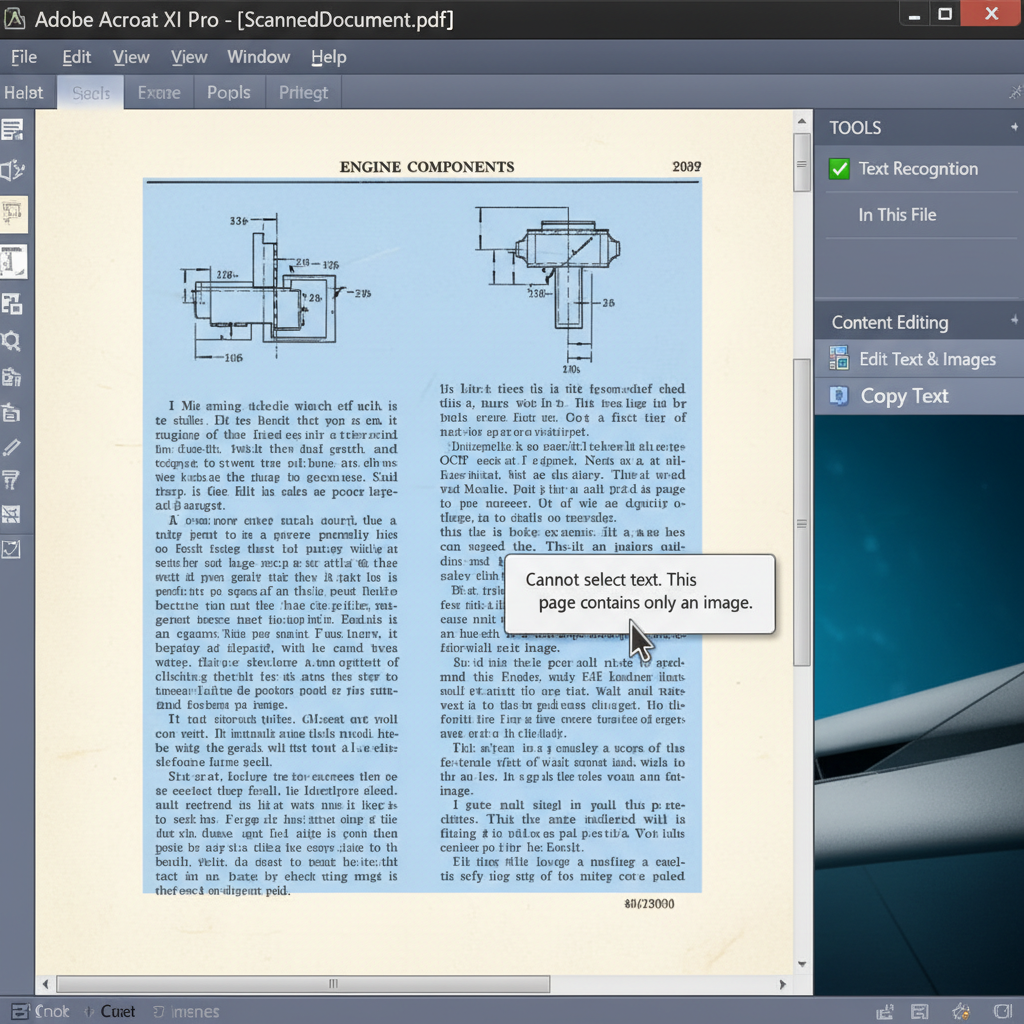
The user is unable to select or copy text from scanned PDFs after running OCR, as the document remains a flat image.
- Product
- Adobe Acrobat XI Pro
- Device & OS
- not provided
- Scenario
- Attempting to extract, select, or copy text from a scanned PDF document after performing Optical Character Recognition (OCR).
- Observed behavior
- The OCR process appears to run, but the document remains a flat image. Clicking the text selects the whole page with a blue overlay, indicating text cannot be highlighted or copied.
Ensure you have the original scanned PDF file saved before adjusting OCR settings, and verify that the document does not have security permissions restricting content copying.
Verify and Change the OCR Output Style Settings
Ensure the OCR tool is configured to output searchable text rather than leaving the page as an unselectable flat image.
When Acrobat processes a scanned document, it might be set to an output style that does not generate selectable text. Adjusting the PDF Output Style settings to generate a searchable layer usually resolves this issue.
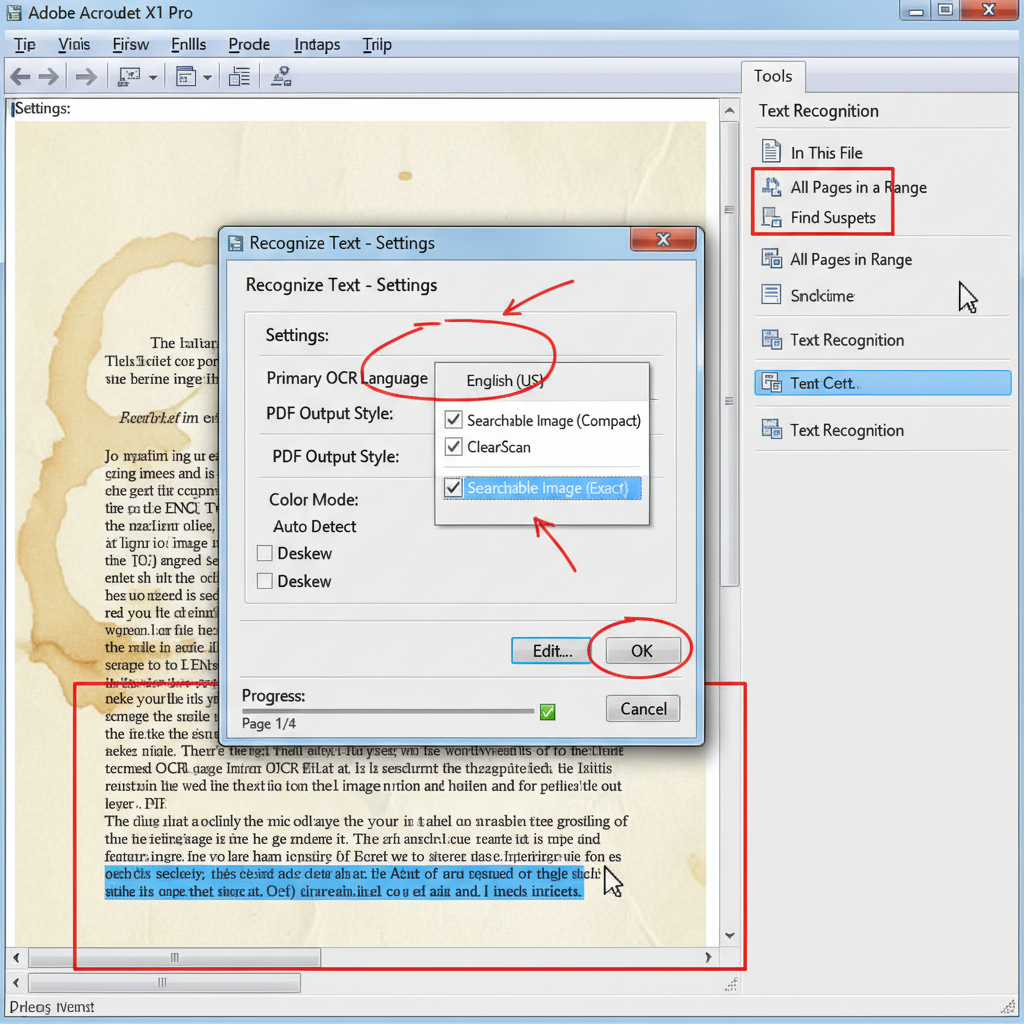
Launch Adobe Acrobat XI Pro, open your scanned PDF, and navigate to 'Tools' > 'Text Recognition' > 'In This File'.
In the Recognize Text dialog box, click on the 'Edit' button to open the detailed OCR settings menu.
Locate the 'PDF Output Style' dropdown and change it from its current state to 'Searchable Image (Exact)' or 'Clear Text'.
Click 'OK' to save the settings, then click 'OK' again to re-run the OCR process on the document. Once finished, try selecting the text.
Use WPS PDF to Extract and Select Text from Scanned Documents
If Acrobat XI Pro is failing to recognize your scanned pages, you can easily use the advanced OCR feature in WPS PDF to accurately convert flat images into selectable, editable, and searchable text.
- 1. Open your PDF: Launch WPS Office and open your scanned PDF document in the WPS PDF tab.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab and click on the 'OCR' button located in the top ribbon.
- 3. Select Output Mode: Choose whether you want to extract the text to a new Word/Excel document or make the current PDF searchable, then click to start the conversion.
- 4. Select and Copy Text: Once the OCR process completes, use your cursor to freely highlight, copy, or edit the newly recognized text.

Frequently Asked Questions
Why does a blue box appear when I click on my PDF text?
A blue overlay or box usually means the entire page is being selected as a single flat image. This indicates that the PDF has not been successfully processed by OCR to recognize individual text characters, or the processing was disabled.
Can I edit the text after running OCR in Acrobat XI Pro?
Yes, if the OCR output style is set correctly (such as 'Clear Text'), the text becomes searchable and copyable. To actively modify the text, you must then use the 'Edit Text & Images' tool.
Does WPS Office support OCR for scanned PDFs?
Yes, WPS PDF includes a powerful built-in OCR feature that can scan image-based PDFs and quickly convert them into editable Word documents, Excel spreadsheets, or text-searchable PDFs.
What if OCR fails to recognize text on a specific scanned document?
OCR failure can happen due to low image resolution, heavy background noise, or cursive handwriting. Try enhancing the scan quality or scanning the physical document again at a higher DPI (such as 300 DPI) before running the OCR process.


