

What is Identity-H in PDF Fonts? How to Fix Text Extraction Issues

Question details
The user needs to understand the meaning of the Identity-H font encoding in PDFs and how to resolve issues where text cannot be properly extracted or copied.
- Product
- Device & OS
- not provided
- Scenario
- Copying or extracting text from a PDF file containing Identity-H encoded fonts.
- Observed behavior
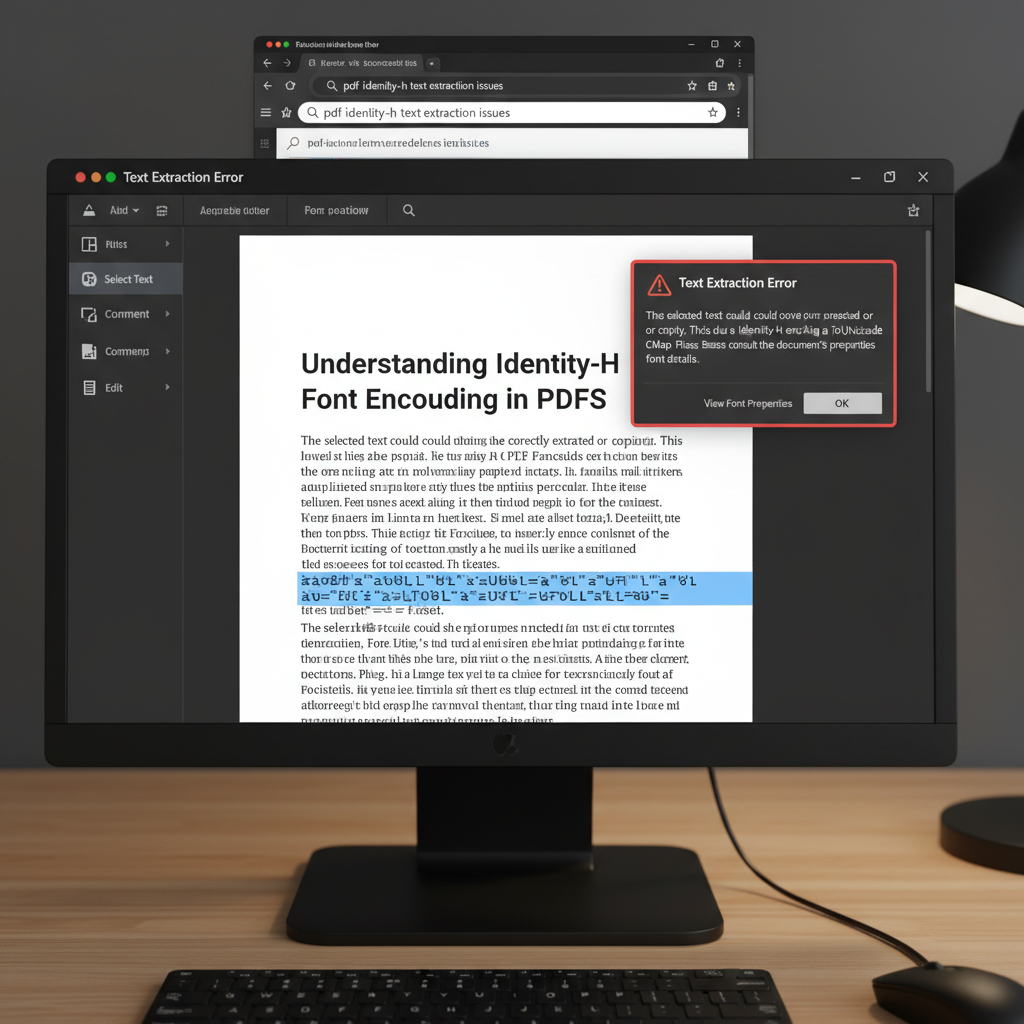
- Text extraction fails or produces incorrect characters because the PDF lacks a correct ToUnicode CMap, despite the Identity-H encoding itself being normal.
Verify whether the text extraction issue occurs across multiple PDF viewers or just one, and ensure you are not dealing with a scanned document that requires OCR instead of standard text extraction.
Export the PDF Using Unicode Fonts and Modern Tools
Re-exporting the original document using standard Unicode OpenType or TrueType fonts ensures a proper ToUnicode mapping is generated for text extraction.
Identity-H is a normal font encoding method that maps character codes directly to visual glyphs. However, for a computer to understand what those glyphs mean when you copy text, the PDF must include a ToUnicode CMap.
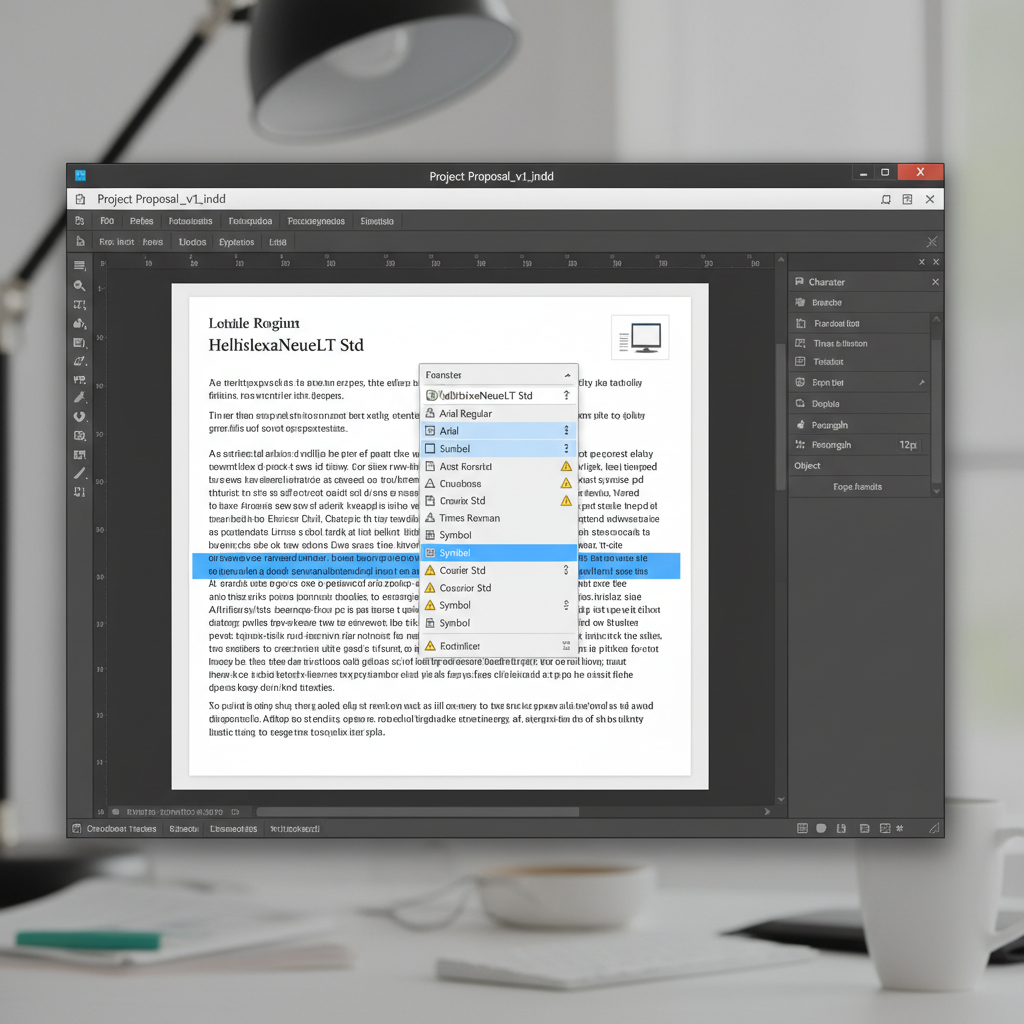
Using legacy or non-Unicode fonts when creating a PDF often omits this essential mapping. To resolve this, you must recreate the PDF from the original source file using modern standards.
Open the original source document in a modern authoring tool like Adobe InDesign, Microsoft Word, or WPS Office.
Highlight the text and replace any legacy, non-Unicode fonts with standard Unicode OpenType or TrueType fonts (such as Arial, Times New Roman, or Calibri).
Export the document to PDF using built-in PDF export functions or Acrobat PDFMaker. Ensure that 'Embed Fonts' and 'Accessibility' options are checked in the export settings to preserve the ToUnicode CMap.
Extract Text Using OCR (Optical Character Recognition)
Use OCR technology to visually read and extract text when you do not have access to the original source document to re-export it.
Easily Create and Export Standard PDFs Using WPS Office
WPS Office provides seamless PDF creation and editing tools. By exporting your Word, Excel, or PowerPoint documents to PDF with WPS Office, you ensure proper font embedding and text extraction without worrying about Identity-H mapping errors.
- 1. Open your Document: Open your original document (Word, Excel, or PowerPoint) in WPS Office.
- 2. Access PDF Export: Go to the 'Menu' tab and select 'Export to PDF'.
- 3. Check Export Settings: In the export dialog, click 'Advanced Settings' and ensure standard font settings are applied so fonts are properly mapped.
- 4. Save the PDF: Click 'Export' to save your file as a standard, easily extractable PDF document.

Frequently Asked Questions
Is Identity-H an error in my PDF file?
No, Identity-H is a standard and common font encoding method used in PDFs to map character codes directly to visual glyphs. It is completely normal for displaying text. However, text extraction relies on an additional component called the ToUnicode CMap, which is sometimes missing.
Why does my copied text show up as gibberish or square boxes?
This happens when the PDF lacks a correct ToUnicode CMap. Without it, your computer doesn't know how to translate the visual glyphs (Identity-H) back into standard text characters like letters and numbers when you try to copy them.
How can I tell if my PDF has a correct ToUnicode mapping?
You can test this by selecting a paragraph of text in your PDF viewer, copying it, and pasting it into a plain text editor like Notepad. If the text appears correctly, the mapping exists. If it appears as random characters or symbols, the ToUnicode mapping is missing or broken.
Can I fix the Identity-H extraction issue without the original file?
Fixing the internal font encoding of a PDF without the source file is extremely difficult. The most reliable workaround is to use a PDF editor with Optical Character Recognition (OCR) to read the document visually and extract the text.


