

How to Decode PDF Text Strings with Type 0 Fonts and Identity-H

Question details
The user needs to understand how to correctly extract and decode text strings from a PDF content stream that utilizes Type 0 fonts and Identity-H encoding.
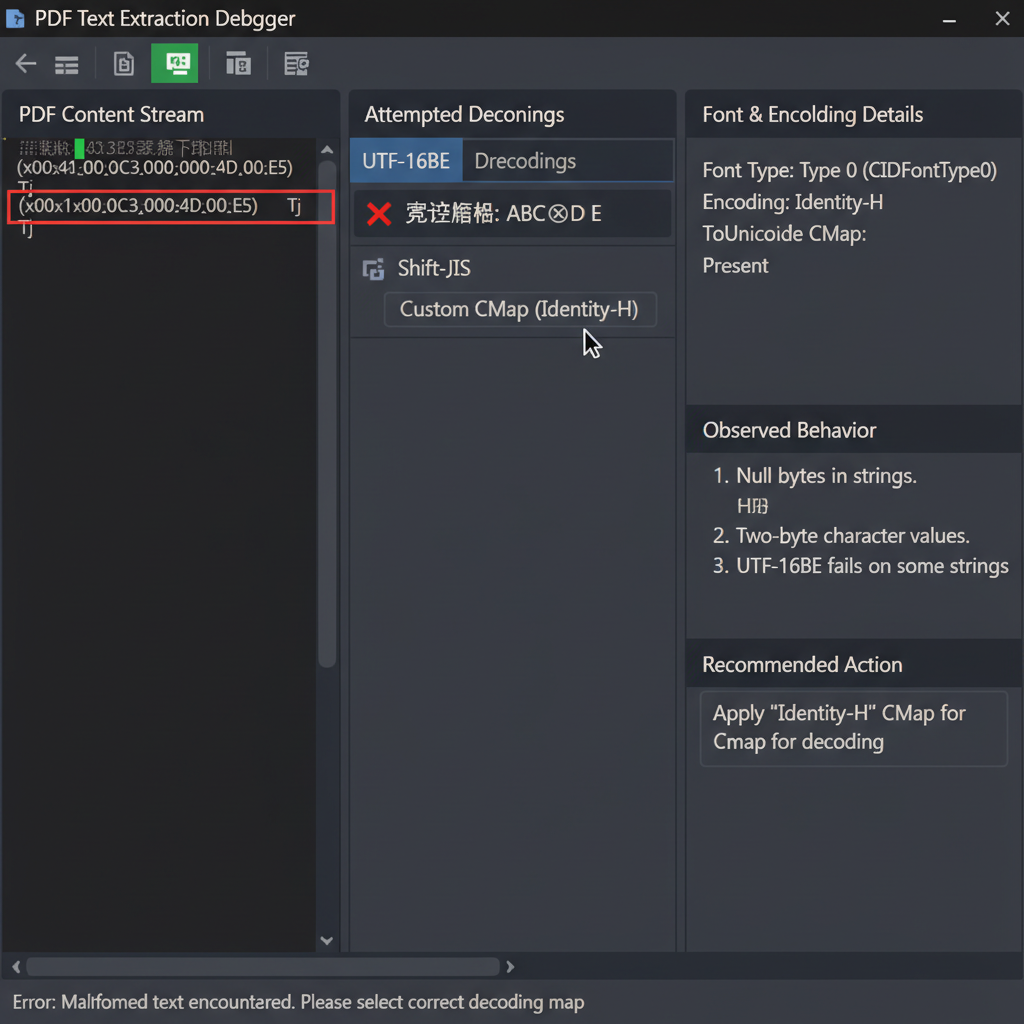
- Product
- Device & OS
- not provided
- Scenario
- Extracting text from a PDF content stream where text strings contain null bytes and two-byte character values.
- Observed behavior
- Attempting to use standard UTF-16BE decoding works for some strings but corrupts others, indicating that the text is not standard Unicode and requires a specific decoding map.
Before attempting to extract text programmatically, ensure you have access to the PDF's internal font dictionaries, specifically the ToUnicode map and CMap associated with the Type 0 font in use.
Extract Text using the Descendant CMap and ToUnicode Map
This is the correct, standard method for extracting and decoding text from PDFs utilizing Type 0 fonts with Identity-H encoding.
Do not assume that a PDF string using a Type 0 font with Identity-H encoding is standard UTF-16BE text. The string contains character codes or character identifiers (CIDs), not necessarily Unicode characters.
To get accurate text extraction, you must map these identifiers back to actual Unicode characters rather than reading the raw bytes directly.
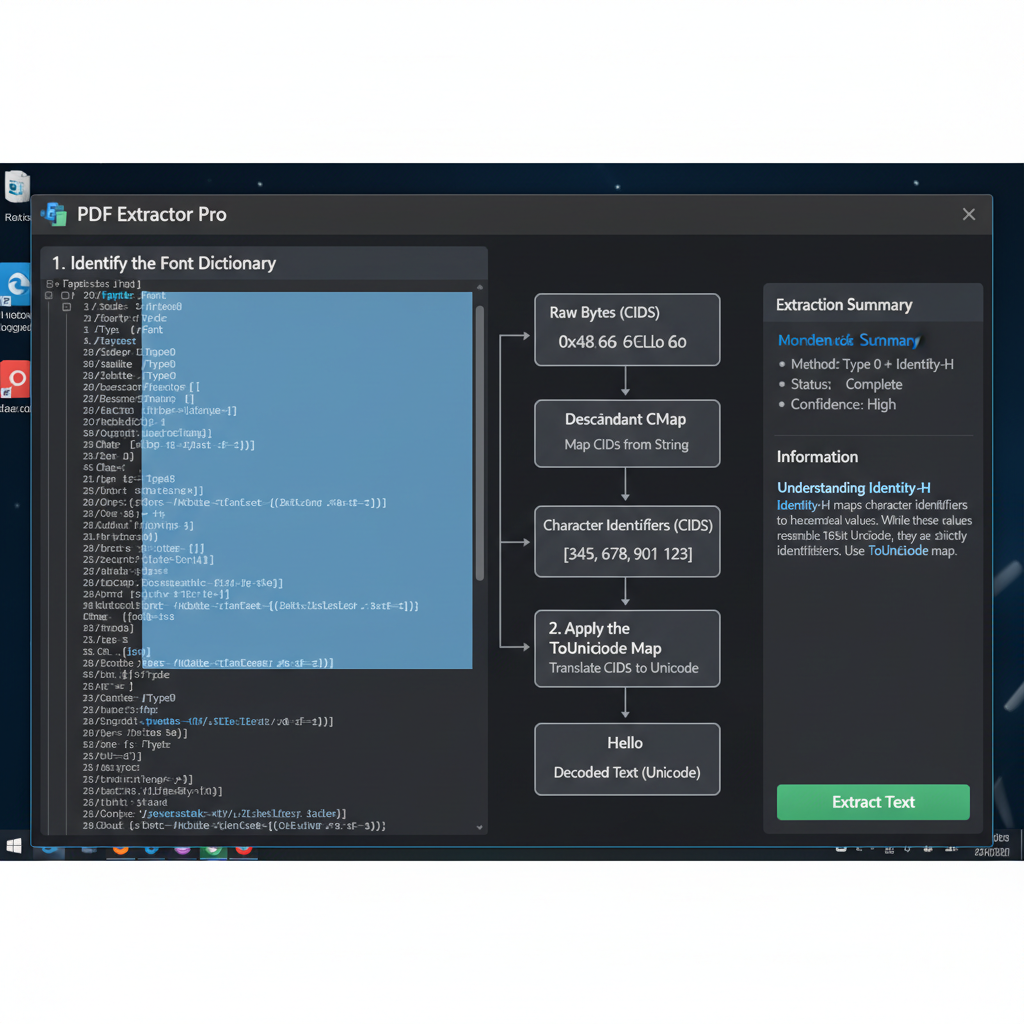
Locate the Type 0 font and its descendant font definitions within the PDF's internal content stream.
Read the raw character codes from the string and use the font's descendant CMap to map these codes into proper Character Identifiers (CIDs).
Take the resulting CIDs and process them through the font's ToUnicode map (provided in the font dictionary) to translate them into correct, readable Unicode text.
Extract Text Seamlessly with WPS PDF
If you want to extract text without dealing with the technical complexities of Character Identifiers and ToUnicode maps, WPS PDF handles these complex font encodings automatically, allowing you to copy or convert text instantly.
- 1. Open your PDF document: Launch WPS Office and open the PDF file you wish to extract text from.
- 2. Select the target text: Click and drag your cursor over the text. WPS PDF automatically decodes the underlying Identity-H characters into readable text.
- 3. Copy or Convert: Right-click to select 'Copy', or navigate to the Toolbar and use the 'PDF to Word' conversion tool to extract the entire document into an editable format.

Frequently Asked Questions
Why does my extracted PDF text show up as gibberish or null bytes?
This usually happens when the PDF uses a custom font encoding like Identity-H, and the extraction tool incorrectly assumes the text is encoded in a standard format like UTF-16BE. You need to decode the text using the font's internal ToUnicode map.
What is Identity-H in a PDF document?
Identity-H is a predefined CMap (Character Map) used in PDFs to map character codes directly to Character Identifiers (CIDs) horizontally. It does not directly map to Unicode characters, which is why a separate ToUnicode table is required for accurate text extraction.
Can I use standard UTF-16BE to decode Identity-H fonts?
No. While assuming Identity-H strings are UTF-16BE might coincidentally work for some specific characters, it will inevitably corrupt others. Always rely on the CMap and ToUnicode map to accurately resolve character identities.
Where is the ToUnicode map located in a PDF?
The ToUnicode map is typically embedded within the Font Dictionary of the PDF. When parsing the PDF structure, you must look up the specific font referenced by the text string to find its associated ToUnicode stream.


