



Fix Missing or Unreadable Text in PDF to Word Conversion

Question details
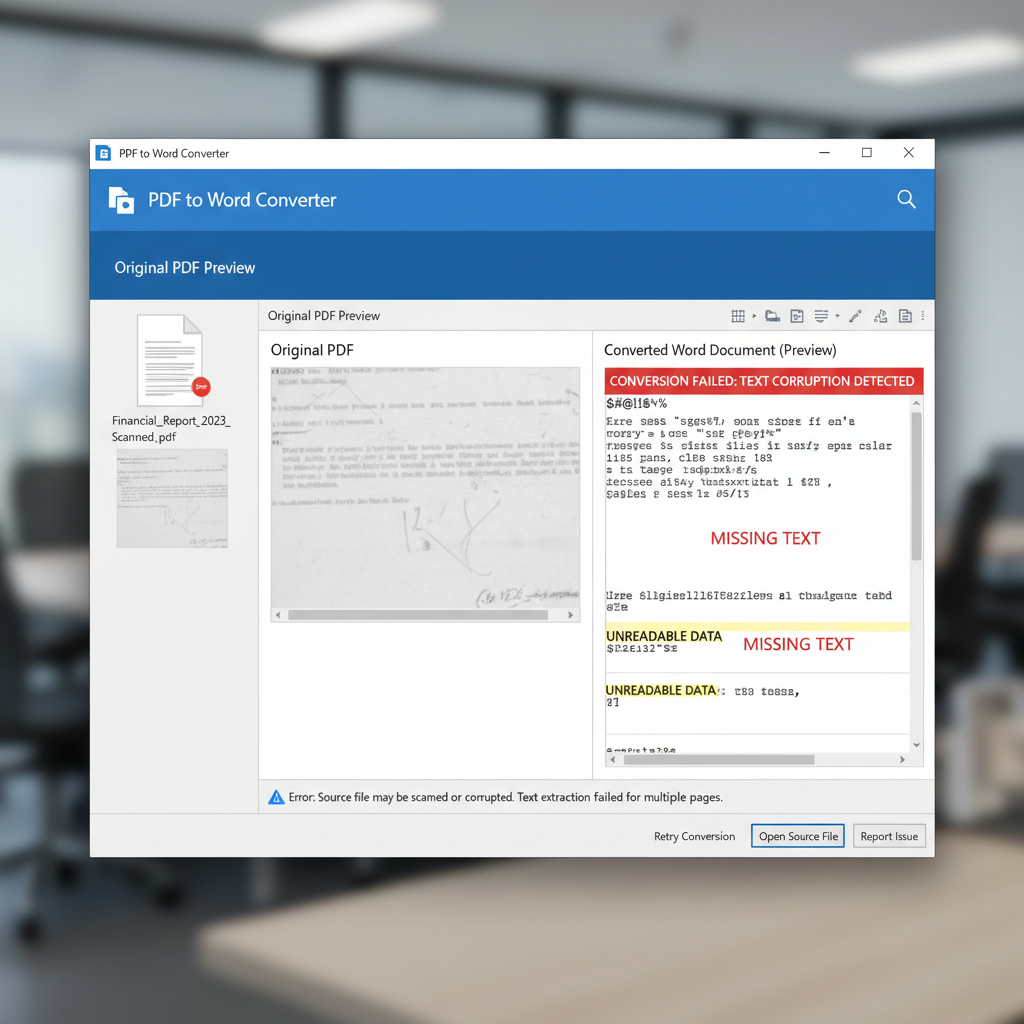
The user experiences missing, damaged, or illegible text after converting a PDF document into a Microsoft Word file.
- Product
- PDF to Word Converter
- Device & OS
- not provided
- Scenario
- Converting a PDF file to a Microsoft Word document for text editing and formatting.
- Observed behavior
- The resulting Word document contains missing, corrupted, or completely unreadable text, which is often caused by the original source file being a scan or corrupted.
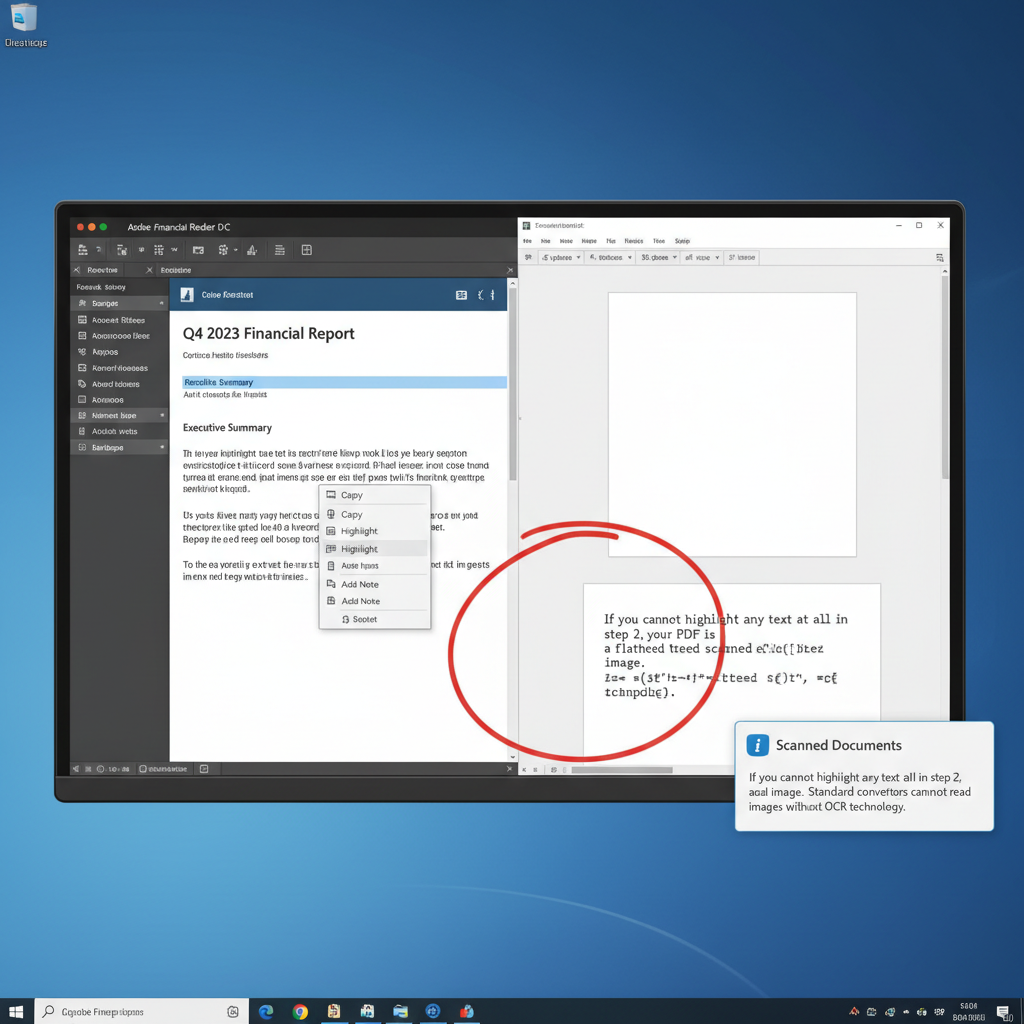
Before trying different conversion tools, verify if the original PDF document contains actual text layers or is merely a scanned image by attempting to highlight text in a standard PDF reader.
Test and Replace the Source PDF File
Verify if the issue originates from a corrupted source PDF or a poor-quality scan by performing a manual copy-paste test.
In many cases, conversion errors are not caused by the converter itself, but by a corrupted source file or a PDF created from a low-quality image scan. By manually extracting text, you can determine the health of the original document.
Launch a standard PDF reader like Adobe Acrobat Reader or WPS Office and open the problematic PDF file.
Attempt to highlight a paragraph of text using your mouse cursor, right-click the selection, and choose 'Copy'.
Open a blank Microsoft Word document, right-click on the page, and select 'Paste'.
Review the pasted text. If it is already unreadable, missing characters, or shows gibberish, the source file is corrupted or lacks proper text encoding.
If the text is corrupted, contact the document author to obtain a corrected source file or recreate the PDF with clear, selectable text before attempting to convert it again.
Use an OCR-Enabled Converter for Scanned PDFs
If your original PDF is an image or a scan without selectable text layers, use a converter equipped with Optical Character Recognition (OCR) to accurately extract the text.
Convert PDFs to Word with High Accuracy Using WPS Office
WPS Office features a powerful PDF to Word converter with built-in advanced OCR capabilities, ensuring that even scanned documents are accurately translated into editable Word files without missing or corrupted text.
- 1. Install WPS Office: Download, install, and open WPS Office on your computer.
- 2. Open your PDF: Click on the 'PDF' tab on the home screen and open your problematic PDF file.
- 3. Select PDF to Word: Navigate to the 'Tools' menu at the top and click on 'PDF to Word'.
- 4. Enable OCR and Convert: Check the 'OCR' box if your document is a scanned image, select your desired output folder, and click 'Start'.
- 5. Review the Output: Open the newly created Word document to verify that the text has been successfully extracted and is fully readable.
Frequently Asked Questions
Why does my converted Word document show weird symbols instead of text?
This usually happens when the original PDF uses custom or embedded fonts that are missing from your computer's system, or when the file has corrupted font encoding. It can also occur if standard conversion is used on a low-quality scanned image.
How can I tell if my PDF is a scanned image?
Open the PDF in any standard viewer and try to highlight a single sentence with your mouse. If you cannot highlight individual words, or if the entire page gets highlighted in blue as a single block, the document is a scanned image.
Can I convert a password-protected PDF to Word?
Yes, but you must first enter the correct permission password to unlock the document. Conversion software cannot read, extract, or convert text from an encrypted PDF without the owner password.
Will OCR fix heavily blurred or damaged PDF text?
OCR (Optical Character Recognition) technology relies on visual clarity to identify letters. If the original scan is heavily blurred, faded, or contains handwritten scribbles, the OCR engine may struggle to accurately recognize characters, which can still result in typos or missing words.


