

How to Export Data from Scanned PDFs and JPEGs to Excel
Question details
The user needs to accurately convert tabular data, such as cellphone records, from scanned PDFs or JPEG images into an editable Excel spreadsheet without generating scrambled text.
- Product
- PDF to Excel OCR Converter
- Device & OS
- not provided
- Scenario
- Converting images or scanned documents containing fragmented text, numbers, and tables into a structured Microsoft Excel format.
- Observed behavior
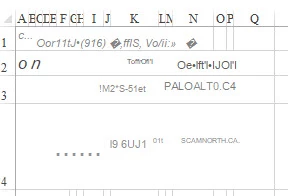
- The OCR process produces scrambled and inaccurate text instead of correctly formatted data due to poor image compression and the lack of contextual sentences in the source file.
Ensure you have access to the original, highest-resolution version of your scanned document or image before attempting the conversion. High-quality source files drastically improve OCR accuracy.
Optimize Image Quality and Format for OCR
Improve OCR accuracy by using lossless, high-resolution image formats instead of compressed JPEGs.
JPEG is a lossy format, meaning it loses detail and clarity every time it is saved. This compression severely impacts OCR accuracy because OCR engines rely on crisp edges to recognize characters correctly. Switching to a lossless format and maximizing resolution provides the OCR engine with the best possible input to interpret fragmented data like phone records.
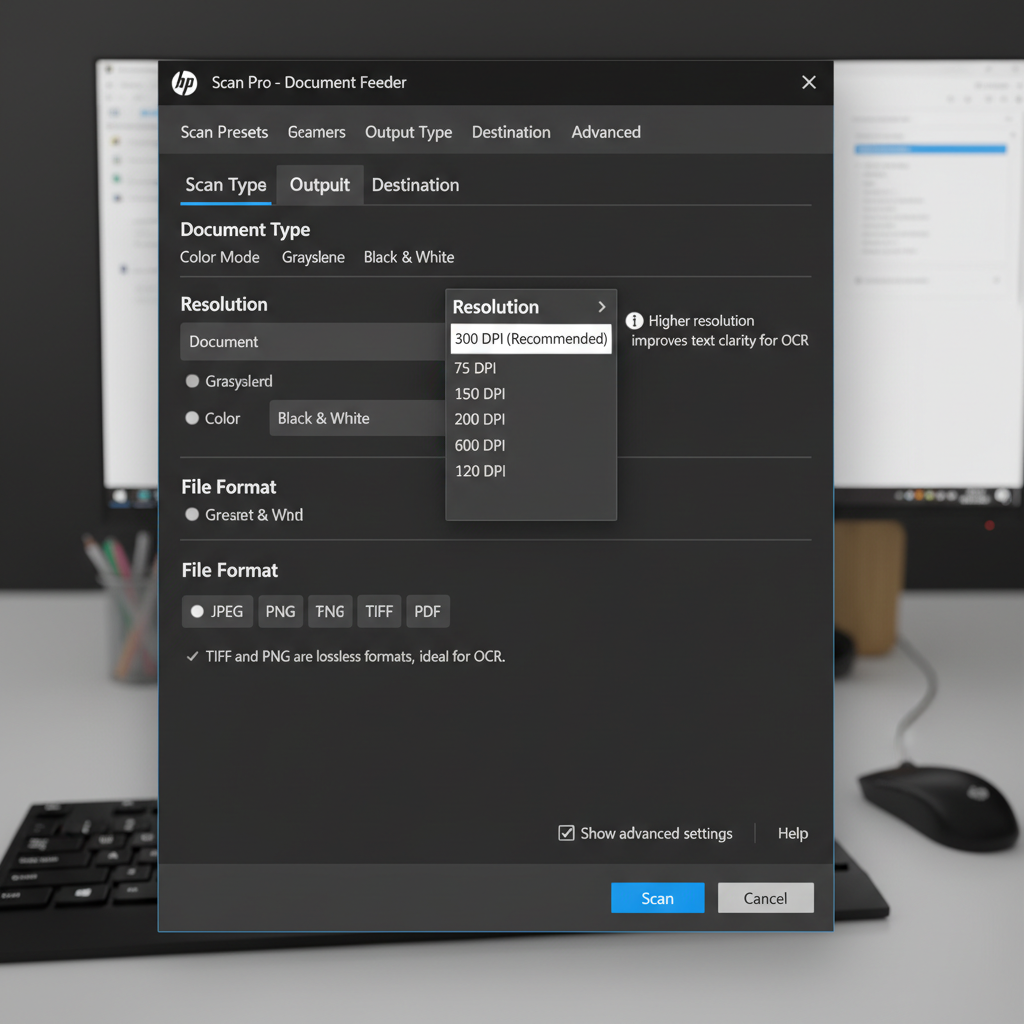
Ask the document creator to scan or export the original file as a lossless format, such as PNG or TIFF, rather than JPEG.
If you are scanning the document yourself, open your scanner settings and set the resolution to a minimum of 300 DPI to capture clear, crisp text.
Do not edit and re-save JPEG files multiple times before importing them into your OCR conversion software, as this compounds quality loss.
Manually Re-key Fragmented Data
Manual entry is sometimes the only reliable method for highly fragmented or complex tabular data that confuses OCR algorithms.
Convert Scanned PDFs to Excel Seamlessly with WPS Office
WPS Office features a powerful built-in OCR engine that efficiently extracts data from scanned PDFs and images, formatting it directly into highly compatible Excel spreadsheets.
- 1. Access the PDF toolkit: Open WPS Office and click on the 'PDF' tab on the home screen to access the comprehensive PDF toolkit.
- 2. Select PDF to Excel: Click on 'PDF to Excel' and use the file browser to add your scanned PDF or high-resolution image file.
- 3. Enable OCR settings: In the conversion dialog box, ensure the OCR option is checked and select the correct document language to improve recognition accuracy.
- 4. Convert and save: Click the 'Convert' button to extract the data. Once finished, WPS will automatically open the editable Microsoft Excel (.xlsx) file.
Frequently Asked Questions
Why does OCR scramble numbers and times in cellphone records?
OCR relies heavily on language context, spell checkers, and continuous lines of text. Fragmented data like standalone numbers and times lack this context, which confuses the OCR engine and often leads to scrambled or misinterpreted outputs.
Is JPEG a good format for OCR conversion?
No, JPEG is a lossy compression format that removes fine image details. This can blur text edges and drastically reduce OCR accuracy. Lossless formats like PNG or TIFF are much better suited for OCR tasks.
What is the minimum DPI required for accurate OCR scanning?
For optimal OCR results, it is recommended to scan documents at a minimum of 300 DPI (dots per inch). This ensures the text is sharp and large enough for the software to accurately distinguish individual characters.


