

How to Fix Acrobat Action Stopping During PDF Text Extraction

Question details
The user needs to resolve an issue where an automated Acrobat Action fails and halts when searching, highlighting, or extracting text from problematic PDFs.
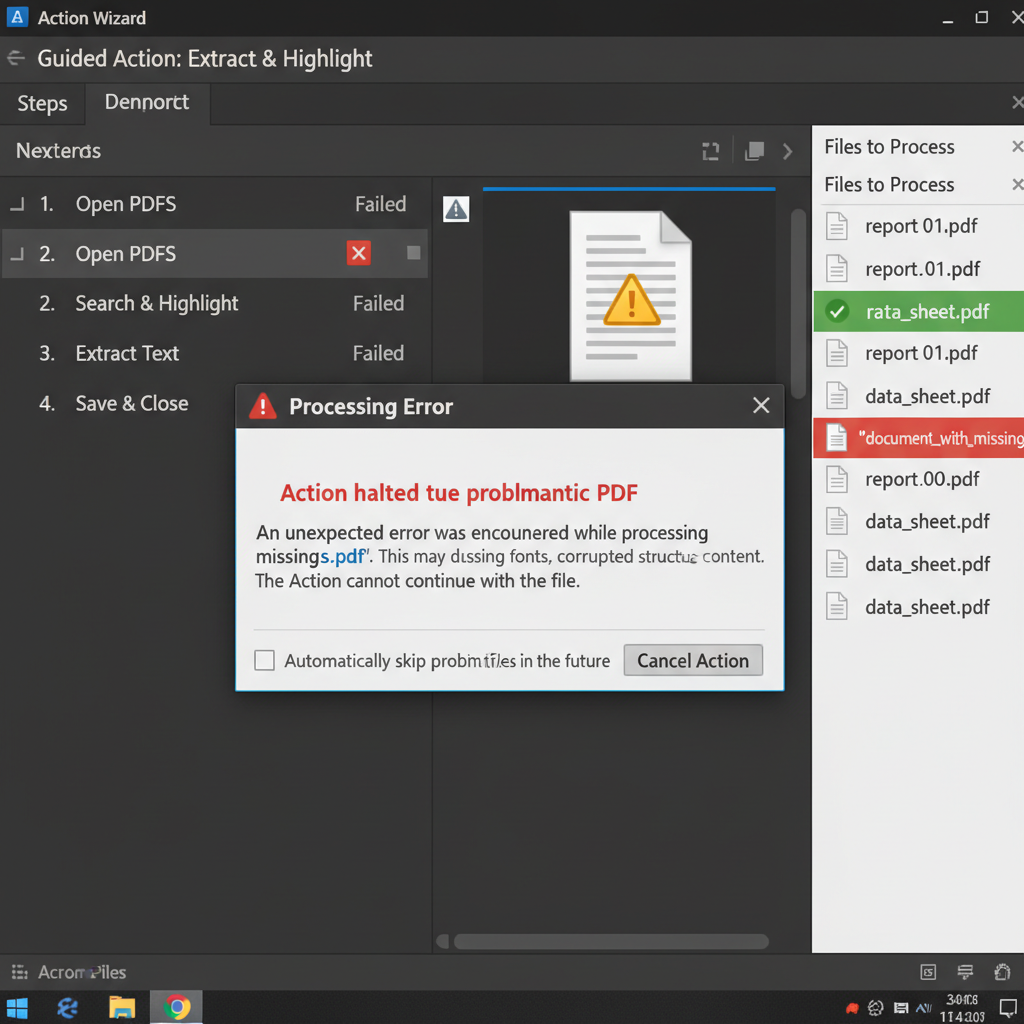
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Running a guided Acrobat Action to automatically search, highlight, and extract words across a batch of PDF documents.
- Observed behavior
- The Action completely stops processing the batch when it encounters a PDF with missing fonts, bad structure, or corruption, displaying an import or processing error instead of skipping to the next file.
Before attempting to modify your Acrobat Action or custom script, make a backup copy of your batch PDF files to prevent accidental data loss during testing.
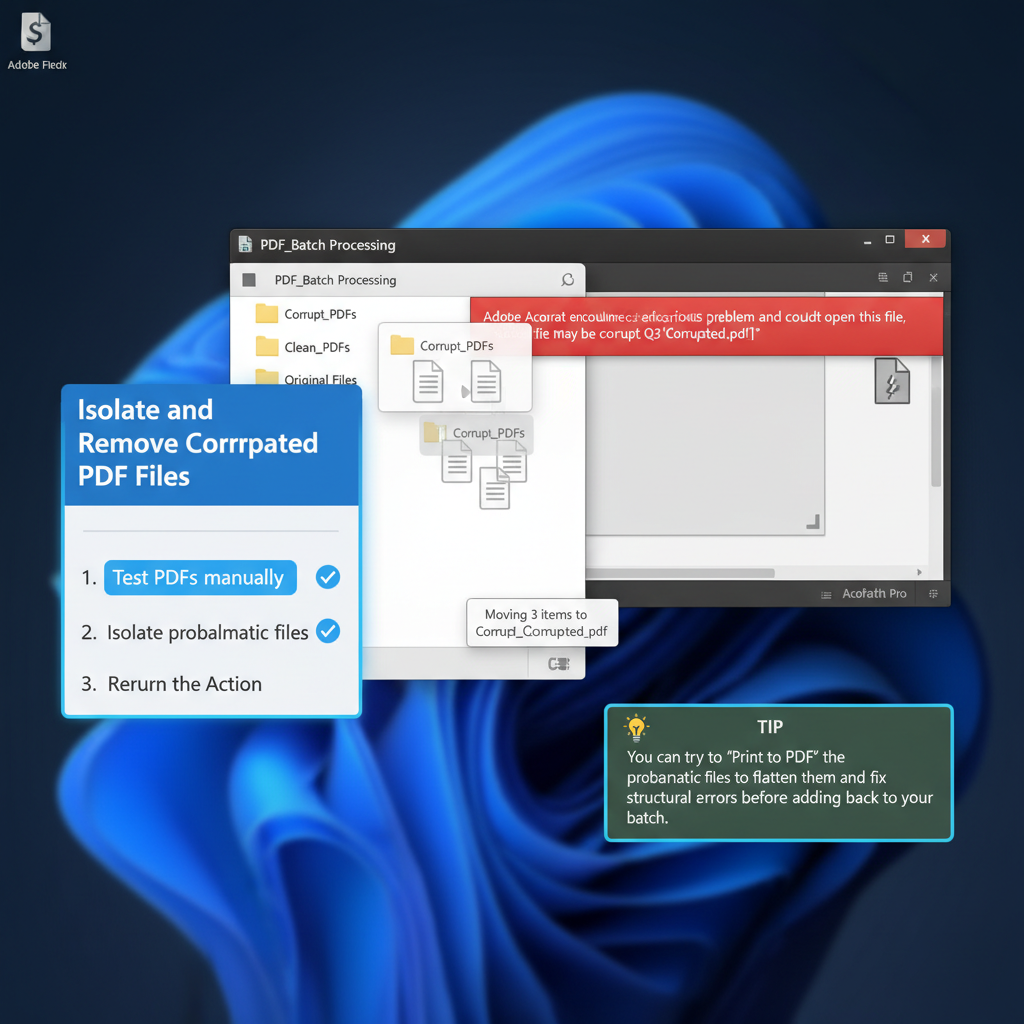
Isolate and Remove Corrupted PDF Files from the Batch
Identify which specific PDF files are triggering the import error so you can remove them and allow the Action to process the remaining clean files.
Acrobat Actions are designed to process files sequentially, but severe document corruption or missing embedded fonts can trigger a fatal import error, halting the entire queue.
Open the PDF files in your batch folder one by one in Adobe Acrobat. Look for any files that immediately throw an 'invalid or corrupt' warning upon opening.
Move the corrupted or unreadable PDF files into a separate folder, removing them from the main processing queue.
Restart your guided Acrobat Action on the remaining valid files to confirm the batch processing works without interruption.
Update the Extraction Script to Handle Errors
Modify the custom JavaScript within your Acrobat Action to log errors and skip failing files rather than stopping completely.
Search and Extract PDF Text Effortlessly with WPS PDF
If custom Acrobat scripts and Actions are causing workflow interruptions, switch to WPS Office. The built-in WPS PDF tool offers robust, native features to search, highlight, and extract text from PDFs. It gracefully handles structural issues and scanned documents without requiring complex JavaScript programming.
- 1. Open the PDF: Launch WPS Office and open your target PDF document.
- 2. Search and highlight: Use the 'Search' tool to find specific keywords, then use the 'Highlight' feature under the Comment tab to mark them.
- 3. Extract text: Select the text directly, right-click, and choose 'Copy', or use the 'PDF to Word' tool in the Home tab to convert and extract the entire document's contents effortlessly.

Frequently Asked Questions
Why does my Acrobat Action say the file is invalid or corrupt?
This error occurs when a PDF file in your batch lacks proper structural tags, contains missing or corrupted embedded fonts, or has suffered data corruption. The Acrobat extraction script stops because it cannot parse the expected text data.
Can I make an Acrobat Action skip errors and continue?
Standard guided Actions typically halt on critical processing errors. To bypass errors, you must modify the custom JavaScript step within the Action, wrapping the extraction code in try/catch blocks to log the failure and skip to the next file.
How do I fix font or structure problems in a PDF?
You can resolve many structural and font issues by opening the problematic PDF and using the 'Print to PDF' feature. This flattens the document and creates a clean new PDF structure that extraction scripts can read more easily.


