

How to Fix PDF Font Errors Preventing Text Extraction

Question details
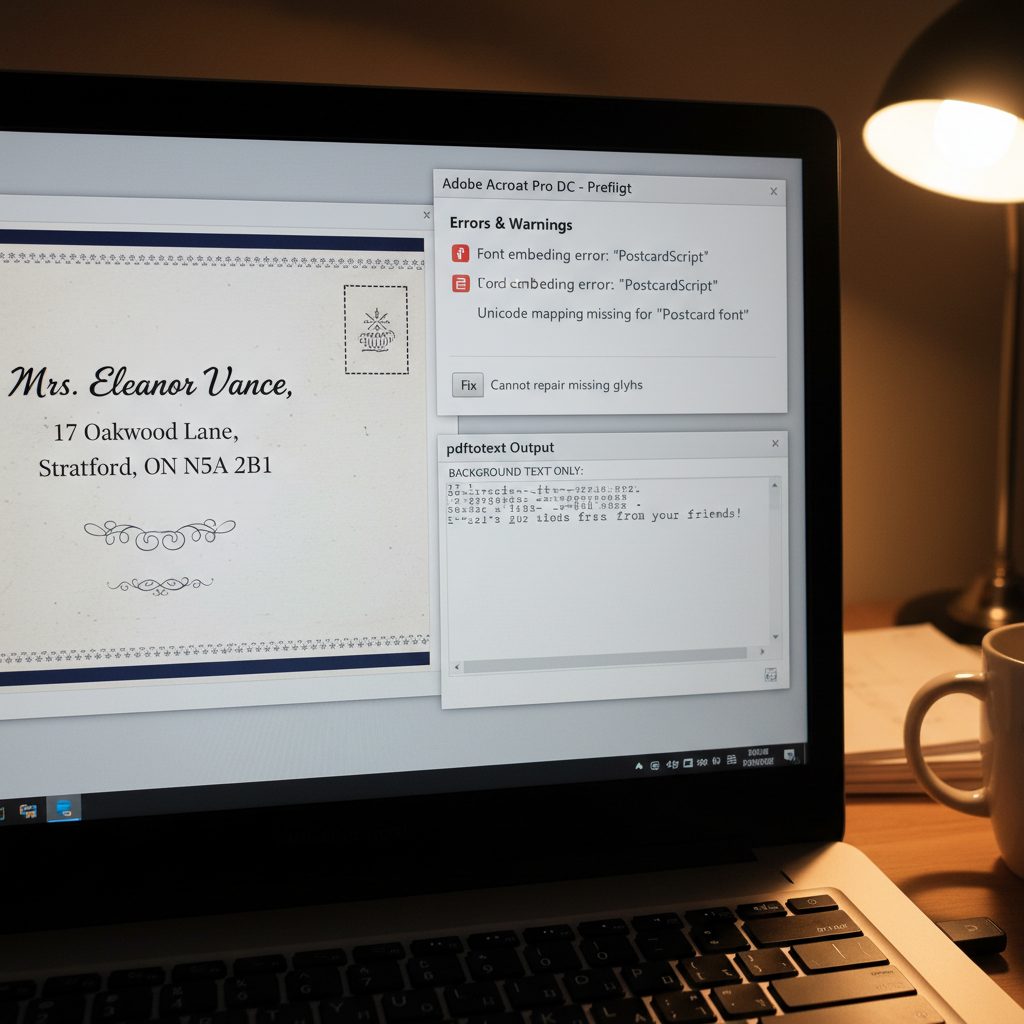
User is unable to extract names and addresses from postcard PDFs due to font type mismatches and missing Unicode mappings.
- Product
- Device & OS
- not provided
- Scenario
- Attempting to extract specific text like names and addresses using tools like pdftotext or Adobe Acrobat, but the extraction fails or yields only background text.
- Observed behavior
- Font errors prevent standard text extraction. Fixing the error with Preflight tools results in only background text being recovered because the foreground text cannot be mapped to Unicode.
Verify whether the text in the PDF can be highlighted and copied manually into a text editor; if the pasted text appears as gibberish, the font mapping is corrupted and you will need to rely on optical character recognition (OCR).
Use OCR (Optical Character Recognition) to Recreate Text
When a PDF's underlying font data is corrupted or lacks proper Unicode mapping, using OCR visually scans the document to generate entirely new, extractable text.
PDF text extraction tools rely on internal dictionaries to map visual font characters to actual letters (Unicode). When this mapping is broken or the embedded font is mismatched, traditional text extraction fails.
By treating the problematic PDF pages as images and running an OCR scan, the software bypasses the broken underlying font code and accurately reconstructs the text based on its visual appearance.
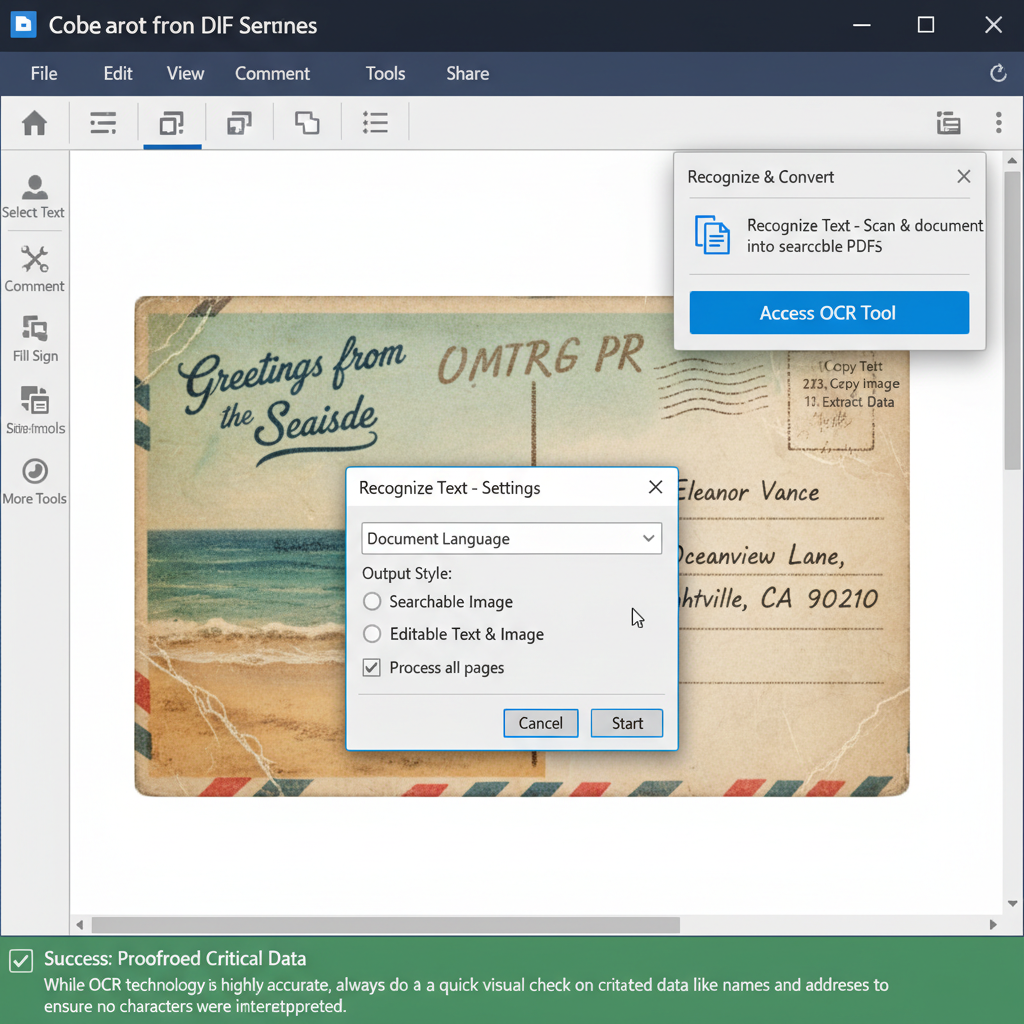
Launch a professional PDF editor equipped with OCR capabilities, such as WPS Office or Adobe Acrobat, and open the problematic postcard PDF.
Navigate to the 'Tools' or 'Edit' tab in the top ribbon and select the 'OCR' or 'Recognize Text' feature.
Select the correct language for the text contained in your PDF. Choose the option to output searchable text or extract to a new document.
Click 'Start' or 'OK' to process the document. Once completed, use the standard text selection tool to highlight, copy, and paste the newly recognized names and addresses.
Analyze and Re-embed Fonts using PDF Preflight
If the issue stems from a simple font mismatch rather than entirely missing Unicode tables, analyzing the font properties might allow you to fix the file internally.
Bypass PDF Font Errors with WPS Office OCR
When missing Unicode mappings or font mismatches prevent standard text extraction, WPS Office's built-in OCR technology seamlessly converts visual text into fully editable documents without the hassle of fixing internal PDF code.
- 1. Open the PDF: Launch WPS Office and open your problematic PDF file.
- 2. Select OCR: Navigate to the 'Tools' tab and click on the 'OCR' button.
- 3. Choose Extraction Mode: Select 'Extract Text' or 'Convert to Word' depending on how you want to manage the names and addresses.
- 4. Process the Document: Set the document language, click 'Start', and easily copy your newly recovered text once processing is complete.

Frequently Asked Questions
Why does my PDF say there is a font error when copying text?
This occurs when the fonts used to create the original PDF were not properly embedded or lack a valid Unicode mapping dictionary. The software knows how to draw the shapes of the letters, but doesn't know what actual text characters those shapes represent.
Can command-line tools like pdftotext handle corrupted embedded fonts?
No, standard text extraction tools like pdftotext rely entirely on the internal text encoding of the PDF file. If the Unicode mapping is broken, these tools will output gibberish, symbols, or blank spaces. OCR is required to bypass this issue.
How do I know if my PDF text is properly mapped to Unicode?
You can quickly test this by highlighting a section of text in your PDF viewer, copying it, and pasting it into a plain text editor like Notepad. If the pasted text reads correctly, the mapping is fine. If it appears as random symbols or squares, the Unicode mapping is broken.
Is OCR always accurate for extracting addresses from postcard PDFs?
OCR accuracy depends heavily on the image resolution, contrast, and clarity of the original text. Modern OCR tools are extremely accurate for standard digital PDFs, but you should always quickly proofread extracted critical data like names and addresses to catch minor typos.


