

Fix Missing Font Errors When Editing OCR Text in Acrobat

Question details
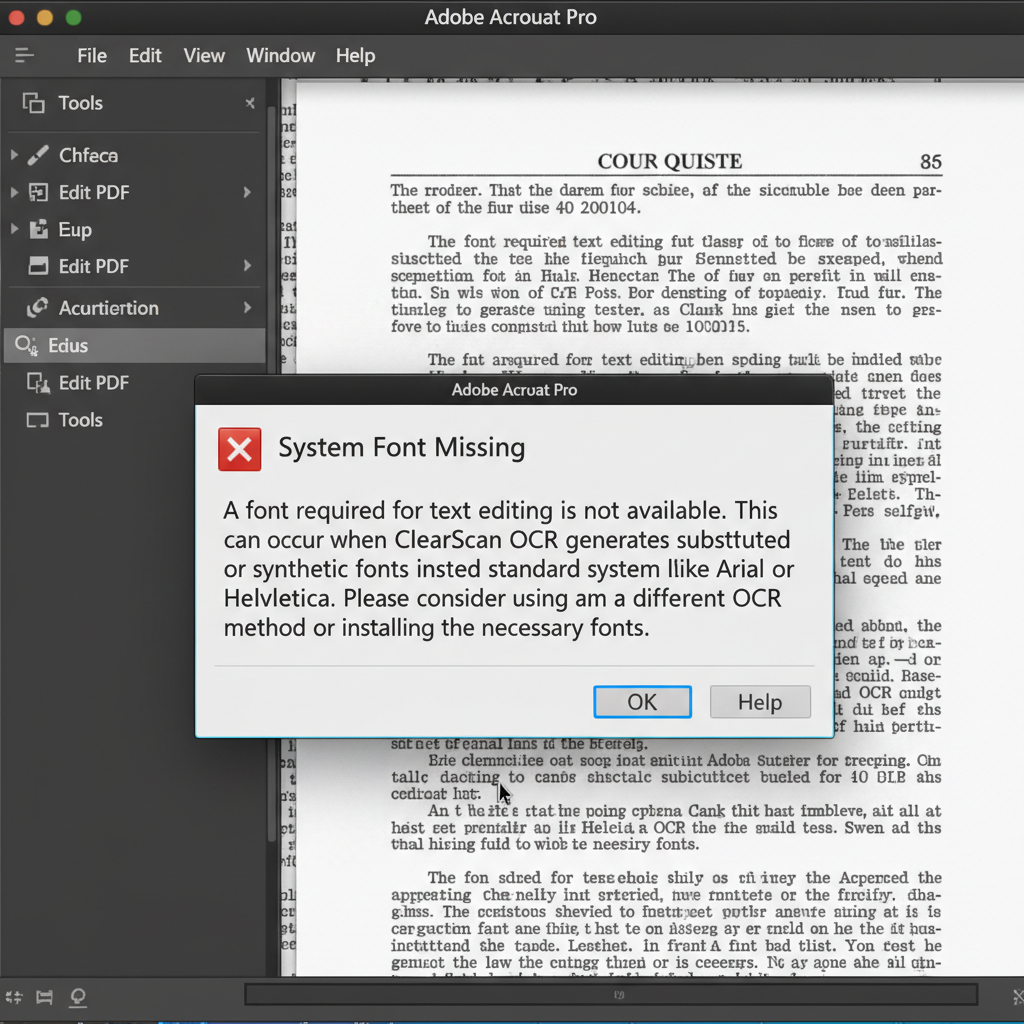
The user needs to resolve an error preventing text editing in an OCR-processed PDF due to missing system fonts.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to edit recognized text in a PDF document after performing Optical Character Recognition (OCR) using the ClearScan method.
- Observed behavior
- Acrobat displays an error stating that no system font is available because the ClearScan OCR process generated text using substituted or synthetic fonts instead of standard installed fonts like Arial.
Before modifying the OCR settings or converting the document, ensure you have saved a backup copy of the original scanned PDF to prevent any accidental loss of original image data.
Switch OCR Settings to Searchable Image
If direct inline editing of the PDF text is not strictly required, repeating the OCR process with a different style will bypass the synthetic font generation.
ClearScan forces Acrobat to create custom, synthetic fonts to mimic the scanned text. Using the Searchable Image setting leaves the original scanned image intact and overlays an invisible layer of text for searching and copying.
Open your PDF in Acrobat, press Ctrl+D to open Document Properties, and click the 'Fonts' tab to verify if synthetic fonts are being used.
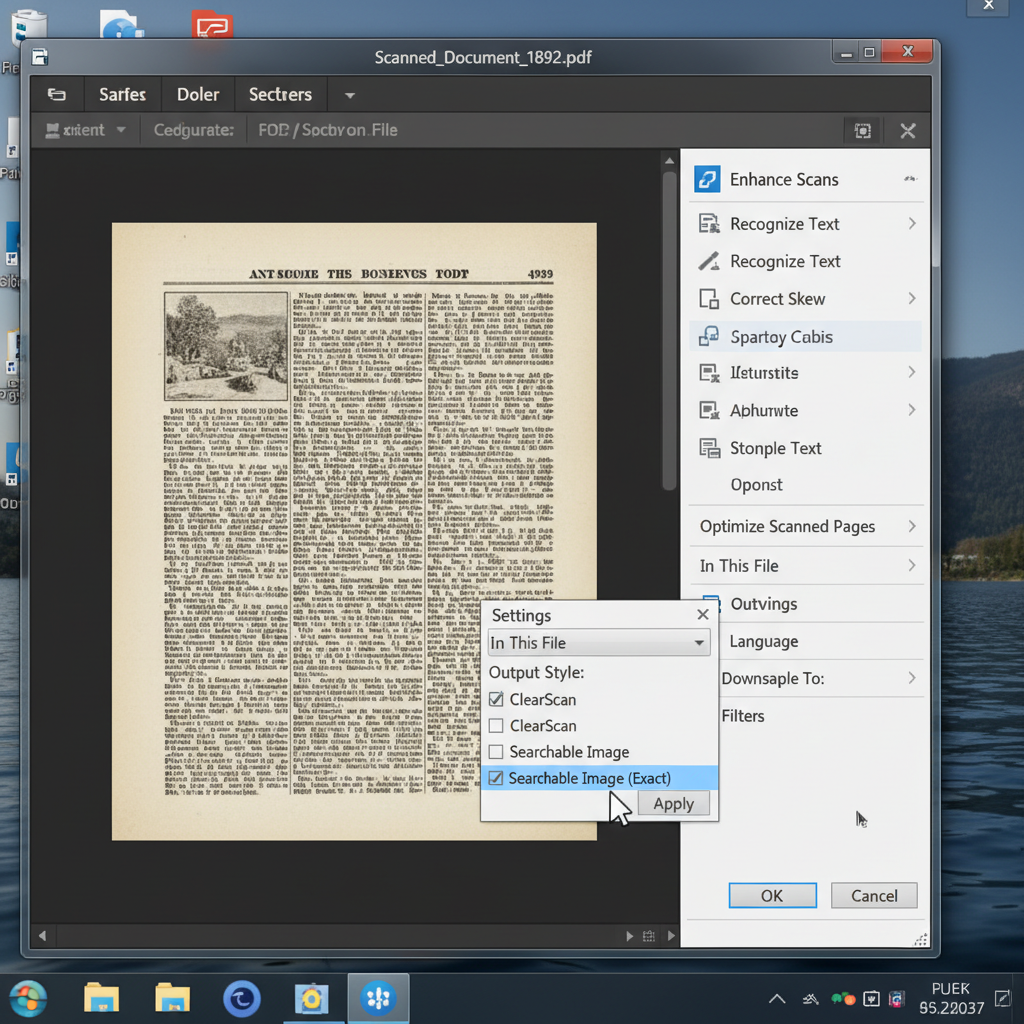
Open the original un-recognized scanned PDF, navigate to the 'Enhance Scans' or 'Recognize Text' tool menu.
Click on 'Settings' in the OCR toolbar and change the Output Style from 'ClearScan' to 'Searchable Image' or 'Searchable Image (Exact)'.
Click 'OK' to run the OCR process. You will now be able to search and copy the text without encountering missing font errors.
Export the Document to Word and Recreate the PDF
Exporting the recognized PDF to a Word document replaces the synthetic fonts with standard system fonts, allowing you to edit freely.
Install a Compatible Font Variant
If you need to edit the text directly but the system lacks the exact substituted font, installing a highly compatible variant like Arial Unicode can sometimes force the edit to work.
Edit Scanned PDFs Flawlessly with WPS Office
Avoid synthetic font errors and rigid OCR limitations. WPS Office provides a powerful, built-in PDF editor equipped with advanced OCR technology. It seamlessly converts scanned documents into fully editable text using standard system fonts, making modifications effortless.
- 1. Open your scanned PDF: Launch WPS Office and open your scanned or image-based PDF document.
- 2. Activate the OCR tool: Navigate to the 'Tools' tab on the top ribbon and select 'OCR' to begin text recognition.
- 3. Select the output format: Choose whether you want to extract the text, create an editable Word document, or make the current PDF searchable.
- 4. Edit directly: Once processed, click on any text block to edit the content using standard, error-free system fonts.

Frequently Asked Questions
Why does Acrobat's ClearScan cause missing font errors?
ClearScan optimizes PDF file size by converting scanned characters into vector outlines and generating custom 'synthetic' fonts. Because these synthetic fonts are not actually installed on your computer's operating system, Acrobat cannot use them for typing new characters, resulting in a missing font error when you try to edit.
How can I check which fonts are currently used in my PDF document?
You can check the embedded and substituted fonts by opening your PDF in Adobe Acrobat, pressing Ctrl+D to access Document Properties, and navigating to the 'Fonts' tab. This will display a full list of fonts used in the document.
What is the difference between ClearScan and Searchable Image OCR?
ClearScan converts the actual image of the text into custom vector fonts to make the text look sharper while reducing file size. Searchable Image, on the other hand, preserves the original scanned picture of the page and places an invisible, searchable text layer over it, which prevents synthetic font substitution issues.
Can I fix the Acrobat font error without re-running the OCR process?
Yes. The easiest workaround without repeating OCR is to export the document to a Microsoft Word format (.docx). This strips the synthetic fonts and forces the text into standard system fonts, allowing you to edit the document normally and save it back as a PDF.


