



How to Fix Gibberish Characters After PDF Conversion

Question details
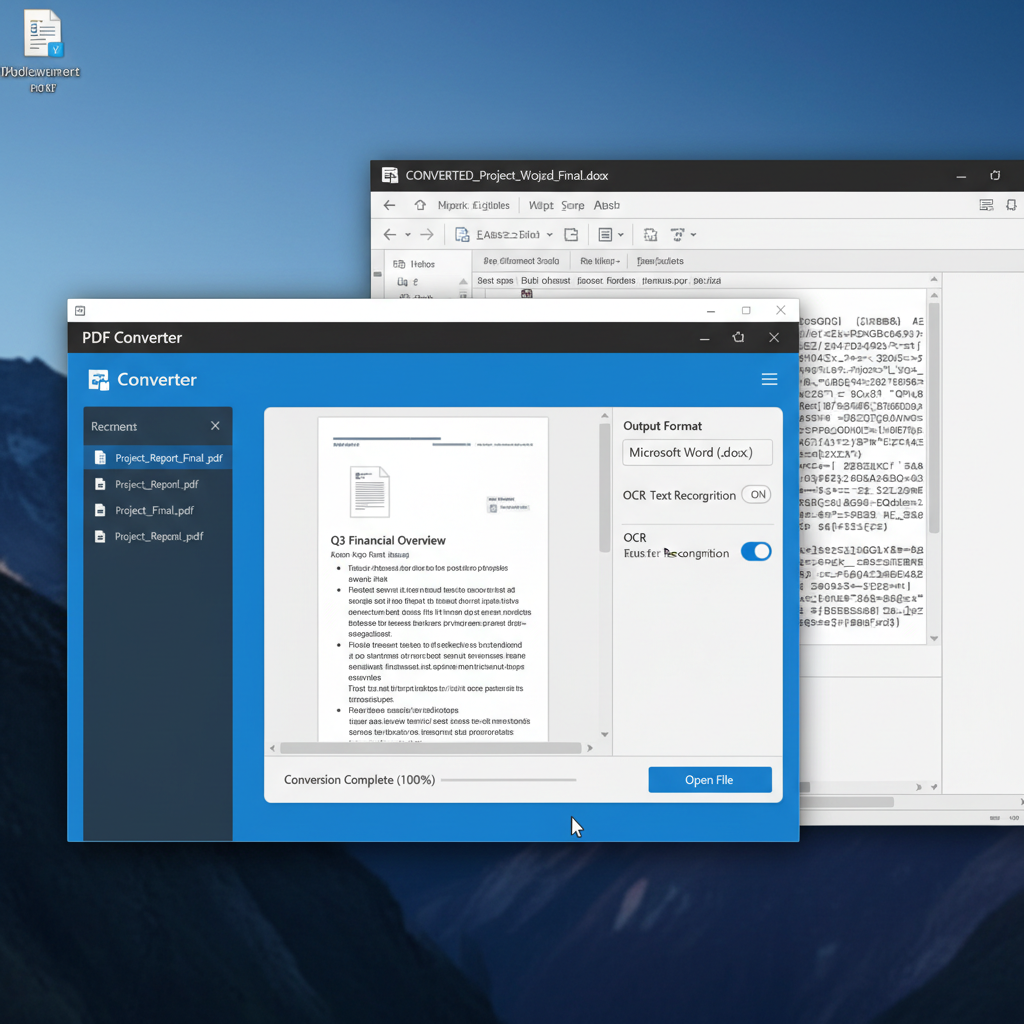
The user needs to resolve an issue where converting a PDF file results in unreadable, nonsense, or gibberish characters.
- Product
- PDF Converter
- Device & OS
- not provided
- Scenario
- Converting a PDF document to an editable format such as Microsoft Word or Excel.
- Observed behavior
- The resulting converted file contains gibberish or nonsense characters instead of the original, readable text.
Determine if your original PDF contains selectable text or is a scanned image. You can test this by trying to highlight individual words in a standard PDF reader.
Enable OCR for Scanned PDF Documents
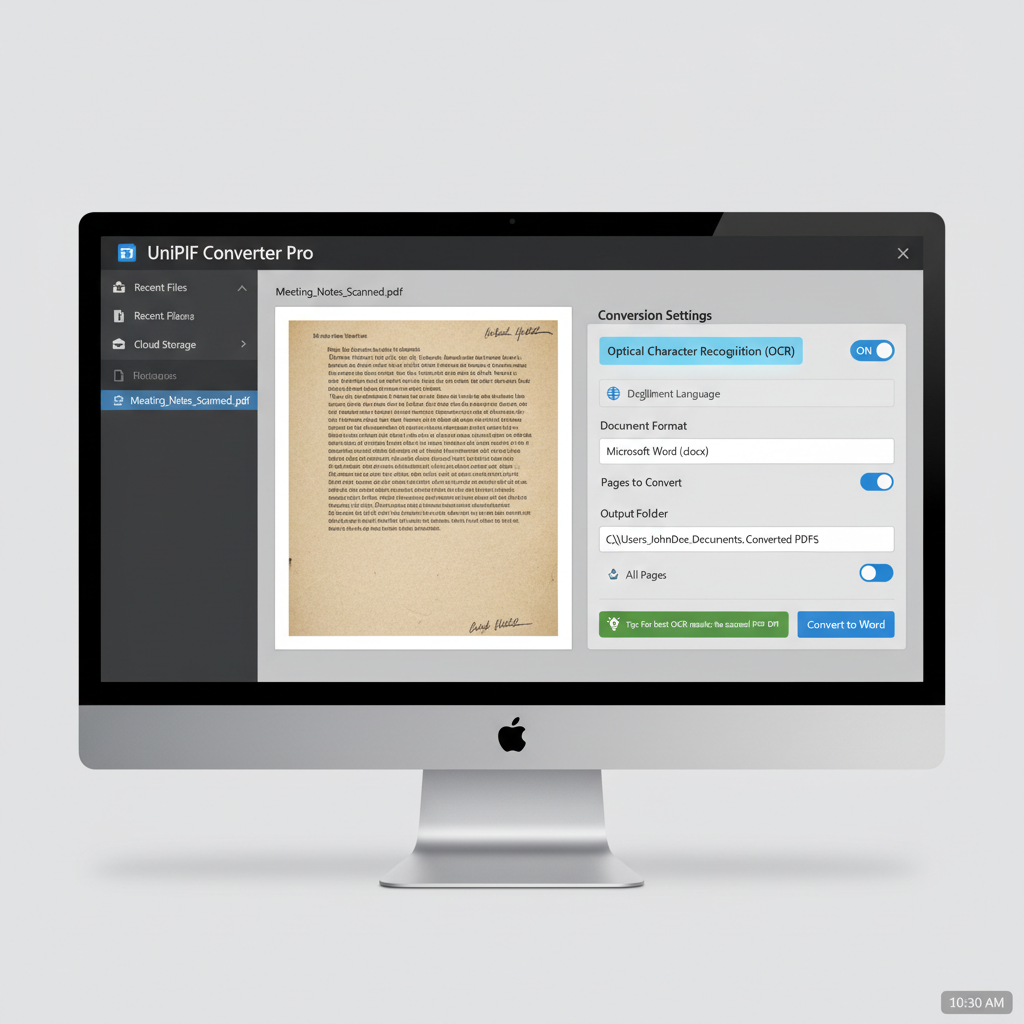
If the PDF is a scanned image rather than a text-based document, standard conversion will fail. You must use Optical Character Recognition (OCR) to extract the text properly.
Scanned PDFs are essentially photographs of text. Without OCR, conversion software attempts to map non-existent text layers, which often results in gibberish symbols or blank pages.
Launch your PDF conversion software (such as Adobe Export PDF or WPS Office) and open the scanned PDF file.
Look for the 'OCR' or 'Recognize Text' option in the conversion settings before initializing the process.
Ensure you select the correct source language of the document, as the OCR engine relies on this to accurately recognize characters.
Proceed with converting the file to Word or Excel. The OCR engine will now translate the images into readable text.
Bypass Font Encoding Issues Using Print to PDF
If the PDF has selectable text but still converts to gibberish, it may have unusual text mapping, embedded fonts, or damaged encoding. 'Flattening' the file can sometimes resolve this.
Convert PDFs Accurately with WPS Office
WPS Office features a powerful built-in PDF toolkit with advanced OCR technology, ensuring high-quality conversions from PDF to Word, Excel, or PowerPoint without gibberish or formatting loss.
- 1. Open WPS Office: Launch WPS Office and click on the 'PDF' tab from the home screen.
- 2. Choose your conversion tool: Click on 'PDF to Word', 'PDF to Excel', or the relevant format from the top toolbar and select your file.
- 3. Enable OCR: If you are converting a scanned file, check the 'OCR' option in the conversion prompt to ensure accurate text extraction.
- 4. Convert and save: Click the 'Convert' button. Your file will quickly be converted into a clean, editable document free of gibberish characters.
Frequently Asked Questions
Why does my converted Word document look like a bunch of symbols?
This usually happens when the original PDF uses custom or embedded fonts that are not mapped correctly to standard text, or if the PDF is a scanned document that was converted without utilizing OCR (Optical Character Recognition) technology.
Do I need special software to convert scanned PDFs?
Yes. Standard PDF converters cannot read text from images. You need a PDF converter equipped with an OCR engine, which scans the image and turns the visual shapes into editable, readable text.
How can I tell if my PDF is a scanned image or text-based?
Open the PDF and try to highlight a single word with your mouse cursor. If you can only select the entire page as one large block, it is a scanned image. If you can highlight individual letters or words, it is text-based.
Will changing the target output format fix the gibberish issue?
Sometimes. If a PDF-to-Word conversion fails due to complex text mapping, trying to convert it to plain text (.txt) might bypass complex font encoding issues, providing you with readable text that you can later copy into Word.


