

Fix Blank Pages in OCR PDFs on iOS by Sanitizing Document

Question details
The user needs to resolve an issue where an OCR-processed scanned PDF displays blank pages on iOS devices despite opening correctly on Windows.
- Product
- Device & OS
- iOS
- Scenario
- Viewing a scanned PDF that was processed with third-party OCR on an iPhone or iPad.
- Observed behavior
- The PDF opens normally on Windows but shows completely blank pages in iOS PDF viewers. Standard hidden information removal fails to fix it, but using the Sanitize Document function allows all pages to render properly.
Before making structural changes, ensure you have saved a backup copy of your original OCR PDF, as sanitizing or flattening a document permanently removes hidden structural data and potentially the searchable text layer.
Use the Sanitize Document Feature
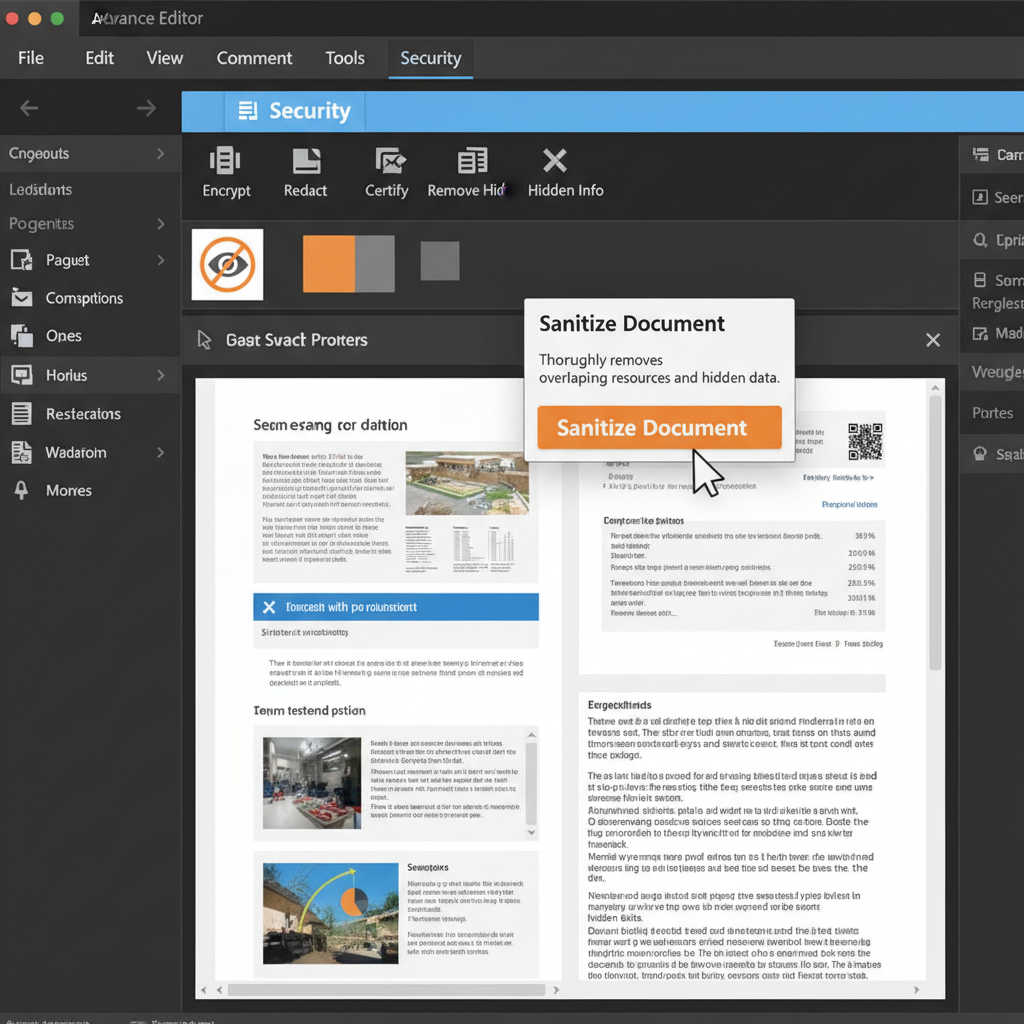
Sanitizing performs a comprehensive removal of complex document structures and overlapping OCR layers that standard hidden-info removal misses, fixing rendering failures on iOS.
The standard 'Remove Hidden Information' tool primarily targets metadata, comments, and basic file attachments. In contrast, 'Sanitize Document' thoroughly strips out overlapping resources, hidden text layers introduced by third-party OCR software, and problematic structural data that the native iOS PDF engine struggles to interpret.
Open your advanced PDF editor, navigate to the Protect or Security tab on the main ribbon, and locate the 'Sanitize Document' option.
Click the option and accept the prompt warning you that hidden information, overlapping elements, and potential text layers will be permanently removed.
Save the newly sanitized PDF file, transfer it to your iOS device via email or cloud storage, and open it to verify that the pages render successfully.
Flatten the PDF via Print to PDF
If a dedicated Sanitize tool is unavailable, flattening the document merges all complex OCR layers into a single static image, ensuring universal mobile compatibility.
Resolve PDF Mobile Display Issues with WPS Office
WPS Office provides powerful PDF editing and optimization tools, allowing you to easily flatten, convert, and repair complex scanned PDFs so they display perfectly on iOS, Android, and Windows devices.
- 1. Open the PDF in WPS Office: Launch WPS Office on your computer and open the scanned PDF that is causing issues on iOS.
- 2. Flatten the PDF: Navigate to the Tools tab and use the 'PDF to Picture' feature, then re-export it as a PDF. This perfectly flattens the file.
- 3. Save and Transfer: Save the optimized document. The simplified file structure is now guaranteed to display correctly on iPhone and iPad PDF viewers.

Frequently Asked Questions
Why do OCR-processed PDFs frequently show blank pages on iOS?
Third-party OCR tools often create complex, invisible text layers and proprietary resource structures over scanned images to make them searchable. The native iOS PDF rendering engine sometimes cannot process these complex, overlapping layers efficiently, resulting in blank or empty pages.
What is the difference between 'Remove Hidden Information' and 'Sanitize Document'?
Removing hidden information typically strips out basic elements like document metadata, bookmarks, annotations, and comments. Sanitizing a PDF is a much more aggressive and comprehensive process that removes all unseen layers, embedded search indexes, hidden text (like OCR layers), and other complex non-visible elements that can corrupt mobile rendering.
Will sanitizing my PDF remove my ability to copy text?
Yes, it is highly likely. Because the searchable text generated by an OCR scan is stored as a hidden layer over the original image, sanitizing the document often deletes this layer. You will be able to read the document normally, but you may no longer be able to highlight, search, or copy the text.


