

Fix Dark or Fuzzy PDF Text After OCR in Adobe Acrobat

Question details
The user needs to identify why PDF text becomes dark, fuzzy, or unreadable after OCR in Acrobat and improve the result.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Running OCR on a clear PDF that may contain vectors, unusual text encoding, or a low-quality image layer.
- Observed behavior
- Text appears dark, fuzzy, or unreadable after OCR.
Check how the PDF was created and whether you can select and copy its text. Keep the original available so you can compare it with a test copy after OCR.
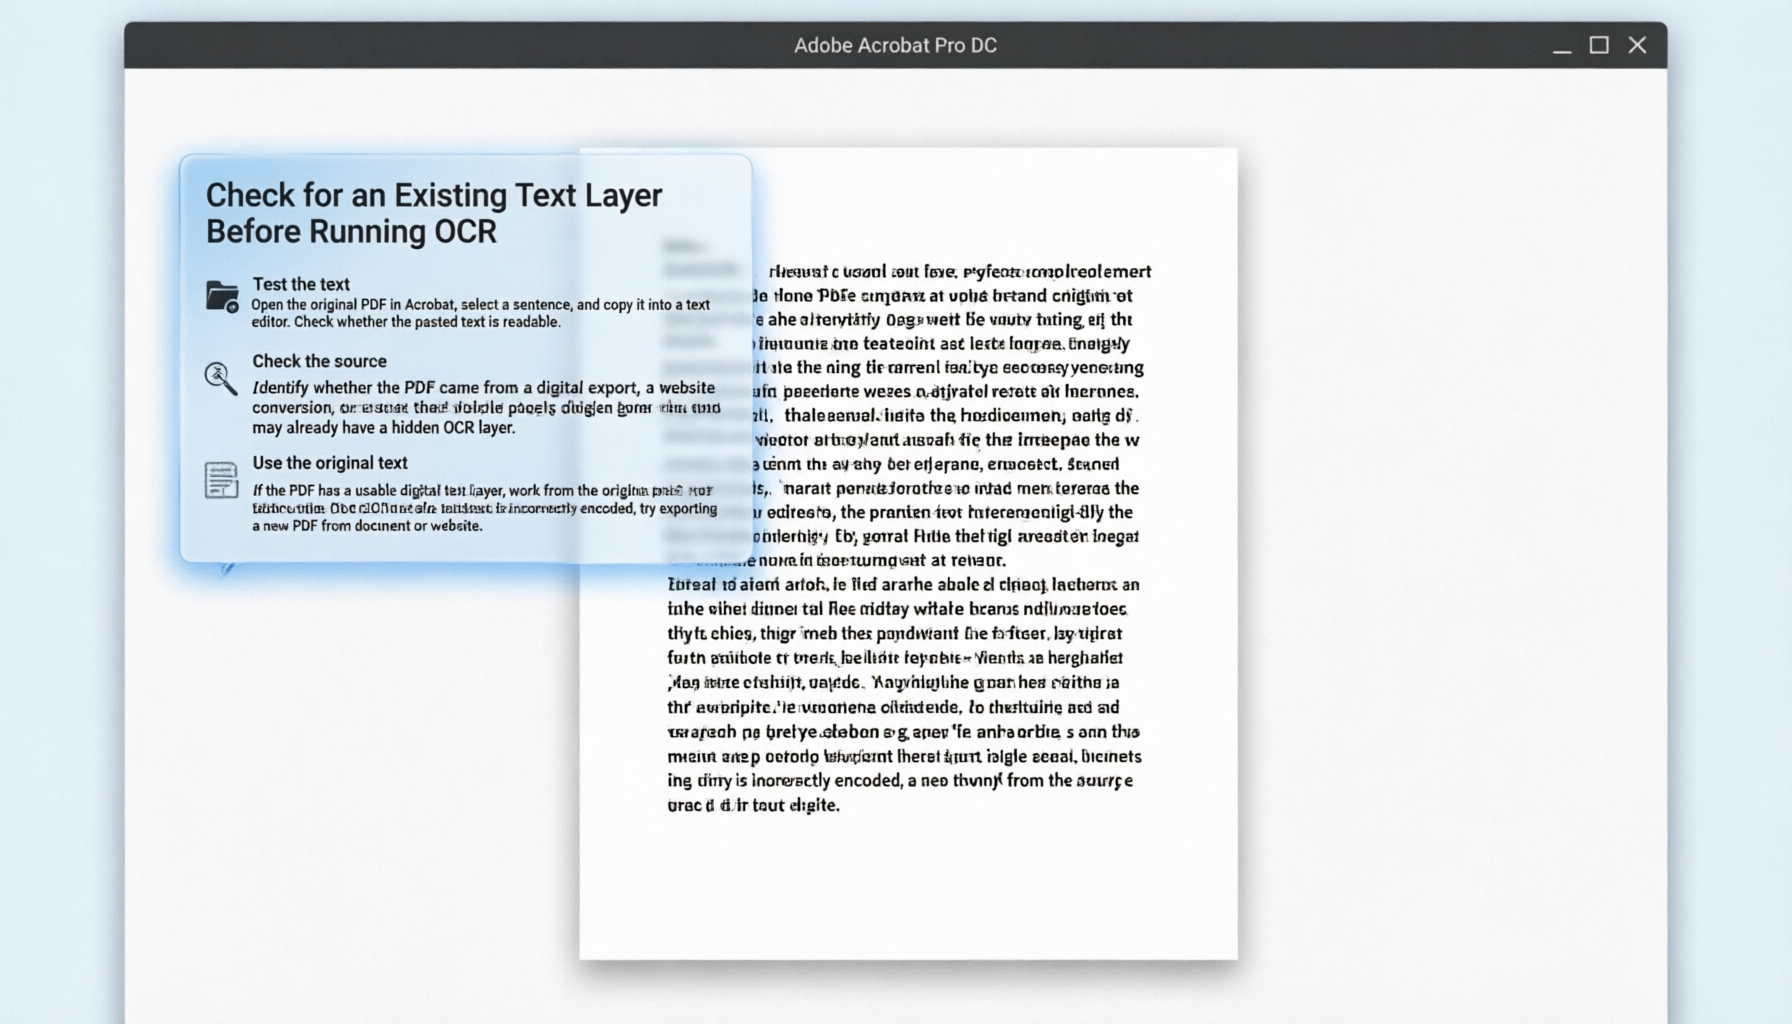
Check for an Existing Text Layer Before Running OCR
Use the existing text when the PDF was digitally generated and OCR is unnecessary.
Open the original PDF in Acrobat, select a sentence, and copy it into a text editor. Check whether the pasted text is readable.
Identify whether the PDF came from a digital export, a website conversion, or a scan. Selectable text alone does not prove that the visible page is digitally generated; a scan may already have a hidden OCR layer.
If the PDF has a usable digital text layer, work from the original PDF without running OCR again. If the text is incorrectly encoded, try exporting a new PDF from the source document or website.
Adjust Scan and OCR Settings for a Scanned PDF
Use this approach when the PDF contains scanned page images that need text recognition.
View PDFs and Work With Office Files in WPS Office
WPS Office is a free, lightweight alternative with a familiar interface for viewing PDFs and working with Office files. Its format compatibility helps you move existing documents into your workflow, though it does not fix Acrobat's OCR processing.

Frequently Asked Questions
Should I run OCR if I can already select text in my PDF?
First copy a sentence into a text editor and check whether it is readable. If the PDF has a usable digital text layer, you may not need OCR. A scanned PDF can also have a hidden OCR layer, so check how the file was created.
Where can I change the OCR language in Acrobat?
Open All tools > Scan & OCR, choose Recognize text, and select the document language in the available settings before running recognition. The exact labels may vary by version.
Why does the PDF look fuzzy after OCR but print clearly?
The issue may be related to display rendering rather than the printed output. Compare the original and OCR copy at the same zoom level, then check the copy in another PDF viewer and print a sample page.
Can the way a website was converted to PDF affect OCR?
Yes. The conversion method can affect whether the PDF contains digital text, vectors, or images. If the existing text is usable, try the original PDF without OCR; otherwise, try creating a new PDF from the source.


