

Fix Incorrect Text Selection After OCR in Adobe Acrobat

Question details
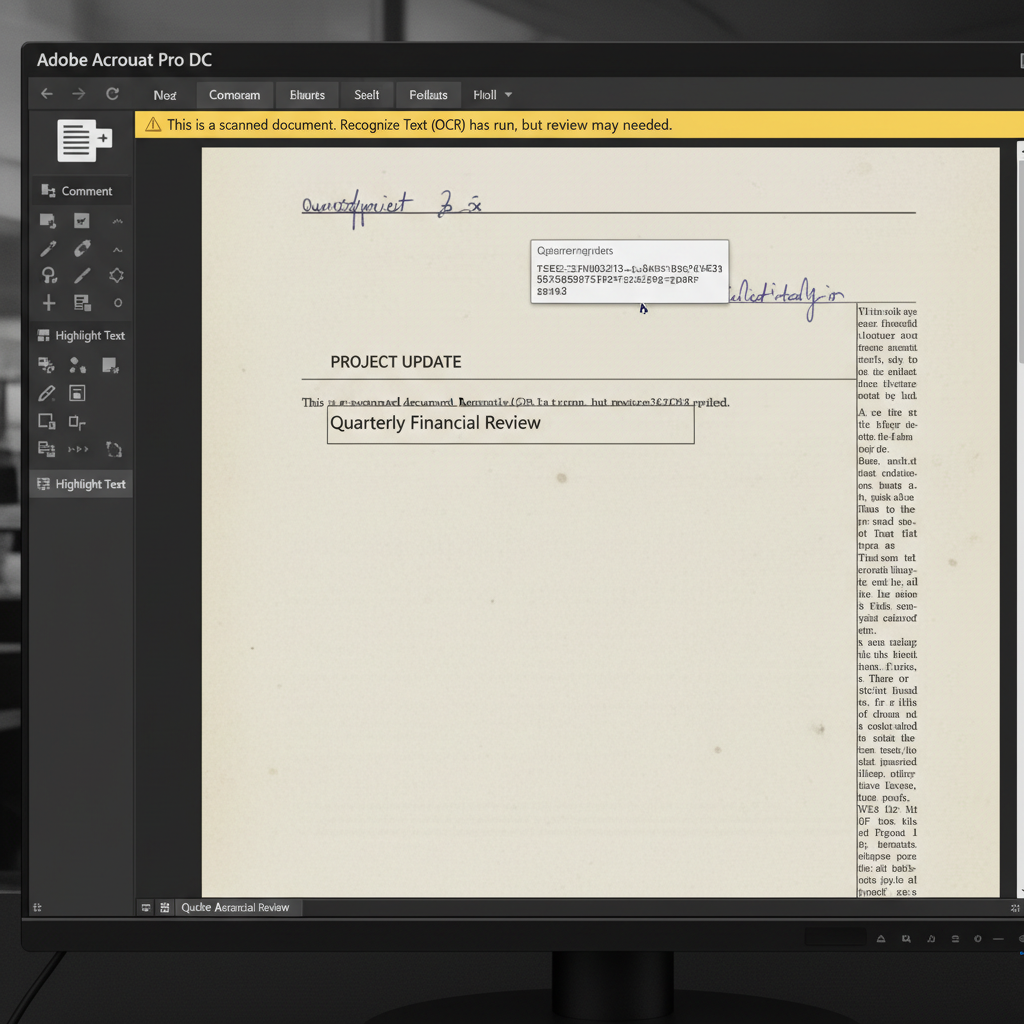
Users need to resolve an issue where selecting text in an OCR-processed scanned PDF highlights incomplete words, random blocks, or incorrect text lines instead of the intended text.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to highlight, copy, or select text in a scanned PDF document after running the Optical Character Recognition (OCR) feature.
- Observed behavior
- Text selection behaves erratically, highlighting blank areas, incomplete words, or text on other lines and pages due to a misaligned or poorly recognized invisible text layer.
Before making changes, test the severity of the OCR misalignment by copying a section of the highlighted text and pasting it into a word processor to see exactly what characters the software actually recognized.
Remove the Invisible Text Layer and Rerun OCR
Fix the misalignment by clearing out the faulty invisible text layer created by the initial OCR process, then process the document again using a cleaner scan.
When Adobe Acrobat performs OCR on a scanned document, it generates an invisible layer of text over the original image. If the scan quality is poor, the document is skewed, or the alignment is off, the text cursor will select the invisible layer incorrectly, causing random blocks or wrong lines to be highlighted.
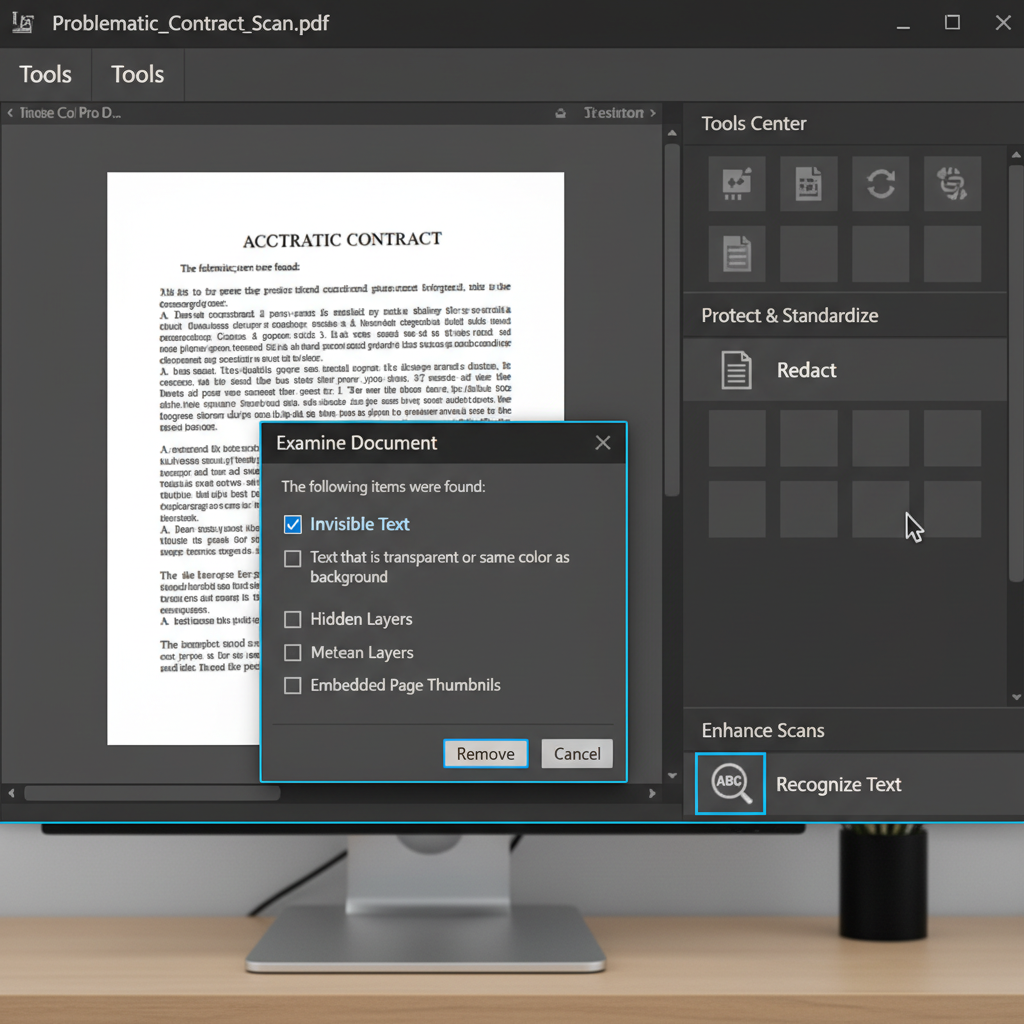
Open your problematic PDF in Adobe Acrobat. Go to the 'Documents' tab on the top menu bar (or the 'Tools' menu in newer versions) and select the 'Examine Document' feature.
Wait for Acrobat to scan the document for hidden information. Once the results appear, check the box next to 'Invisible Text' or 'Hidden Text', then click 'Remove' to strip the faulty OCR layer from the file.
With the invisible text removed, go back to 'Tools' > 'Enhance Scans' > 'Recognize Text' to run the OCR process again. Ensure you are working with a clean, high-resolution scan (at least 300 DPI) for the most accurate alignment.
Perform Accurate OCR on Scanned PDFs with WPS Office
Avoid misaligned text selections and poorly recognized layers by using the highly accurate OCR engine in WPS Office. It effortlessly converts scanned images into perfectly aligned, selectable, and editable text.
- 1. Open Scanned PDF in WPS: Launch WPS Office and open your scanned PDF document using the WPS PDF editor.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button to initialize the text recognition engine.
- 3. Select Output Options: Choose whether to extract the text to a plain Word document or convert the current PDF into a searchable, selectable PDF, then click 'Confirm' to apply.
Frequently Asked Questions
Why does my PDF highlight the wrong words when I select text?
This happens because the PDF contains a scanned image with an invisible text layer generated by Optical Character Recognition (OCR). If the OCR process misreads the text or the page is slightly skewed, the invisible text layer won't align accurately with the visible image underneath.
How can I check if my PDF has a hidden text layer?
You can check by copying a section of the problematic text and pasting it into a text editor like Notepad. Alternatively, use the 'Examine Document' or 'Remove Hidden Information' tool in your PDF editor to detect and list invisible text layers.
Can I just edit the invisible text without removing it completely?
While some advanced PDF editors allow you to edit the hidden text layer directly, it is usually much faster and more effective to completely remove the inaccurate invisible text and perform a fresh OCR pass using a higher quality source image.


