

Fix OCR Not Working When Exporting PDF to Word

Question details
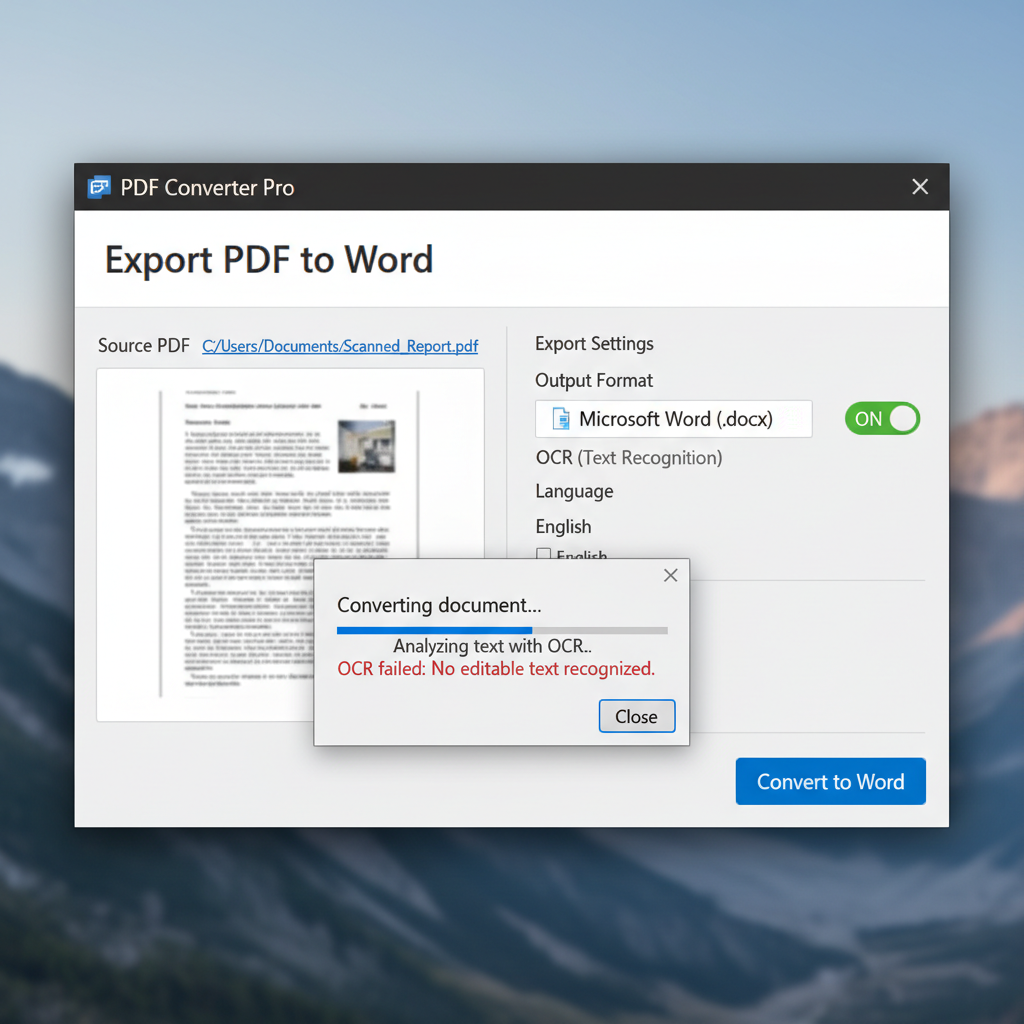
The user is experiencing an issue where exporting an image-based PDF to Word results in a document containing only images instead of editable text due to OCR failure.
- Product
- PDF Converter
- Device & OS
- not provided
- Scenario
- Exporting a scanned or image-based PDF containing English text to a Microsoft Word document.
- Observed behavior
- The resulting Word document contains only images rather than editable text, indicating that OCR did not recognize the content.
Ensure your PDF document is not password-protected against copying or editing, as permission restrictions can prevent OCR software from processing the text.
Verify OCR Settings and Source Image Quality
Ensure the correct language is selected and that the source document has clear, legible text for the OCR engine to process.
OCR (Optical Character Recognition) relies heavily on the quality of the original document. If the text is blurry or the wrong language is selected, the conversion engine will default to placing the original image into the Word document.
Open the PDF and zoom in on the text. Ensure the text is clear, legible, and not heavily pixelated or distorted.
In your PDF export settings, locate the OCR language option and ensure it is set to match the language of the document's text (e.g., English).
Try exporting a different, high-quality scanned PDF to determine if the OCR failure is specific to the original file.
Pre-Process the Document with a Dedicated OCR Application
Use specialized OCR software to recognize and embed text before performing the Word conversion.
Convert Scanned PDFs to Editable Word Documents Flawlessly
WPS Office features a built-in, highly accurate OCR tool that makes extracting text from image-based PDFs simple and efficient.
- 1. Open your PDF: Launch WPS Office and open your scanned or image-based PDF document in the WPS PDF editor.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Configure conversion settings: Select 'Convert to Word' and choose your target language (e.g., English) from the drop-down menu.
- 4. Start the conversion: Click 'Start' to let WPS Office accurately recognize the text and save it as a fully editable Microsoft Word document.

Frequently Asked Questions
Why does my converted Word document only show images instead of text?
This typically happens because the original PDF is image-based (like a scan or photograph). If OCR (Optical Character Recognition) fails or is not enabled during the conversion, the software simply places the images directly into the Word document instead of extracting the text.
How can I improve OCR accuracy for my PDFs?
To improve OCR accuracy, ensure your source PDF has a high resolution (ideally 300 DPI or higher), high contrast between the text and background, and clear, unskewed pages. Additionally, always verify that the correct language is selected in your OCR software settings.
Does WPS Office support OCR for languages other than English?
Yes, the OCR feature in WPS Office supports multiple languages. You can select the specific language of your scanned document in the OCR settings before converting to ensure the highest possible text recognition accuracy.


