

Fix PDF Text Recognized as an Image and Cannot Be Edited

Question details
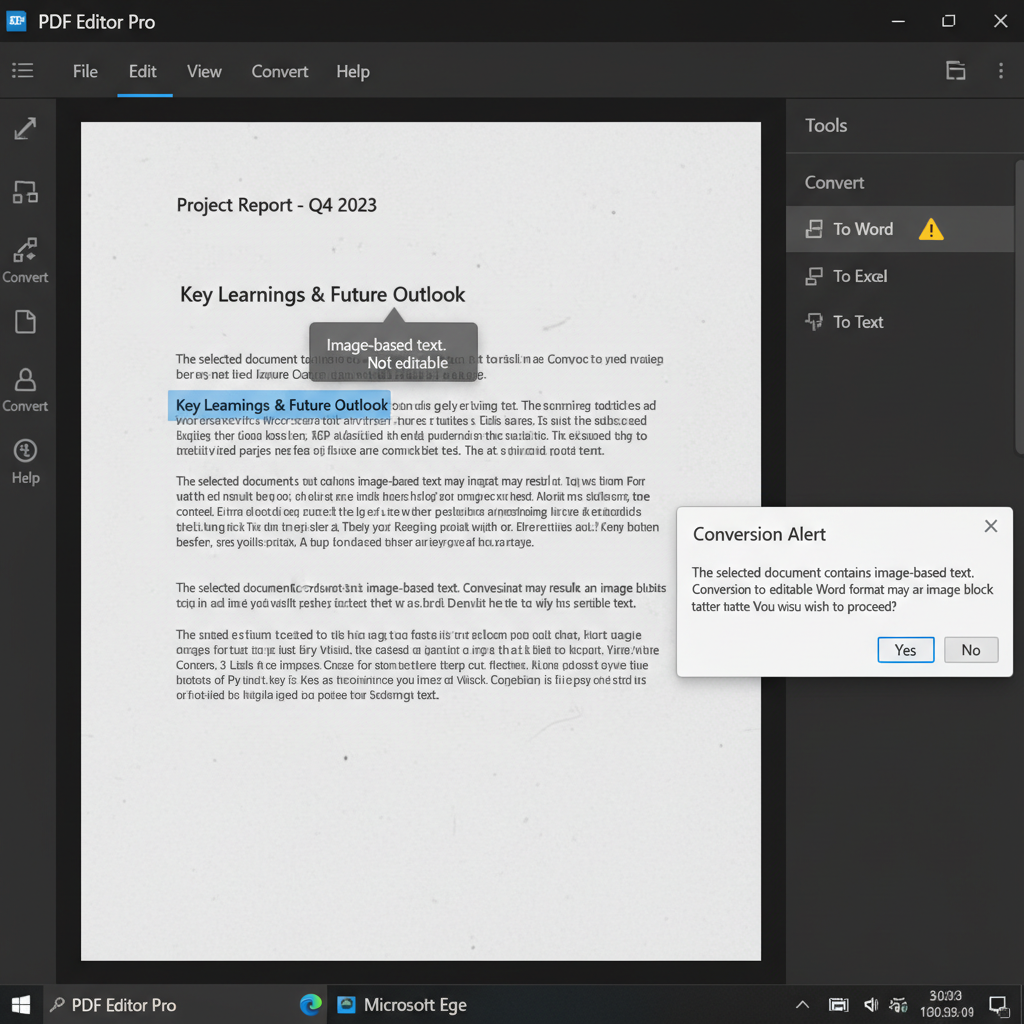
The user is unable to edit text within a PDF document or successfully convert it to an editable Word file because the document's content is formatted as an image.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Attempting to edit the text of a scanned PDF or export the file into a Microsoft Word document for further modification.
- Observed behavior
- The text remains uneditable and exports as an image-based block rather than editable text, even when using a premium subscription.
Make sure your PDF file is not restricted by a permissions password that prevents copying or editing, and ensure you are using a desktop PDF application to access full Optical Character Recognition (OCR) capabilities.
Run OCR Using Adobe Acrobat to Recognize Text
Use the built-in Optical Character Recognition (OCR) tool in Adobe Acrobat to scan the image-based PDF and convert it into searchable and editable text.
When a PDF is created from a scanner or an image file, the text is flattened into a single picture. Regular editing tools cannot modify it. By running OCR, the software identifies letter shapes in the image and generates editable text over them.
Launch Adobe Acrobat on your Windows or Mac computer and open the image-based PDF document.
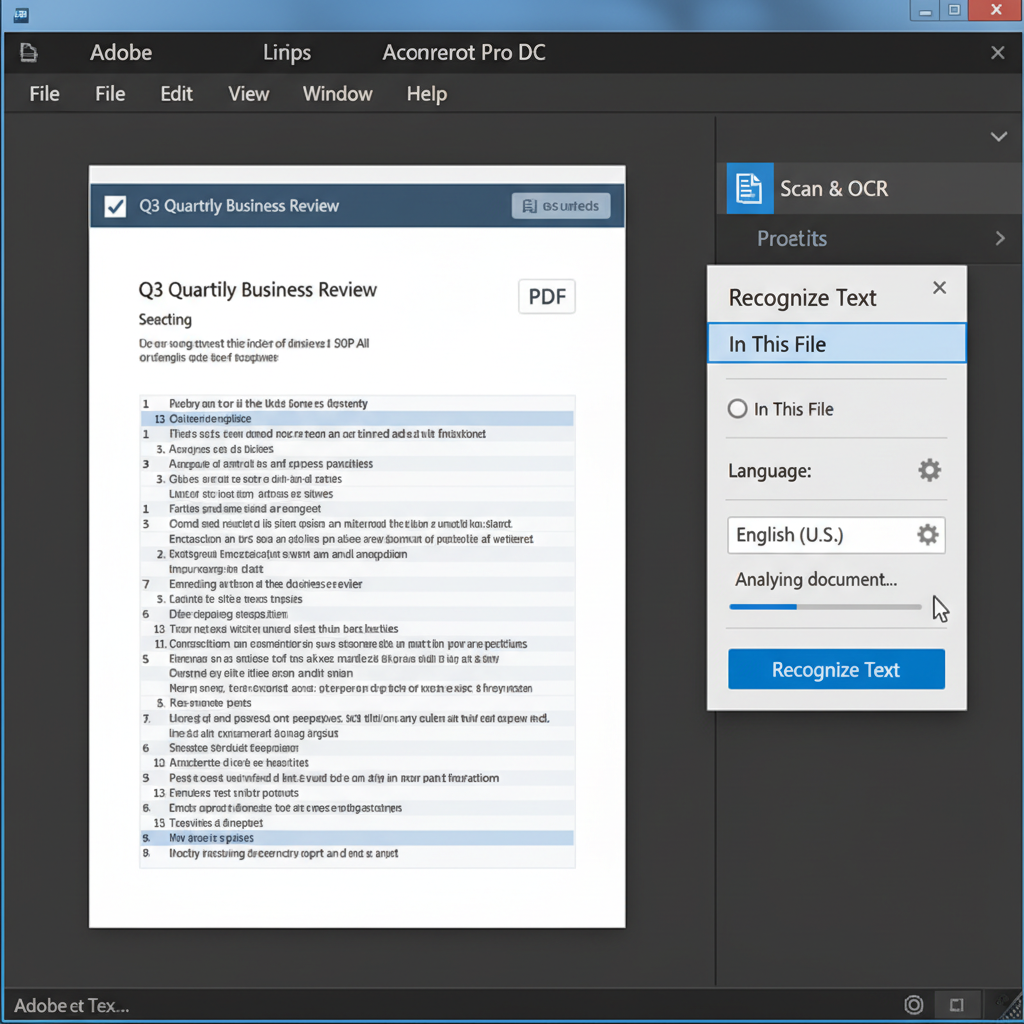
Navigate to the 'Tools' menu and select 'Scan & OCR' (or 'Recognize Text' depending on your version).
Choose 'In This File', select the correct language of the document from the settings, and click 'Recognize Text'.
Once the OCR process is complete, click on 'Edit PDF' to modify the text directly, or go to 'File' > 'Export To' > 'Microsoft Word' to save it as an editable Word document.
Use WPS Office to Extract and Edit Text from Scanned PDFs
WPS Office includes a powerful and highly accurate built-in OCR feature that effortlessly converts image-based PDFs into editable text or fully formatted Word documents.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your scanned or image-based PDF document.
- 2. Launch the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select the Recognition Area: Choose whether to scan the entire document or select a specific area, and specify the document's language for better accuracy.
- 4. Convert and Edit: Click 'Extract text' to copy the text directly, or choose 'Save as Word' to export the recognized content into a new, editable DOCX file.

Frequently Asked Questions
Why does my exported Word document still contain images instead of text?
This happens when the original PDF is an image-based scanned document, and the conversion tool does not apply OCR during the export. You must run an OCR (Optical Character Recognition) process first to identify and extract the text.
How can I tell if my PDF is image-based or contains real text?
Try selecting a single word or sentence with your mouse cursor. If you cannot highlight individual words and the cursor selects the entire page as one large block, the PDF is image-based.
Can I use OCR on my mobile phone to edit scanned PDFs?
While some mobile PDF applications offer basic text extraction, fully recognizing and formatting a scanned PDF for editing is best done on a desktop application (Windows or Mac) due to better processing power and advanced OCR tools.
Do I need a premium subscription to convert a scanned PDF to Word?
In most PDF editors, basic viewing is free, but advanced features like OCR text recognition and converting scanned images into editable Word documents typically require a premium subscription.


