

How to Convert Image-Based Word Pages to Editable Text using Acrobat OCR

Question details
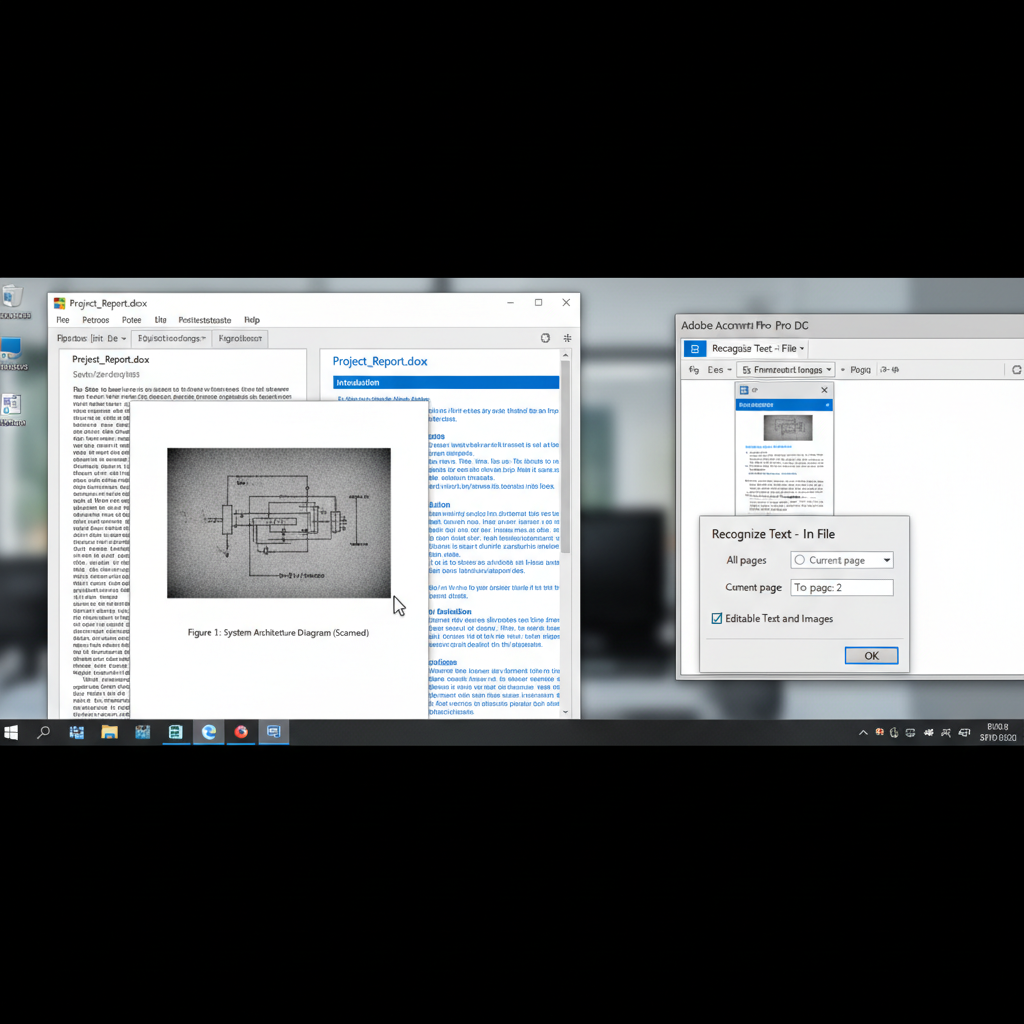
The user needs to convert specific image-based pages within a Word document into editable text using OCR, without converting the entire document and losing the existing live text.
- Product
- Adobe Acrobat / Microsoft Word
- Device & OS
- not provided
- Scenario
- Trying to extract text from scanned images embedded within a multi-page Word document that also contains normal text.
- Observed behavior
- Printing the entire document to PDF flattens the file, resulting in the permanent loss of originally editable live text on other pages.
Identify exactly which pages in your Word document contain images of text versus actual editable text to avoid unnecessary conversion and formatting loss.
Separate, OCR, and Recombine Using Acrobat and Word
Isolate the image pages, convert them to PDF for OCR processing in Acrobat, and then merge the editable text back into your main Word document.
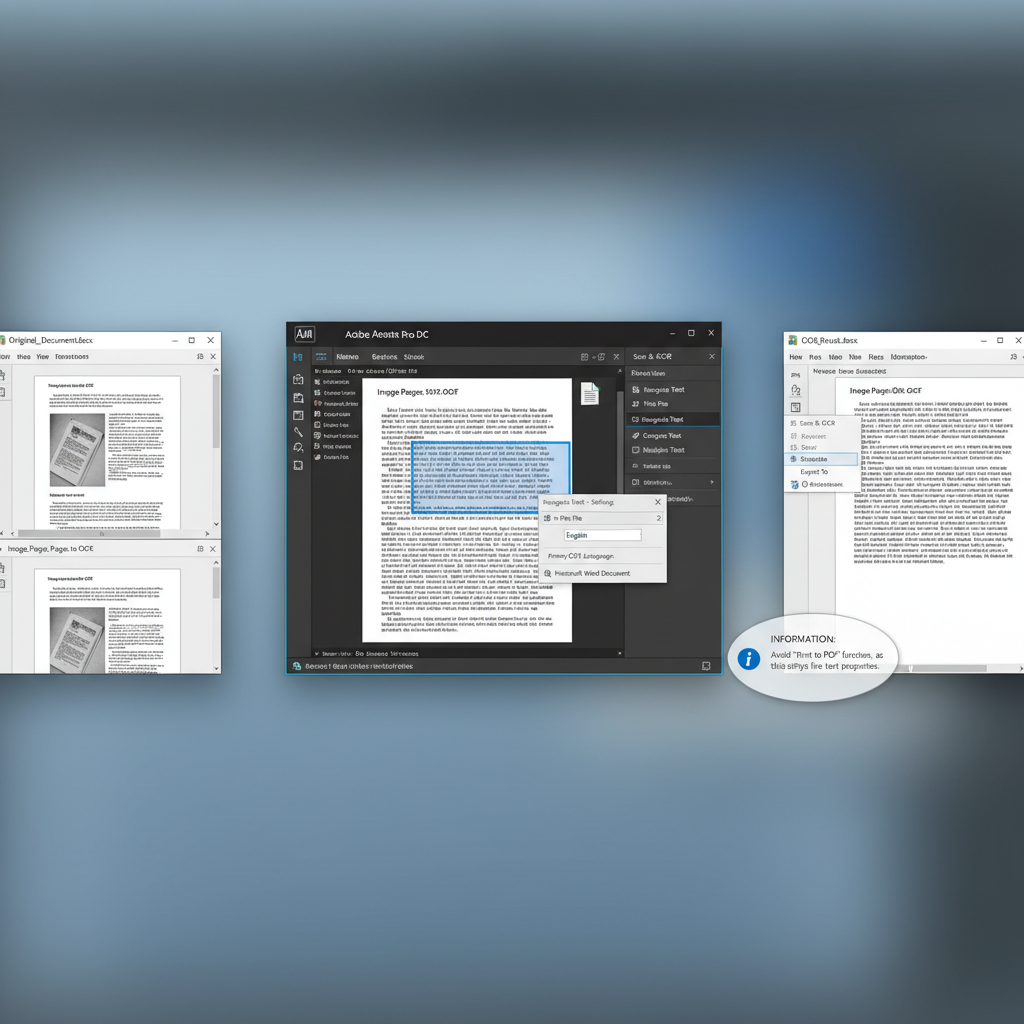
By separating the image-based pages from the main document before running OCR, you prevent Acrobat from accidentally flattening or altering your existing live text.
Cut the image-based pages from the original Word document and paste them into a brand new, separate Word document.
Save the new document as a PDF using Word's built-in 'Save As' feature or by utilizing the Acrobat PDFMaker plugin.
Open the newly created PDF in Adobe Acrobat. Navigate to 'Scan & OCR' > 'Recognize Text', select the appropriate language, and execute the OCR process.
Once the text is recognized, go to 'File' > 'Export To' > 'Microsoft Word Document' to save the PDF back into an editable Word format.
Open the newly converted Word document, copy the editable text, and paste it back into the correct locations within your original document.
Easily Convert Images to Editable Text with WPS Office
Skip the hassle of switching between Word and Acrobat. WPS Office features a powerful built-in OCR tool that can directly extract editable text from images within your documents in just a few clicks.
- 1. Open your document: Launch WPS Office and open the document containing the image-based text.
- 2. Select the image: Click on the specific image from which you want to extract text.
- 3. Activate the OCR tool: Right-click the image and select 'Picture to Text' or locate the OCR feature under the 'Tools' tab in the top ribbon.
- 4. Extract and insert text: Review the extracted text in the prompt window, format it as needed, and insert it directly into your document.

Frequently Asked Questions
Why did I lose my editable text when printing to PDF?
Using the 'Print to PDF' function often flattens the document, converting live text into non-editable vector graphics or images. To preserve text editing capabilities, you should always use 'Save As PDF' or the 'Export' function.
Can I run OCR on an entire Word document directly?
Native Microsoft Word does not have a comprehensive built-in OCR tool to process an entire mixed document at once. You typically need to use a dedicated PDF editor with OCR capabilities, or use an all-in-one suite like WPS Office that supports direct Picture-to-Text extraction.
Does OCR accuracy depend on the image quality?
Yes, OCR relies heavily on the resolution and clarity of the original image. Blurry, low-resolution, or highly stylized text images may result in recognition errors or missing characters.
How do I know if text in my Word document is actually an image?
Try to highlight individual words or letters with your mouse cursor. If clicking selects the entire block with resizing handles around the edges instead of highlighting the text, it is an image.


