

How to Automatically Split a PDF and Name Files by Certificate Number

Question details
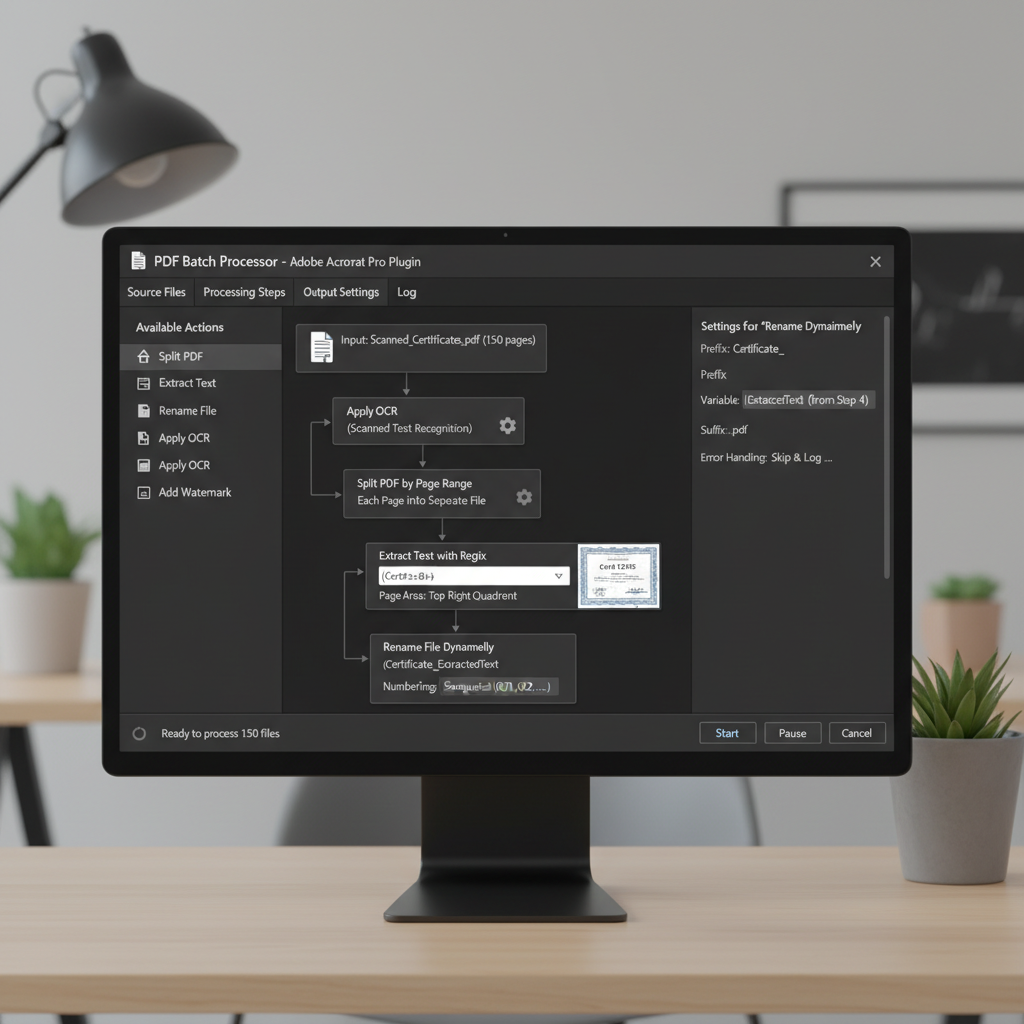
The user needs to split a large PDF of scanned certificates into individual files and automatically name each new file based on the unique certificate number found on its respective page.
- Product
- Adobe Acrobat / PDF Editors
- Device & OS
- not provided
- Scenario
- Automating the extraction and saving process for bulk scanned documents where manual renaming would be too time-consuming.
- Observed behavior
- The user requires an automated workflow to recognize text within a scanned document, extract a specific string (the certificate number), split the pages, and apply that string as the filename.
Ensure your scanned PDF documents are high quality and clearly legible. You must perform Optical Character Recognition (OCR) on the file before any script can read the certificate numbers.
Use OCR and Custom JavaScript in Adobe Acrobat
This method utilizes Acrobat's OCR capabilities combined with a custom JavaScript snippet to locate specific text fields, split the document, and automatically rename the output files.
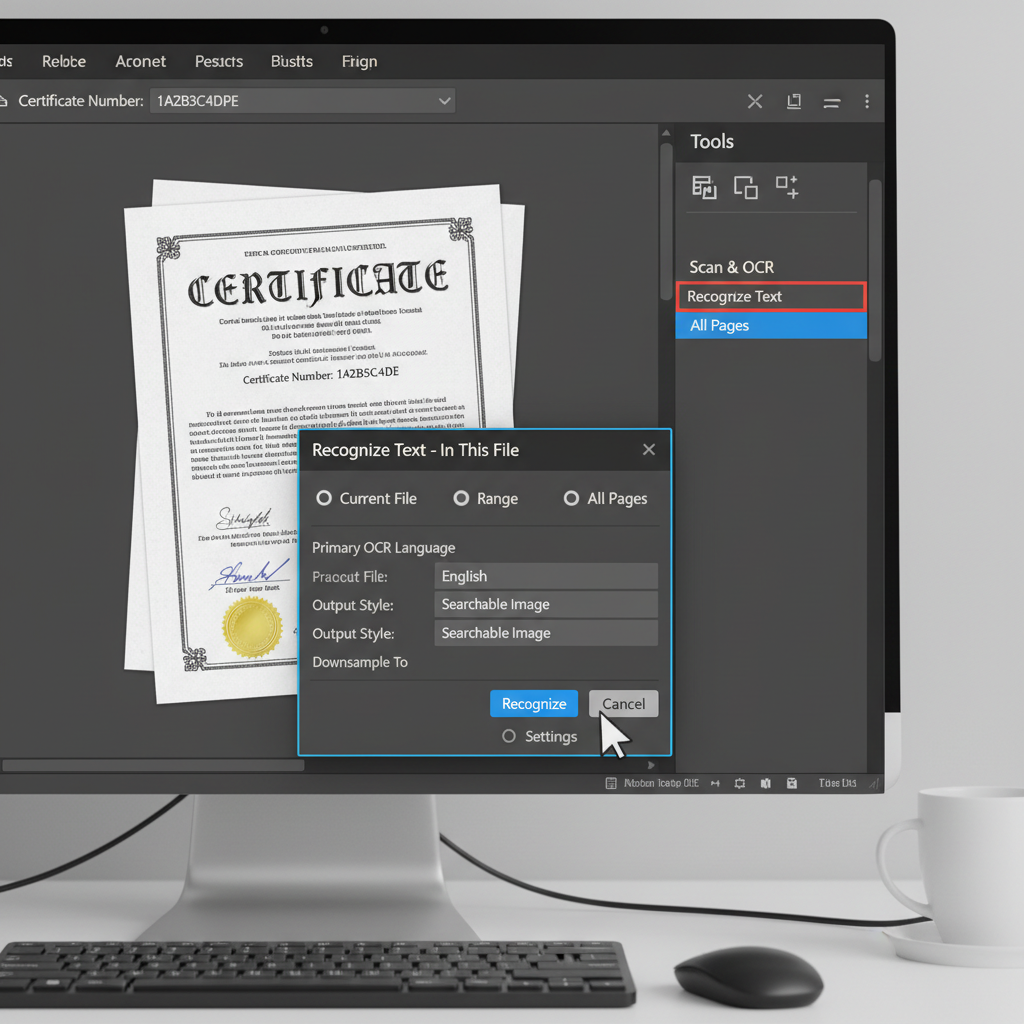
Because scanned documents are essentially flat images, the software cannot natively read the certificate numbers. Once OCR is applied, the text becomes searchable.
A custom JavaScript can then be used to locate a consistent label (like 'Certificate Number:'), extract the adjacent text, and use it as the output filename during the page splitting process.
Open your PDF in Acrobat, go to 'Tools' > 'Scan & OCR', and select 'Recognize Text'. Choose 'In This File' to convert the scanned images into readable text.
Review several pages of the document to ensure the certificate numbers were recognized correctly. Consistent formatting improves the reliability of the script.
Open the Action Wizard or JavaScript console. Run your custom document-processing script designed to iterate through the document, split each page, and apply the extracted text as the filename using the 'extractPages' method.
Before processing a massive batch of certificates, test the script on a small sample of 5 to 10 pages to confirm the output files are named and split accurately.
Use WPS PDF to Extract Text and Split PDF Pages Easily
WPS Office offers a built-in OCR engine and intuitive PDF splitting features. While fully automated variable renaming requires custom coding, WPS PDF makes it incredibly simple to perform highly accurate OCR, extract certificate details, and divide your large document into individual files.
- 1. Open the scanned PDF: Launch WPS Office, navigate to the 'PDF' section, and open your scanned certificate document.
- 2. Perform OCR: Click on the 'Tools' tab and select 'OCR'. Choose your document language and click 'Extract Text' to make the file fully searchable.
- 3. Split the PDF into single pages: Navigate to the 'Page' tab and click 'Split PDF'. Select 'Split by Every 1 page' to separate each certificate into its own distinct file.
- 4. Save and rename: Select an output directory and click 'Split'. You can now easily copy the recognized certificate numbers from the text panel to quickly rename the individual output files.

Frequently Asked Questions
Why is OCR necessary for naming PDFs automatically?
Scanned documents are essentially pictures of text. Optical Character Recognition (OCR) converts these pictures into machine-readable text, which is required for any script to find, copy, and utilize the certificate numbers as filenames.
Can I automatically split PDFs without using a custom script?
Most standard PDF editors can easily split documents by a set page count or file size natively. However, using specific, dynamic text from within the document to name the resulting files is an advanced task that requires a custom script or a specialized batch-processing tool.
What if the certificate number is in a slightly different location on each page?
If the spatial location varies, a well-written script will rely on a consistent text label, such as 'Certificate No:'. The script will search the document's text flow for that specific phrase and extract the characters immediately following it, regardless of exact coordinates.
How can I improve OCR accuracy for automated text extraction?
Ensure your original scanned PDFs are high resolution (ideally 300 DPI or higher), possess strong contrast between text and background, and are free from digital noise, smudges, or skewing. This significantly reduces errors during automated extraction.


