

How to Batch OCR Scanned PDFs and Rename Files Automatically

Question details
The user wants to process hundreds of scanned PDFs in bulk, perform OCR on a specific area of each document, and use the recognized text as the new filename.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Automating a document management workflow where hundreds of scanned files need to be processed, identifying specific data fields (like license plates or invoice numbers) to systematically rename and organize the documents.
- Observed behavior
- Standard PDF applications do not offer a built-in, out-of-the-box workflow for batch OCR that extracts text from a user-defined region to automatically rename files.
Gather all your scanned PDFs into a single staging folder and verify that the target text (e.g., license plates) appears in the exact same geometric location across all documents to ensure accurate regional extraction.
Use an External Python Script with an OCR Library
Since standard PDF editors lack native regional extraction for file renaming, writing a custom Python script using an OCR library is the most reliable way to automate this workflow.
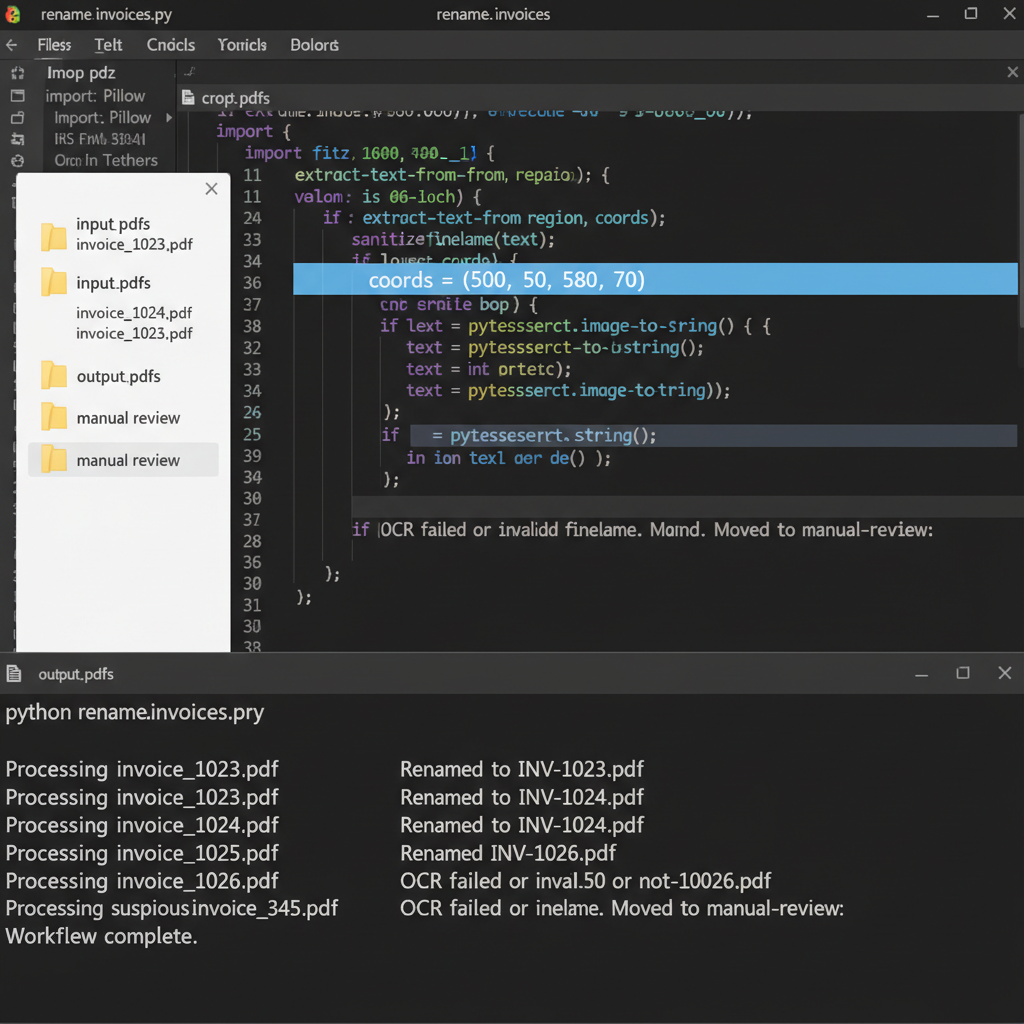
This method requires some basic programming knowledge. By utilizing Python along with libraries like PyMuPDF (for handling PDFs) and Tesseract (for OCR), you can programmatically define a crop box, extract the text, and rename the file in bulk.
Install Python on your computer along with the necessary libraries. You will typically need PyMuPDF, Pillow, and pytesseract. Make sure the Tesseract OCR engine is also installed on your system.
Write a script that opens each PDF and crops the specific coordinate region where your target text is located (for example, the top-right corner for an invoice number).
Pass the cropped image of the region to the OCR engine. Add a function in your script to sanitize the resulting text by stripping out invalid filename characters like slashes, colons, or line breaks.
Use the sanitized text string to construct a new filename. Program the script to save the renamed PDF into a designated output folder and loop through all remaining files.
Use Adobe Acrobat Action Wizard with Custom JavaScript
If you are using Adobe Acrobat Pro, you can attempt to build a custom action that runs OCR and then executes JavaScript to rename the file.
Batch OCR Scanned PDFs with WPS Office
While automatic regional extraction and renaming require custom scripting, WPS Office provides a robust, built-in Batch OCR feature. It quickly converts hundreds of scanned PDFs into editable and searchable documents, making data extraction significantly easier.
- 1. Open WPS PDF: Launch WPS Office on your computer and open the PDF module.
- 2. Access the Batch OCR feature: Navigate to the Tools tab and click on the 'Batch' or 'OCR' option to open the bulk processing menu.
- 3. Import your files: Click 'Add Files' or drag and drop your entire folder of scanned PDFs into the processing window.
- 4. Start recognition: Select your desired output format (such as searchable PDF or text document) and click 'Start' to process all your files at once.
Frequently Asked Questions
Can standard PDF editors automatically rename files based on OCR text?
No, standard PDF editors generally do not natively support extracting text from a specific geometric region to use as an automatic file renaming trigger. This highly specific workflow usually requires a custom automation script or specialized data extraction software.
How do I handle invalid characters in extracted OCR text for filenames?
When using a script to rename files, you must include a sanitization function to strip or replace illegal filename characters. Characters like slashes (/), backslashes (\), colons (:), asterisks (*), and question marks (?) must be removed to prevent OS-level file saving errors.
What happens if the OCR fails to read the text correctly?
If OCR accuracy is low due to poor scan quality, the script may generate incorrect or blank filenames. It is best to include a fallback mechanism in your script that appends a sequential number or flags the file for manual review if the extracted text does not meet a certain length or pattern requirement.


