

How to Batch Convert Thousands of PDF Files to Text or CSV

Question details
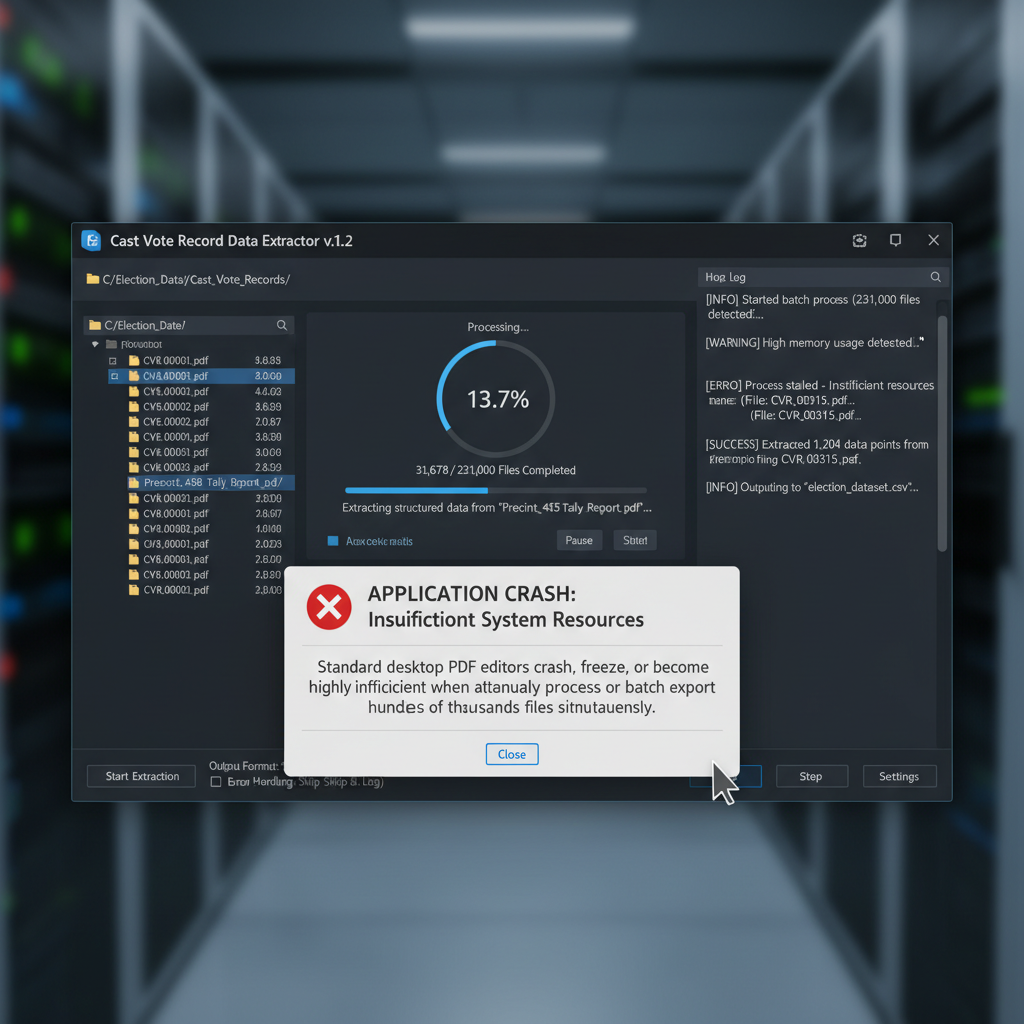
The user needs to process over 231,000 PDF files to extract data into individual or consolidated Text/CSV files, as manual conversion is impossible at this scale.
- Product
- PDF Converters
- Device & OS
- not provided
- Scenario
- Extracting data from hundreds of thousands of cast vote record PDFs into a manageable dataset.
- Observed behavior
- Standard desktop PDF editors crash, freeze, or become highly inefficient when attempting to manually process or batch export hundreds of thousands of files simultaneously.
Ensure you have adequate hard drive storage space and memory before running large-scale batch conversions, and verify if the PDFs contain native selectable text or require OCR processing.
Use Python or Java for Programmatic PDF Extraction
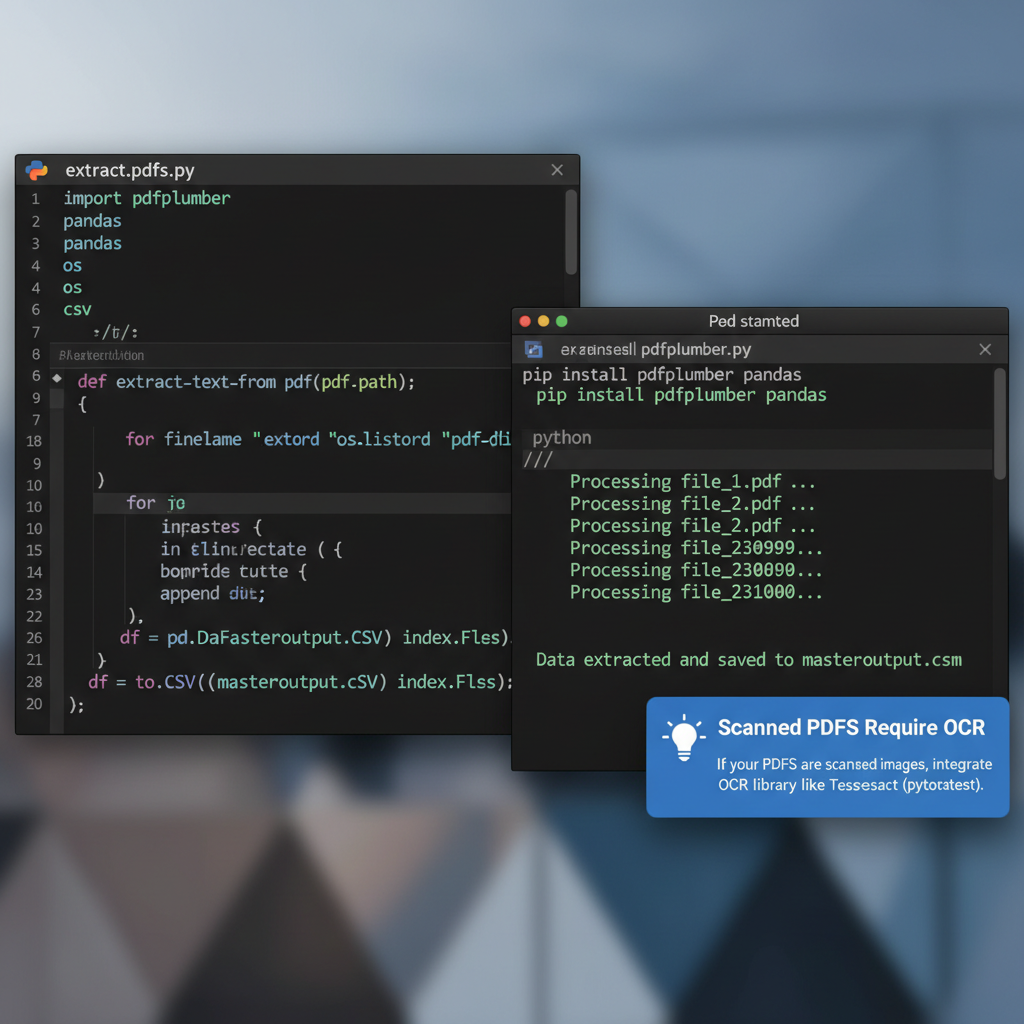
Writing a custom script using libraries like PyPDF2, pdfplumber, or Apache PDFBox is the most scalable way to process hundreds of thousands of files automatically.
A programmatic approach allows you to loop through entire directories of PDFs, parse the relevant text, and instantly structure the output into a single unified CSV file or database without manual intervention.
Install Python and a PDF extraction library by running a command like 'pip install pdfplumber pandas' in your terminal.
Create a script that iterates through the folder containing your 231,000+ PDFs and extracts the text data from each file using the library's read methods.
Format the extracted text into rows and columns, then use a library like Pandas to append the structured data into a master CSV file.
Utilize Enterprise-grade Batch Processing Software
Commercial PDF SDKs or specialized enterprise batch-processing applications can handle massive document volumes without writing custom code.
Set Up an Acrobat Watch Folder
While not ideal for processing 200,000+ files all at once, setting up a watch folder can automate the conversion process as files are gradually dropped into it.
Batch Convert PDFs to Text or Excel with WPS Office
WPS Office includes a robust PDF toolkit that allows you to easily batch convert multiple PDF files into editable Text, Excel (CSV-compatible), or Word formats. It supports high-quality extraction and powerful OCR for scanned documents.
- 1. Open WPS PDF: Launch WPS Office and switch to the PDF tab.
- 2. Select the conversion tool: Click on 'PDF to Excel' or 'PDF to Text' in the top conversion toolbar.
- 3. Add your files: Click 'Add Files' or drag and drop to select the PDFs you want to convert in batch.
- 4. Start the conversion: Choose your desired output folder and click 'Convert' to process the files automatically.
Frequently Asked Questions
Can standard desktop PDF editors handle converting 200,000 PDFs at once?
No, standard desktop PDF editors are generally not designed to process hundreds of thousands of files in a single manual batch. Attempting to load this many files will typically result in the software freezing or crashing due to memory limits.
Do I need OCR to convert PDF data to a CSV file?
You only need Optical Character Recognition (OCR) if your PDFs are scanned images. If the PDFs contain native, selectable text, standard extraction scripts and batch software can parse the data directly without OCR.
Which programming language is best for bulk PDF extraction?
Python is highly recommended due to its extensive ecosystem of data manipulation libraries (like Pandas) and PDF tools (like pdfplumber or PyPDF2). Java, Perl, and specialized command-line tools are also excellent alternatives for orchestrating high-volume extraction.


