

How to Copy Hidden Text, Metadata, and Overlapping Objects Between PDFs

Question details
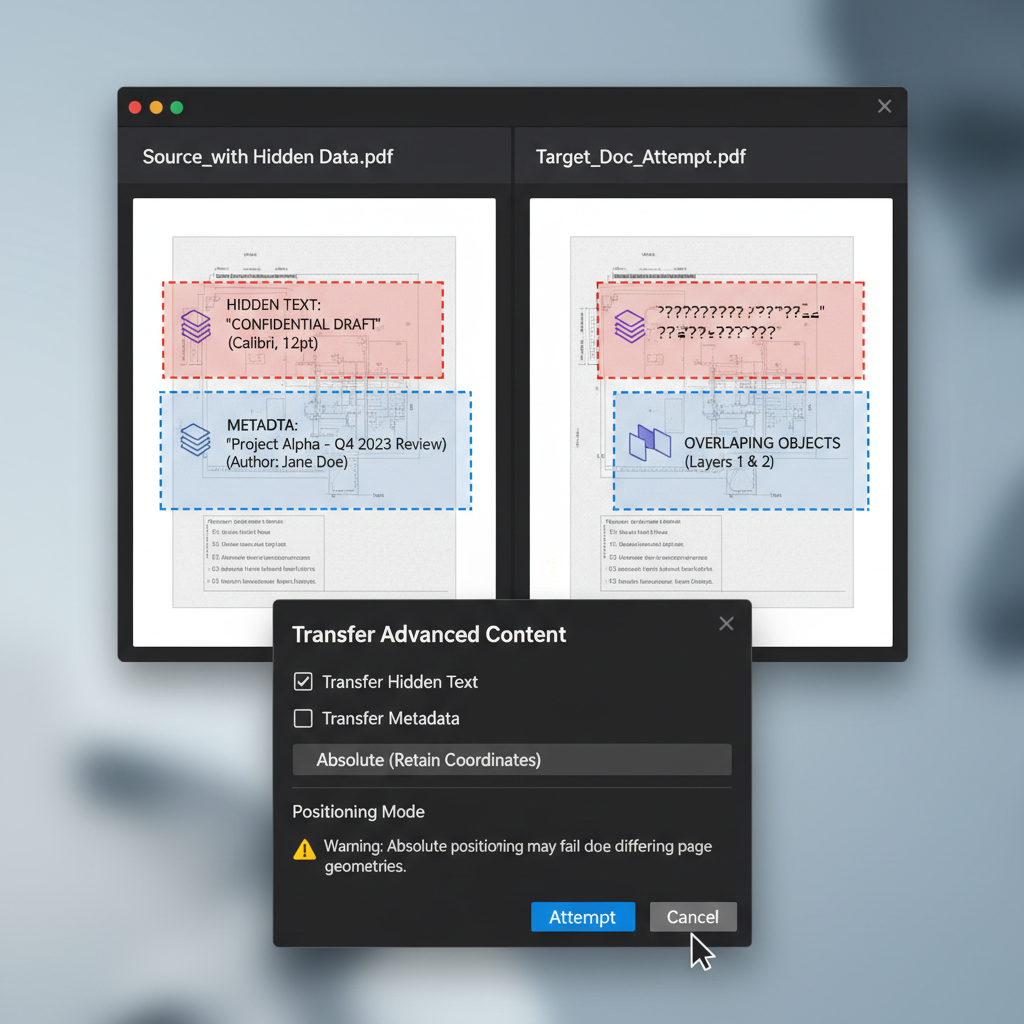
The user wants to copy or reproduce hidden text, metadata, and overlapping objects identified in one PDF into another PDF while retaining their exact original positions.
- Product
- Device & OS
- not provided
- Scenario
- Attempting to transfer invisible document structures, such as layered content and file metadata, from a source PDF to a target PDF with precise coordinate alignment.
- Observed behavior
- Standard PDF copy commands fail to reliably recreate hidden page content, overlapping objects, or metadata in the target file at the exact same positions.
Before proceeding, determine exactly what type of hidden items you are dealing with (e.g., document metadata, OCR text layers, or stacked page objects), as different elements require entirely distinct extraction methods.
Duplicate the File and Remove Visible Objects
Because hidden page content and overlapping objects cannot be reliably copied and pasted with exact positioning, duplicating the entire source file is the safest workaround.
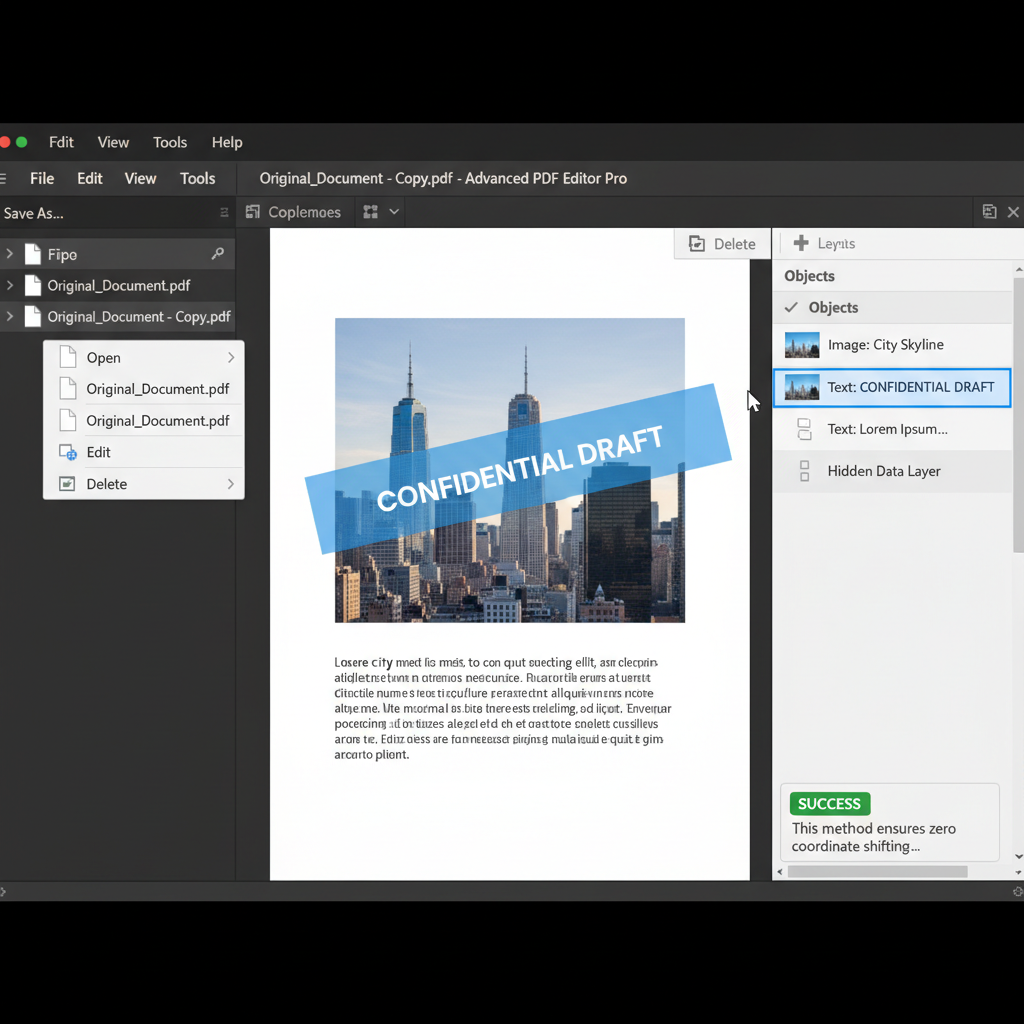
Standard clipboard operations usually strip formatting or alter the coordinates of overlapping objects. By working backwards—duplicating the file and deleting what you don't need—you preserve the absolute positioning of all hidden structures.
Locate your original PDF file, right-click it, and select 'Copy', then paste it in your desired folder to create a duplicate.
Launch your advanced PDF editing software and open the newly duplicated file.
Select the visible text, images, and overlapping foreground objects that you do not wish to keep, and delete them. This leaves the underlying hidden page content and metadata perfectly intact and in their exact original positions.
Go to 'File' > 'Save As' to save the document. You can now use this file as a template containing only your desired hidden information.
Extract and Transfer Metadata Separately
If you only need to transfer the hidden document metadata rather than the physical page content, you can export the metadata as a separate file and import it into your target PDF.
Manage Complex PDF Structures with WPS Office
Handling overlapping objects, document properties, and precise layouts is simple with WPS Office's built-in PDF editor. It provides professional-grade tools to modify your documents efficiently without the steep learning curve of specialized software.
- 1. Download and install WPS Office: Get the latest version of WPS Office from the official website and install it on your device.
- 2. Open your PDF: Launch WPS PDF and open the document containing the objects or metadata you want to manage.
- 3. Edit objects and properties: Navigate to the 'Edit' tab to manipulate text and overlapping image elements, or go to 'Menu' > 'Document Properties' to review metadata.

Frequently Asked Questions
Why can't I just copy and paste hidden text into a new PDF?
Standard copy commands are designed to grab visible foreground elements. Hidden text (such as invisible OCR text layers or background items) requires specialized selection tools or custom plug-ins to be isolated, and normal pasting often loses the precise X and Y coordinates.
How do I find out what hidden information is in my PDF?
Most advanced PDF editors have a 'Sanitize Document', 'Inspect Document', or 'Remove Hidden Information' tool. Running this tool will generate a report listing metadata, hidden text, overlapping objects, and deleted content.
Does removing visible text affect document metadata?
No. Deleting visible page content such as text boxes and images only alters the page layout layer. The document's metadata (author, keywords, creation date) remains intact unless specifically cleared from the document properties.


