

How to Correct OCR Text Without Changing PDF Appearance on Mac

Question details
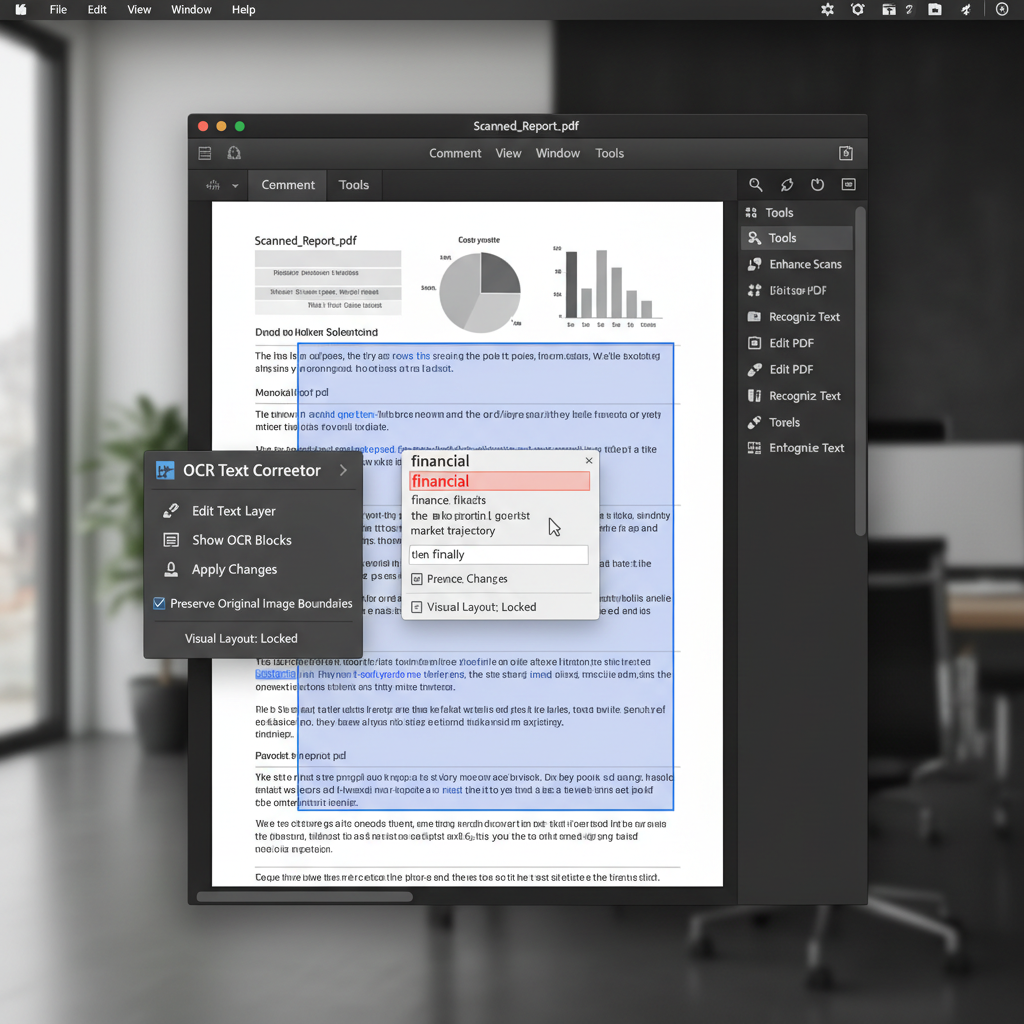
The user needs to manually fix incorrect or missing words recognized by OCR in a scanned PDF while ensuring the original visual layout and appearance remain completely unchanged.
- Product
- Adobe Acrobat
- Device & OS
- Mac
- Scenario
- Fixing text recognition errors in the hidden OCR layer of a scanned PDF document.
- Observed behavior
- Acrobat's OCR sometimes misreads or misses words, but the software lacks a direct editing tool for the invisible text layer that strictly preserves the original image boundaries.
Before attempting to extract or alter the OCR layer, ensure you have the original, high-resolution scanned image file saved as a backup, as applying new OCR layers can sometimes overwrite existing document metadata.
Export to Word, Correct Text, and Re-create the PDF
Since Acrobat cannot directly edit the hidden text layer seamlessly, exporting to Word is the best workaround for heavy text correction.
By converting the scanned PDF to a Word document, you gain full control over the recognized text. After making corrections, you can save the document back to a PDF format.
Note that while this corrects the text, the visual appearance may differ slightly from the original raw scan depending on the export settings.
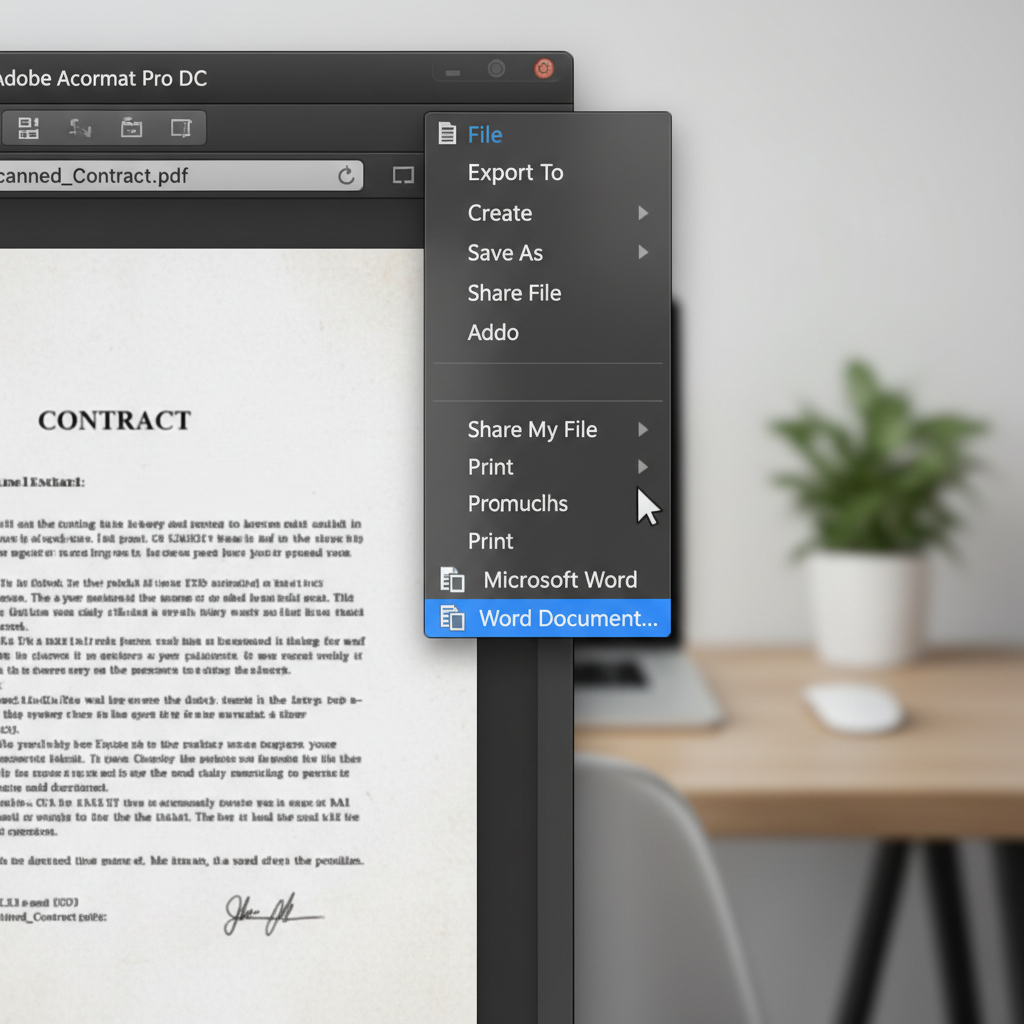
Open your scanned PDF in Acrobat for Mac. Navigate to 'File' > 'Export To' > 'Microsoft Word' > 'Word Document'.
Open the newly created Word document. Locate the misread or missing words and manually correct the text.
Once the text is corrected, go to 'File' > 'Save As' and choose 'PDF' to re-create the document with the accurate, searchable text.
Re-process with a Higher-Quality Scan and OCR Engine
Use this method if retaining the exact original appearance of the scanned document is absolutely mandatory.
Use WPS Office for Highly Accurate PDF OCR and Editing
WPS Office features an advanced OCR engine that accurately recognizes text from scanned PDFs. You can easily extract the text into an editable Word document to fix recognition errors while ensuring compatibility.
- 1. Open the Scanned PDF: Launch WPS Office on your Mac and open the scanned PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab and select 'OCR'. Choose the option to extract the text to a Document.
- 3. Correct the Text: Open the newly extracted document in WPS Writer and manually correct any OCR inaccuracies.
- 4. Export Back to PDF: Click 'Menu' > 'Export to PDF' to save your corrected document with fully searchable text.

Frequently Asked Questions
Why can't I directly edit the hidden OCR text layer in Acrobat on Mac?
Acrobat does not expose the invisible, underlying text layer to standard editing tools. This restriction prevents users from accidentally breaking the alignment between the searchable text and the visual scanned image.
Can I edit OCR text using the built-in Preview app on Mac?
No, Apple's built-in Preview app allows you to select and copy text from an OCR-processed PDF, but it does not have the capability to edit or correct the hidden text layer.
How can I make a PDF searchable without changing how it looks?
When performing OCR, ensure you select an output setting like 'Searchable Image' or 'Searchable Image (Exact)'. This setting keeps the original scanned image visible while placing an invisible, searchable text layer behind it.
Why does my scanned PDF look messy or have different fonts after OCR?
If your OCR tool is set to 'Editable Text and Images' or 'ClearScan', it actively attempts to replace the original scanned image with formatted, editable text. This often results in changed fonts and layout shifts.


