

How to Correct OCR Text Without Changing the Scanned PDF Image

Question details
The user wants to correct misread words in the hidden OCR-recognized text layer of a scanned PDF while keeping the visual scanned image entirely unchanged.
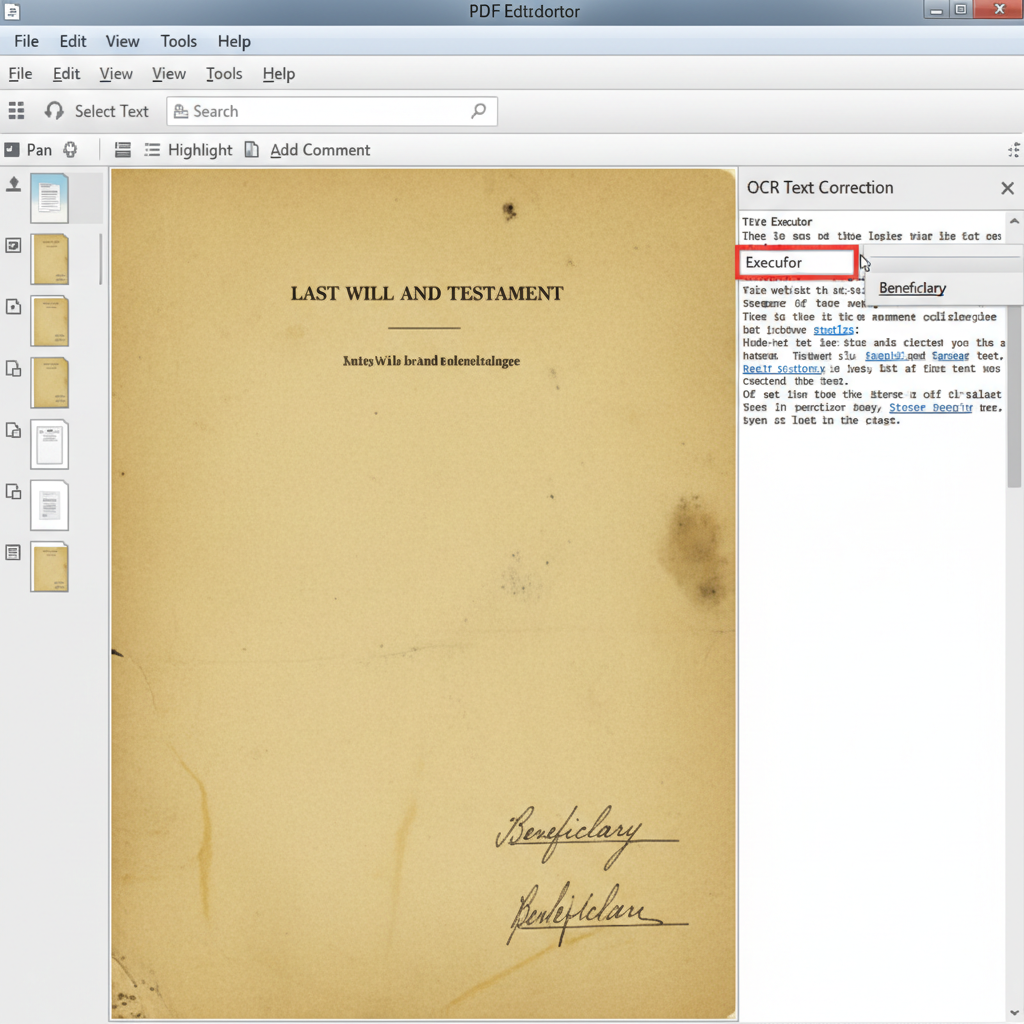
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Reviewing a scanned legal document that uses a searchable-image PDF format with inaccurate OCR recognition.
- Observed behavior
- OCR has misread certain words in the document's hidden text layer, requiring manual correction without modifying the visual integrity of the original scanned page.
Ensure your PDF document is formatted as a 'Searchable Image' (or 'Image over Text'), where the original scan acts as the visual layer and the recognized text resides in a hidden, selectable layer beneath it.
Use the Correct Recognized Text Tool in Your PDF Editor
Correct OCR errors directly in the hidden text layer without disturbing the original visual scan by using advanced PDF editing tools.
A searchable-image PDF keeps the scanned page as the primary visual layer and stores OCR text as a separate hidden layer. Most advanced PDF editors have a dedicated feature to review and correct this hidden layer.
Open the searchable-image PDF in an advanced PDF editor like Adobe Acrobat Pro.
Navigate to the 'Scan & OCR' or 'Recognize Text' toolset from the main tools menu.
Click on the option to 'Correct Recognized Text'. This will prompt the software to highlight suspicious or low-confidence words.
Review the highlighted OCR suspects. Type the correct text into the provided text box for each misread word, then click 'Accept' to update the hidden text layer.
Improve Scan Quality and Rerun OCR
If there are too many errors to correct manually, optimizing scanner settings and re-running OCR can drastically improve text recognition accuracy.
Effortlessly Extract and Edit PDF Text with WPS Office
WPS PDF provides powerful OCR capabilities to accurately recognize text from scanned documents. You can easily create searchable PDFs, extract text for correction, and manage hidden text layers efficiently.
- 1. Open your PDF: Launch WPS Office and open your scanned PDF document using the WPS PDF tool.
- 2. Access the OCR Feature: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Choose the Output Mode: Select the option to create a searchable PDF or extract text directly, depending on your correction and archiving needs.
- 4. Save and Search: Save the document. You can now easily search, select, and copy the accurately recognized text.

Frequently Asked Questions
What is a 'Searchable Image' PDF?
A searchable image PDF contains two layers: a visible layer that is the exact scanned visual image of the document, and a hidden, transparent text layer created by OCR that allows you to select, copy, and search for words.
Why does OCR misread some words on my scanned documents?
OCR accuracy depends heavily on the quality of the original scan. Low resolution, poor contrast, faded ink, creases on the paper, or complex visual layouts can cause the software to misinterpret characters.
Can I directly edit the visible text in a scanned PDF without losing the original look?
Editing the visible text fundamentally changes the scanned image. To keep the original look completely intact, you must use the 'Searchable Image' OCR mode and only correct the hidden recognized text layer rather than modifying the visual layer.


