

How to Extract PDF Pages and Name Files Using Form Field Values

Question details
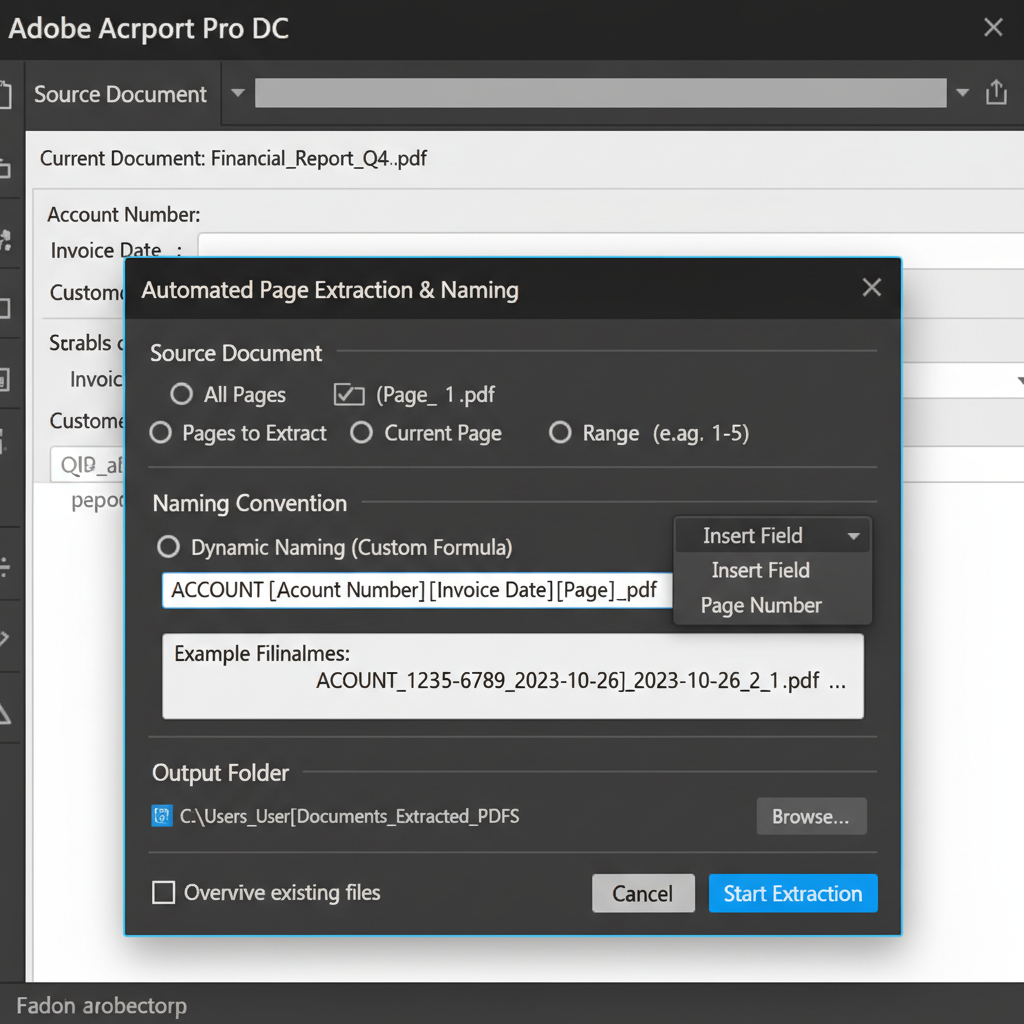
The user wants to extract individual pages from a PDF and automatically name the resulting files based on specific form field values, such as an account number.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Automating the extraction of PDF pages into separate files while dynamically naming each file using data found within the page's form fields or static text.
- Observed behavior
- Adobe Acrobat does not provide a standard built-in feature to name extracted files automatically from form values, meaning the default extraction tool only assigns sequential numbers.
Determine whether the target text you want to use for naming is an actual interactive PDF form field or just static text on the page, as the scripting logic required to read the data will differ significantly.
Utilize a Custom JavaScript Action
Use a custom JavaScript to read the form field value and extract the page, as Acrobat lacks a native graphical interface for this specific naming automation.
Because Adobe Acrobat cannot natively extract and rename files based on page content or form fields out of the box, you must rely on Acrobat JavaScript.
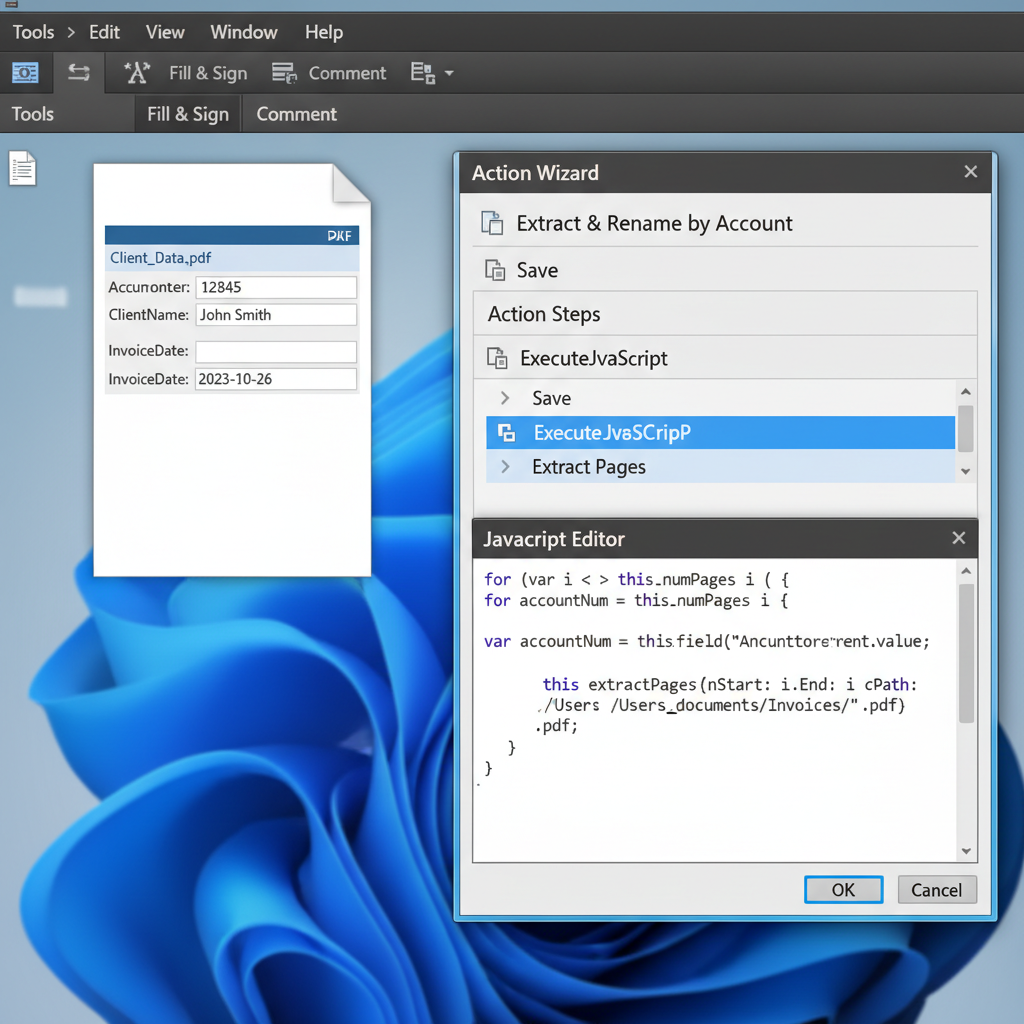
A script can be written to iterate through each page, identify the specific form field (e.g., 'AccountNumber'), read its value, and use the 'extractPages' method to save the file with the retrieved string.
Go to 'Tools' in Adobe Acrobat and select 'Action Wizard' to create a new custom action.
Under 'More Tools', choose 'Execute JavaScript' and add it to your action steps on the right panel.
Click 'Specify Settings' and paste a custom JavaScript code designed to loop through pages, get the 'getField' value, and execute the 'extractPages' command with the custom path.
Save the Action and run it on your target PDF document. Ensure you have properly configured folder-level trust settings if the script requires elevated save permissions.
Easily Extract and Manage PDF Pages with WPS Office
While automated file naming via custom scripts requires advanced coding, WPS Office provides an incredibly intuitive and fast way to manually extract, split, and organize your PDF pages without any complex setup.
- 1. Open the PDF File: Launch WPS Office and open the PDF document from which you want to extract pages.
- 2. Navigate to the Page Tab: Click on the 'Page' tab located on the top navigation ribbon to access page management tools.
- 3. Select Extract Page: Click the 'Extract Page' button. A dialog box will appear allowing you to specify exactly which pages or page ranges you need.
- 4. Choose Extraction Mode: Select whether you want to extract the pages into a single new PDF or separate them into individual PDF files.
- 5. Save the Extracted Pages: Click 'Extract', choose your desired output destination, and manually apply your preferred naming convention to the newly created files.

Frequently Asked Questions
Can I extract PDF pages without using a custom script?
Yes. Most PDF editors, including WPS Office and Adobe Acrobat, have a built-in 'Extract Pages' feature. However, these standard tools will only name the resulting files with sequential numbers (e.g., Document_1.pdf, Document_2.pdf), not dynamically from form fields.
What is the difference between a form field and static text in a PDF?
A form field is an interactive element overlaid on the PDF where users can enter or store data. Static text is the permanent text visually rendered on the page. Custom scripts read these differently; extracting static text usually requires parsing words by their coordinates, which is more complex than reading a named form field.
Why does my Acrobat script fail to save the extracted files?
Acrobat enforces strict security limits on JavaScript. Scripts that attempt to save files to your local hard drive often require 'folder-level' trust or must be executed from a privileged context (like an Action Wizard or a trusted plug-in directory) to bypass security warnings.


