

How to Extract Structured PDF Data to a Text File with Acrobat JavaScript

Question details
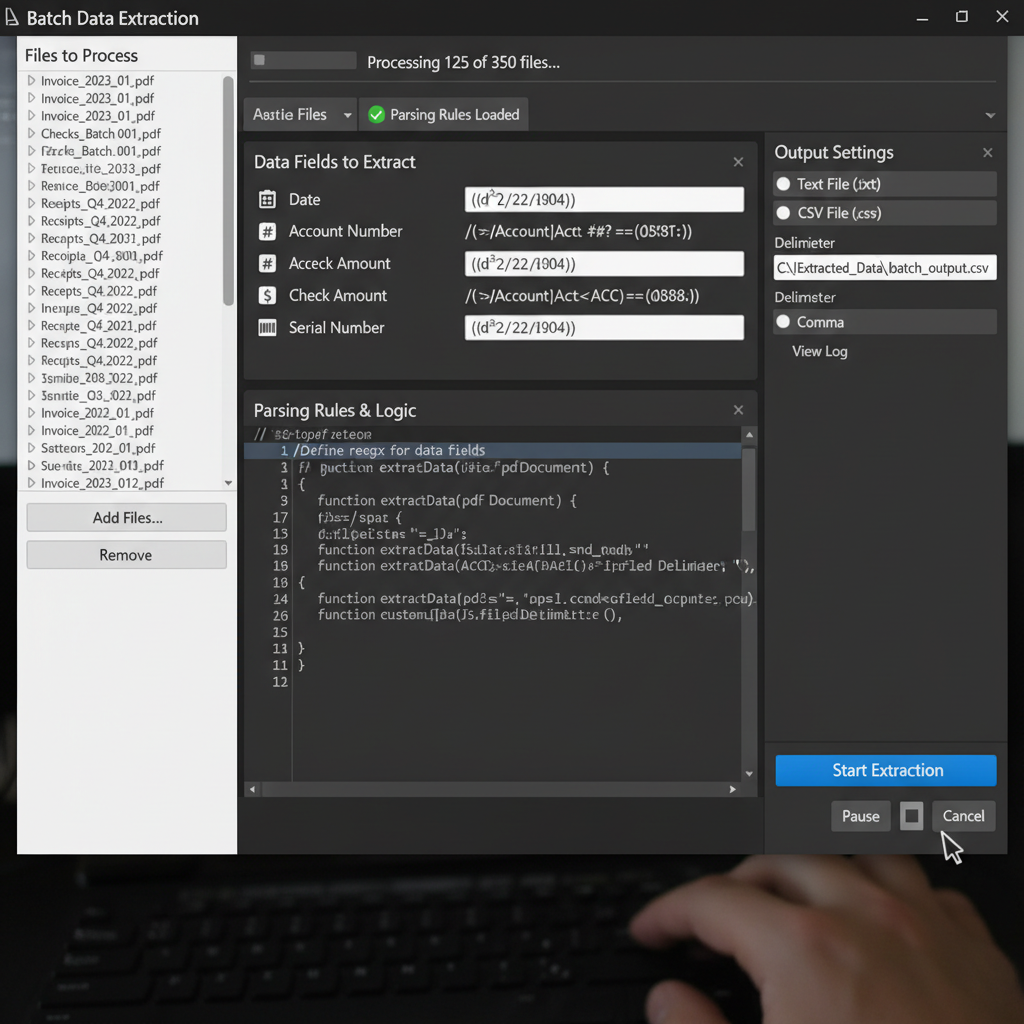
The user needs to extract specific structured data, such as dates, account numbers, check amounts, and serial numbers, from hundreds of PDF files and save the output to a text file or CSV format.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Batch processing multiple PDF documents to accurately identify, parse, and export specific data fields into a structured text or CSV file.
- Observed behavior
- The process requires carefully designed parsing rules and custom JavaScript to identify labels, extract corresponding values, and handle delimiters without conflicting with currency formatting.
Before running any batch extraction scripts, ensure you have a clear understanding of the exact structural layout of your source PDFs. Verify that the data fields you want to extract consistently follow the same patterns across all documents.
Write and Adapt Custom Acrobat JavaScript for Extraction
Create a tailored JavaScript algorithm to identify text labels and corresponding values, ensuring the correct delimiter is used for the final text or CSV output.
Because every PDF document has a unique layout, there is no universal script that can be copied exactly for your data. You must define an algorithm that matches your specific source files.
When generating the output, choosing the right delimiter is crucial to prevent data misalignment.
Open a sample PDF and identify the exact labels that precede the data you want to extract (e.g., 'Account Number:', 'Date:'). Note any variations in spacing or spelling.
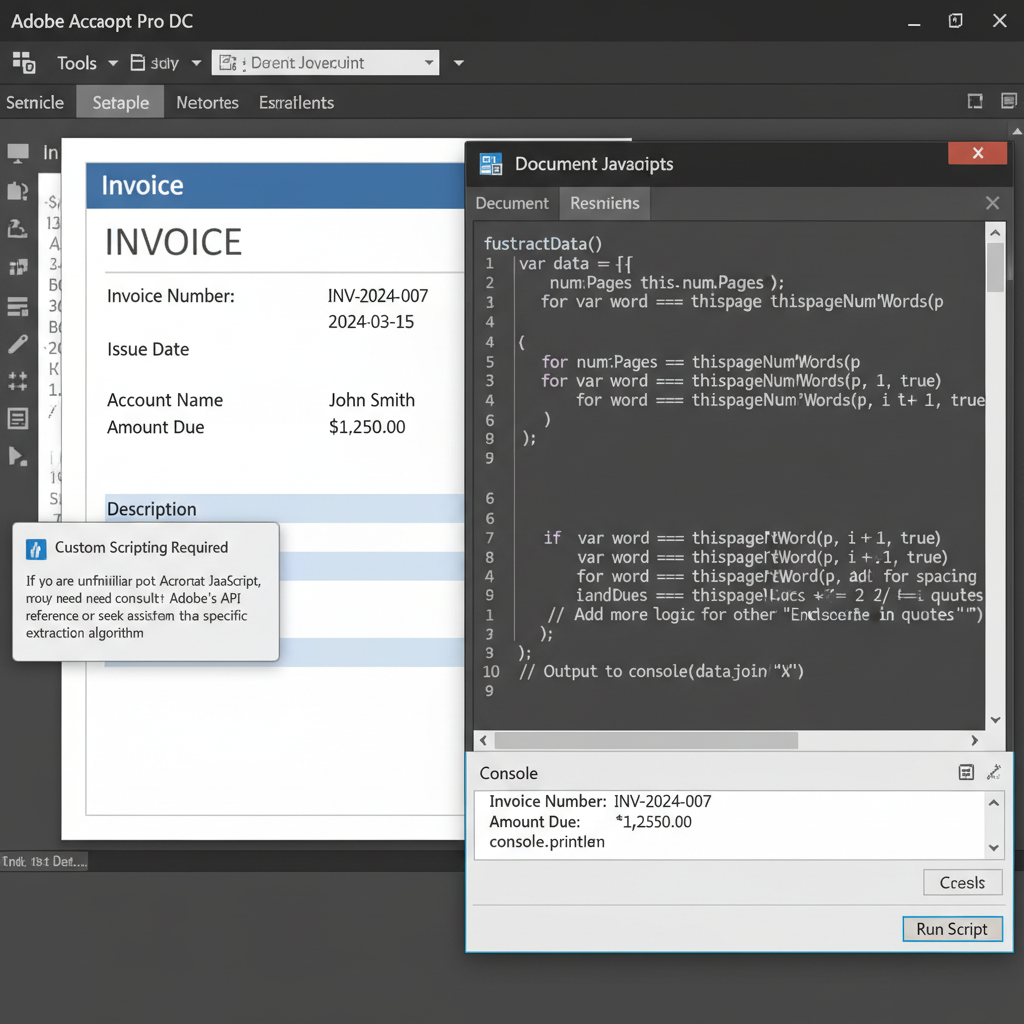
Use Acrobat JavaScript methods such as getPageNumWords and getPageNthWord to iterate through the document's text. Write logic to trigger when a specific label is found and extract the subsequent word or string as the value.
Decide whether to output a standard text file or a CSV. If your extracted data includes currency amounts with commas (e.g., $1,250.00), use a tab character (\t) as your delimiter, or ensure the CSV output wraps currency values in quotation marks to prevent accidental column splitting.
Before running the script on your entire collection of hundreds of PDFs, execute it on a small batch of 3 to 5 files. Check the resulting text file to verify that date parsing and field extractions are accurate.
Extract PDF Data to Excel or Text Easily with WPS Office
If writing custom JavaScript and parsing algorithms is too complex or time-consuming, WPS Office provides built-in tools to seamlessly convert your structured PDF documents directly into Excel spreadsheets or Text files without writing any code.
- 1. Open WPS Office: Launch WPS Office and navigate to the PDF tab in the main workspace.
- 2. Select the Conversion Tool: Click on 'PDF to Excel' or 'PDF to Text' in the top toolbar, depending on how you want to manage your extracted data.
- 3. Add Your PDF Files: Drag and drop the PDF files you want to extract data from into the conversion window, or click 'Add Files' to select them.
- 4. Convert and Extract: Click the 'Convert' button. Once finished, you can easily filter, sort, and manage your structured data in the resulting spreadsheet or text document.

Frequently Asked Questions
Why is my CSV output shifting columns when extracting currency amounts?
Currency amounts often contain commas (e.g., $1,000.00). If your JavaScript outputs a CSV format using commas as delimiters, the system will misinterpret the currency comma as a column break, splitting the value. To fix this, change your script to use a tab delimiter or wrap the extracted currency values in quotation marks.
Can I copy a standard Acrobat JavaScript for PDF extraction?
No, there is rarely a one-size-fits-all script because every PDF has a different layout, structure, and set of labels. You must write or adapt a custom script to match your specific document's text flow and data fields.
How do I test my PDF extraction script safely?
Always run your customized script on a small, isolated folder containing a few sample PDFs first. Review the output text file for parsing errors, incorrect date formats, or misaligned fields before applying the script to your full batch of documents.


