

How to Extract Text from Multiple PDFs to Excel or CSV

Question details
The user needs to extract selectable text from multiple PDF certificates with consistent layouts and export the data into Excel or CSV format.
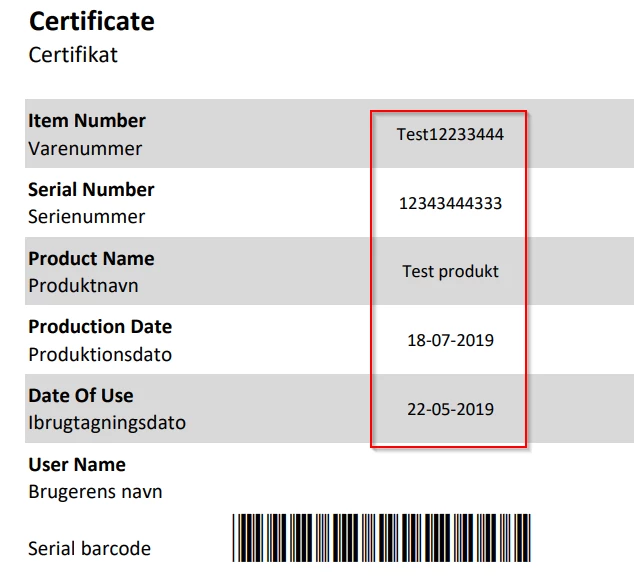
- Product
- Device & OS
- not provided
- Scenario
- Batch extracting text data from non-form PDF documents like certificates into a spreadsheet.
- Observed behavior
- The user is looking for a way to reliably parse and export the text content when the data is not stored in standard interactive PDF form fields.
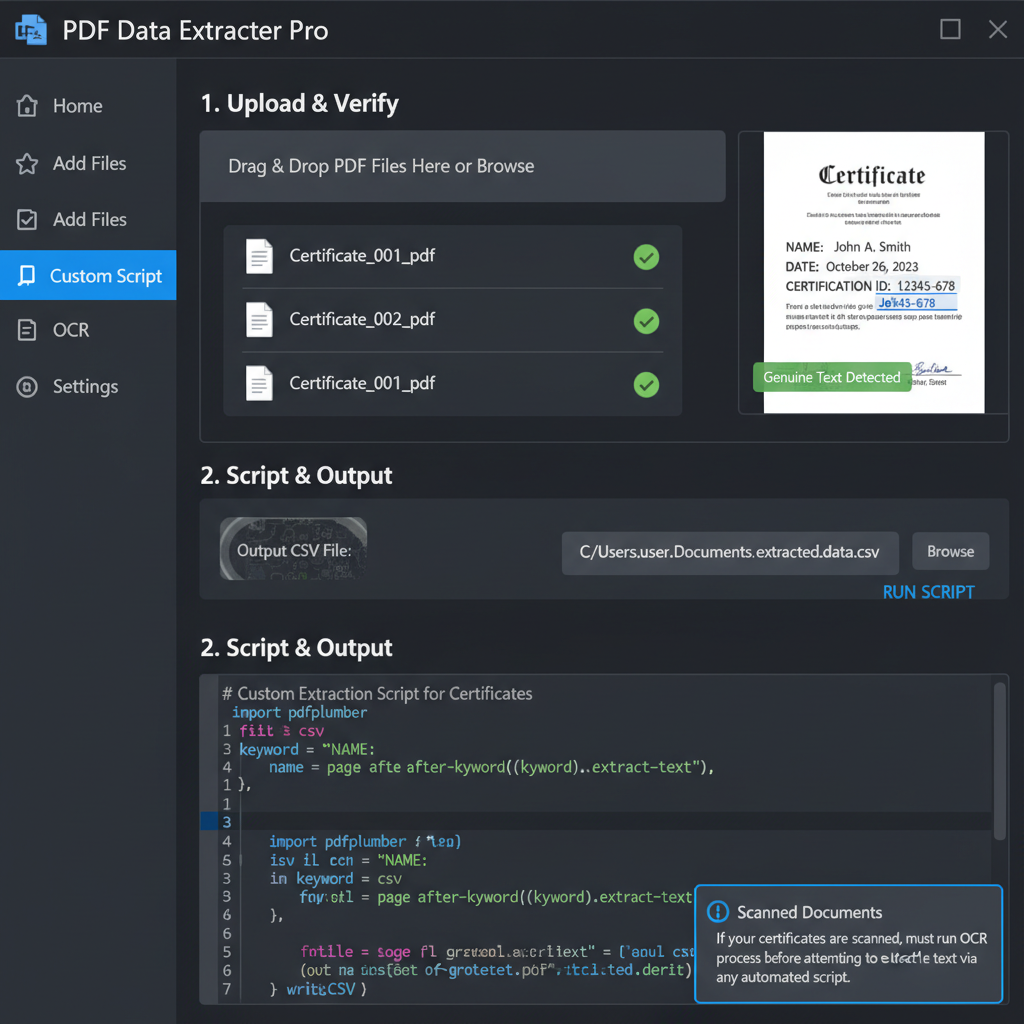
Check if your PDF files contain genuine, selectable text or if they are scanned images. Scanned documents will require OCR (Optical Character Recognition) processing before text can be successfully extracted.
Use a Custom Extraction Script for Consistent Layouts
Ideal for processing multiple PDFs like certificates that share the exact same layout and text positioning.
If your PDFs contain genuine text rather than scanned images, a custom script (using languages like Python with libraries such as PyPDF2 or pdfplumber) can programmatically read and export the text. This method relies heavily on the document layout being consistent across all files so the script knows exactly where to look for the data.
Open a sample PDF and try to highlight the text with your cursor. If it highlights, it is genuine text. If not, you will need to apply OCR first.
Determine the exact coordinates or surrounding keywords for the data you want to extract (for example, looking for the text immediately following 'Name:' or 'Date:').
Run a script to parse the PDFs, extract the target strings based on the identified patterns, and append them as rows to a CSV file using a standard CSV writer module.
Convert PDFs to Excel Using a PDF Converter
Best for users who prefer a graphical interface over coding, converting the entire PDF into a spreadsheet for manual data cleanup.
Batch Convert PDFs to Excel with WPS Office
WPS Office provides a powerful built-in PDF to Excel converter that supports OCR technology, allowing you to easily extract text and tables from both digital and scanned PDFs directly into a spreadsheet.
- 1. Open WPS Office: Launch WPS Office on your computer and go to the 'PDF' tab.
- 2. Access PDF to Excel: Click on 'PDF to Excel' located in the conversion toolbar.
- 3. Add Multiple Files: Click 'Add Files' in the dialogue box to import all the PDF certificates you want to process in bulk.
- 4. Start Conversion: Ensure the output format is set to Excel (.xlsx), then click 'Convert' to extract the text into spreadsheet format for easy CSV export.

Frequently Asked Questions
Can I extract text from a PDF if it is a scanned image?
Yes, but you must use OCR (Optical Character Recognition) software first. OCR converts the image of the text into selectable, machine-readable text that can then be parsed by scripts or exported to Excel.
Why is the extracted data formatting incorrect in Excel?
PDF and Excel handle formatting differently. A PDF is primarily a visual document without structural table data (unless it is a tagged PDF). When converting, the layout might break across cells, requiring manual data cleaning or a more precise custom parsing script to organize.
Is it possible to extract data from multiple PDFs without programming skills?
Yes. You can use dedicated PDF converter software like WPS Office, which offers a batch 'PDF to Excel' feature. While it converts the entire document layout into a spreadsheet rather than targeting specific fields like a custom script would, it eliminates the need for coding.


