

How to Extract Table Data from PDF to XML or CSV Using C#

Question details
The user wants to programmatically extract structured table content from a PDF file and convert it into XML or CSV formats using C#, while ignoring images and other non-table elements.
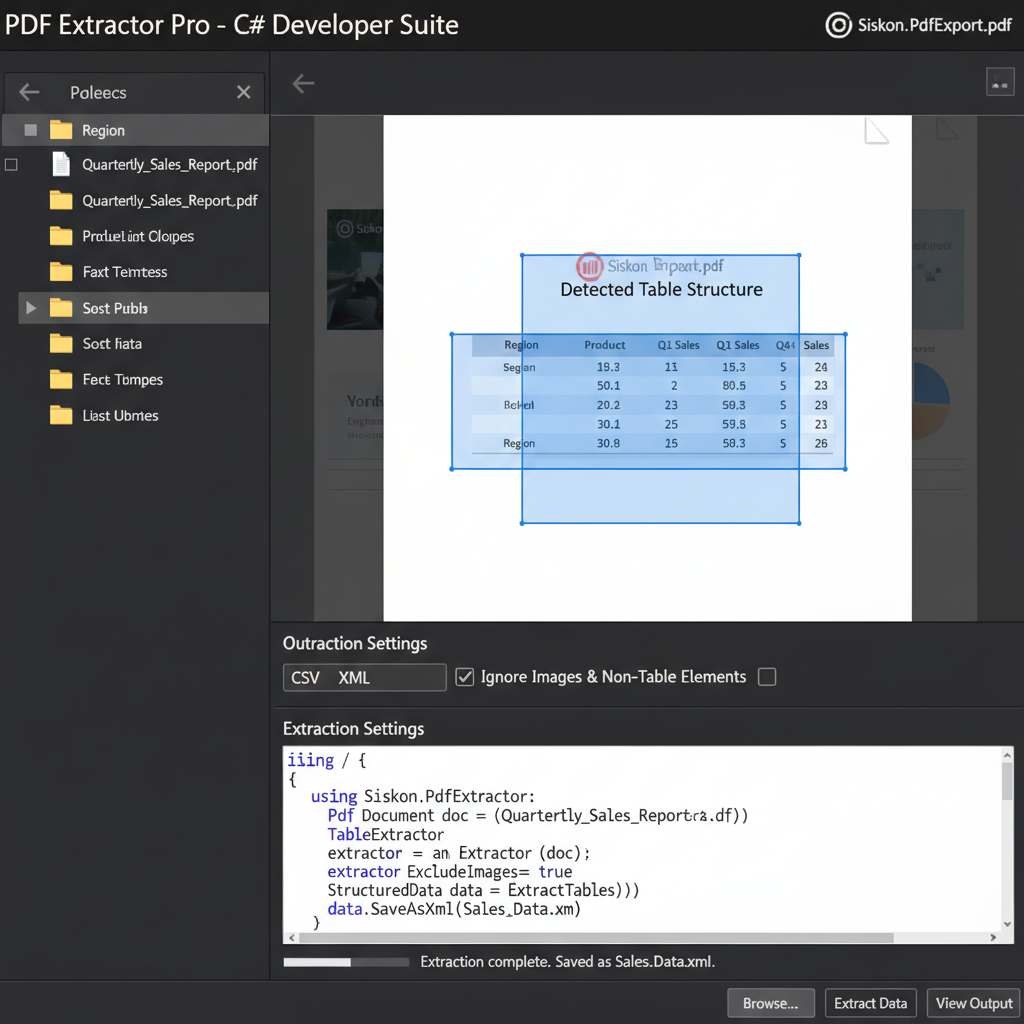
- Product
- PDF Extractor
- Device & OS
- not provided
- Scenario
- Developing a C# application to automate the extraction of tabular data from standard PDF documents into structured data formats like XML or CSV.
- Observed behavior
- Standard PDF files do not contain native table structures; they only store text and positioning. Existing tools like Acrobat Pro lack a direct C# workflow for converting this positioned text into XML or CSV.
Before attempting to write C# extraction code, understand that PDFs do not store standard HTML-like table tags. You will need a specialized third-party C# library equipped with table-detection algorithms to translate text coordinates into structured rows and columns.
Use a Specialized C# .NET PDF Extraction Library
Because PDFs only contain absolute text positioning, utilizing a dedicated C# library with built-in table detection is the most reliable way to convert PDF tables to CSV or XML.
A PDF document stores text strings, images, and vector graphics based on X and Y coordinates on a page. To extract a table, an algorithm must analyze these text bounding boxes and visual grid lines to dynamically reconstruct the logical rows and columns.
Research and identify a third-party C# .NET library that explicitly supports table detection and extraction (such as iText, PdfiumViewer, or a commercial PDF SDK).
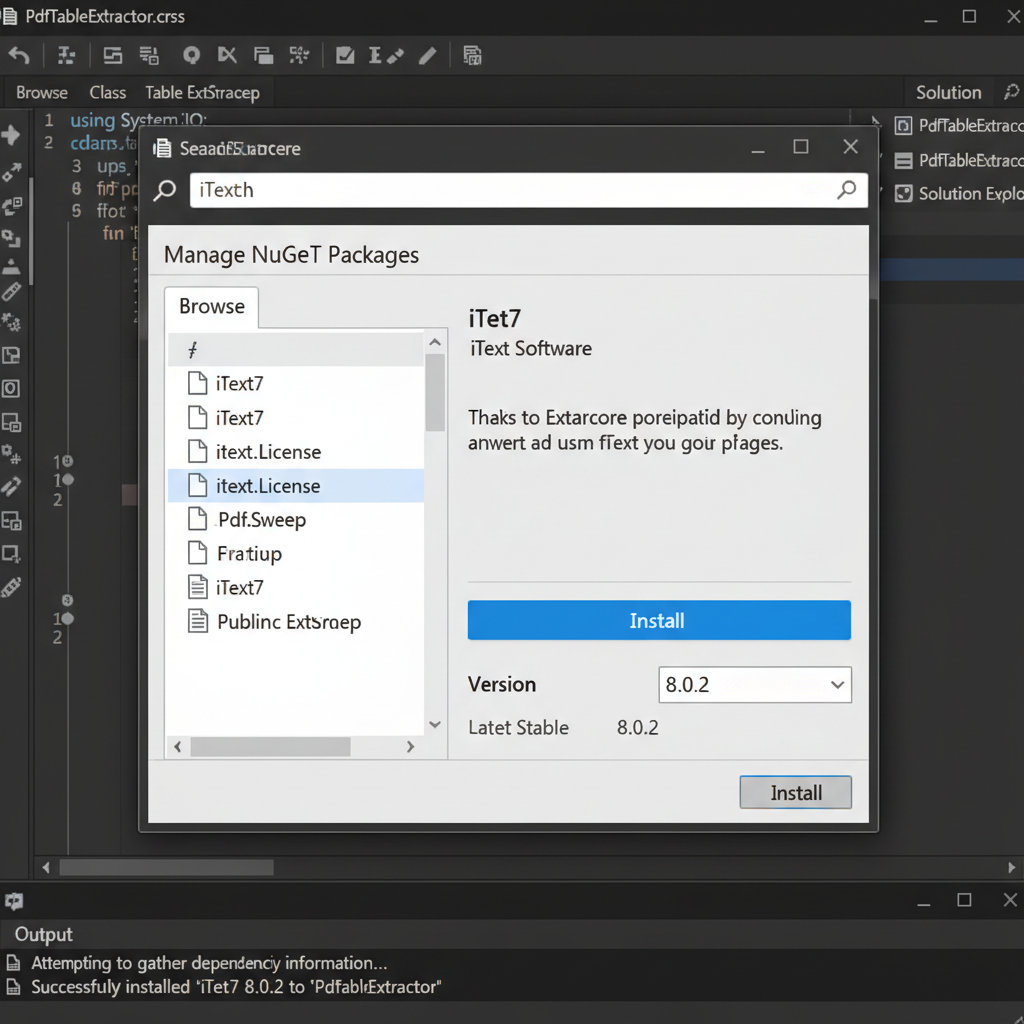
Open your project in Visual Studio, navigate to the NuGet Package Manager, and install the selected PDF extraction library.
Write C# code to load the PDF document and use the library's API to target the specific page and coordinate bounds where the table is located.
Invoke the library's table detection method to iterate through the positioned text, grouping the text strings into arrays of rows and columns.
Loop through the extracted 2D text array and format the strings using standard C# File I/O classes to write the output to a .csv or .xml file.
Extract PDF Tables to CSV Easily with WPS Office
If you do not strictly require an automated C# program, you can easily bypass complex table-detection algorithms by using the built-in PDF to Excel converter in WPS Office to extract tabular data seamlessly.
- 1. Open the PDF File: Launch WPS Office and open the PDF document containing the tables you wish to extract.
- 2. Select PDF to Excel: Navigate to the 'Tools' tab on the top ribbon and click the 'PDF to Excel' button.
- 3. Convert the Tables: Select the specific pages that contain your table data and click 'Convert' to generate a structured spreadsheet.
- 4. Save as CSV: Once the extracted table opens in WPS Spreadsheet, click 'Menu', select 'Save As', and choose 'CSV (Comma delimited)' from the format dropdown.

Frequently Asked Questions
Why is it difficult to extract table data from a PDF file?
PDFs are designed for fixed-layout visual presentation. They store text, images, and coordinates rather than structural HTML-like tags (such as <table> or <tr>), making programmatic table detection highly complex without specialized algorithms.
Does Adobe Acrobat Pro have a C# API for exporting PDF tables to XML?
No. Adobe Acrobat Pro does not offer a direct C# .NET programming workflow or native API function specifically built to parse table grids and export them directly to XML or CSV formats.
How can I convert a PDF table to CSV without writing code?
You can use desktop software like WPS Office. Simply open the PDF, use the 'PDF to Excel' conversion tool to extract the tables into a spreadsheet, and then use the 'Save As' function to export the document as a CSV file.
What kind of algorithm is needed for C# PDF table extraction?
A table extraction algorithm must parse text element coordinates, cluster them into rows based on horizontal Y-axis alignment, and separate them into columns by detecting gaps on the X-axis or by analyzing visual line elements drawn on the page.


