

How to Extract PDF Table Data with Acrobat SDK and VBA

Question details
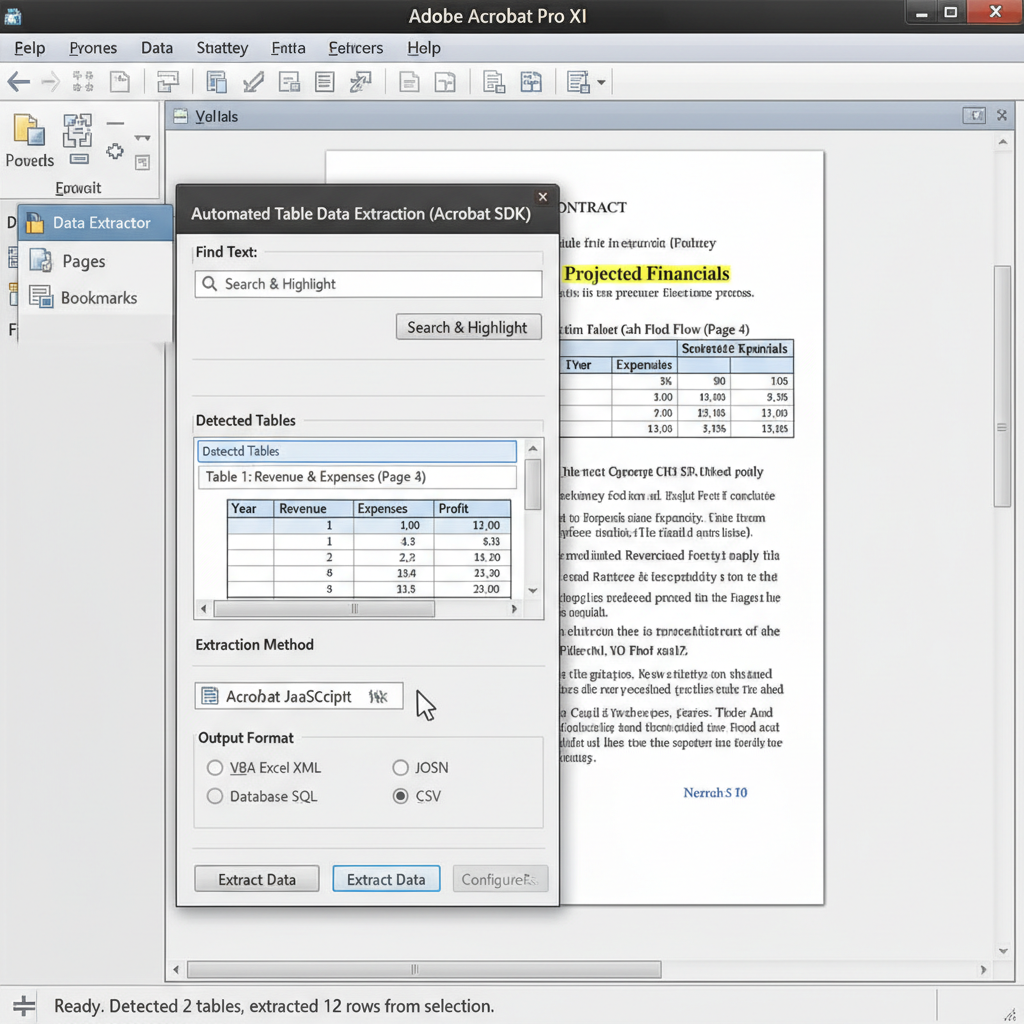
The user wants to locate specific text and extract subsequent structured tabular data (rows, cells, headers) from a PDF document using programming methods like Acrobat SDK, VBA, or JavaScript.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Automating the extraction of tabular data from PDF files for data processing or analysis.
- Observed behavior
- The user is looking for a programmable method to reliably identify and extract structured table data from PDFs, specifically using Acrobat XI.
Ensure you have Adobe Acrobat XI or later installed, and access to a development environment supporting VBA or JavaScript. Keep in mind that PDFs do not natively store table structures, so extracting reliable data relies heavily on coordinate analysis or OCR tools.
Use Acrobat's Built-in Export Features or Advanced Extraction Libraries
Because native text search in Acrobat SDK does not reliably capture table structures, utilizing advanced export functions or dedicated PDF data extraction libraries is recommended.
While the FindText method in Acrobat's SDK can locate text strings, it doesn't understand table structures like rows and columns. To accurately extract tabular data, you must analyze the bounding boxes and coordinates of text elements. For complex documents, writing custom coordinate-parsing VBA code is extremely difficult.
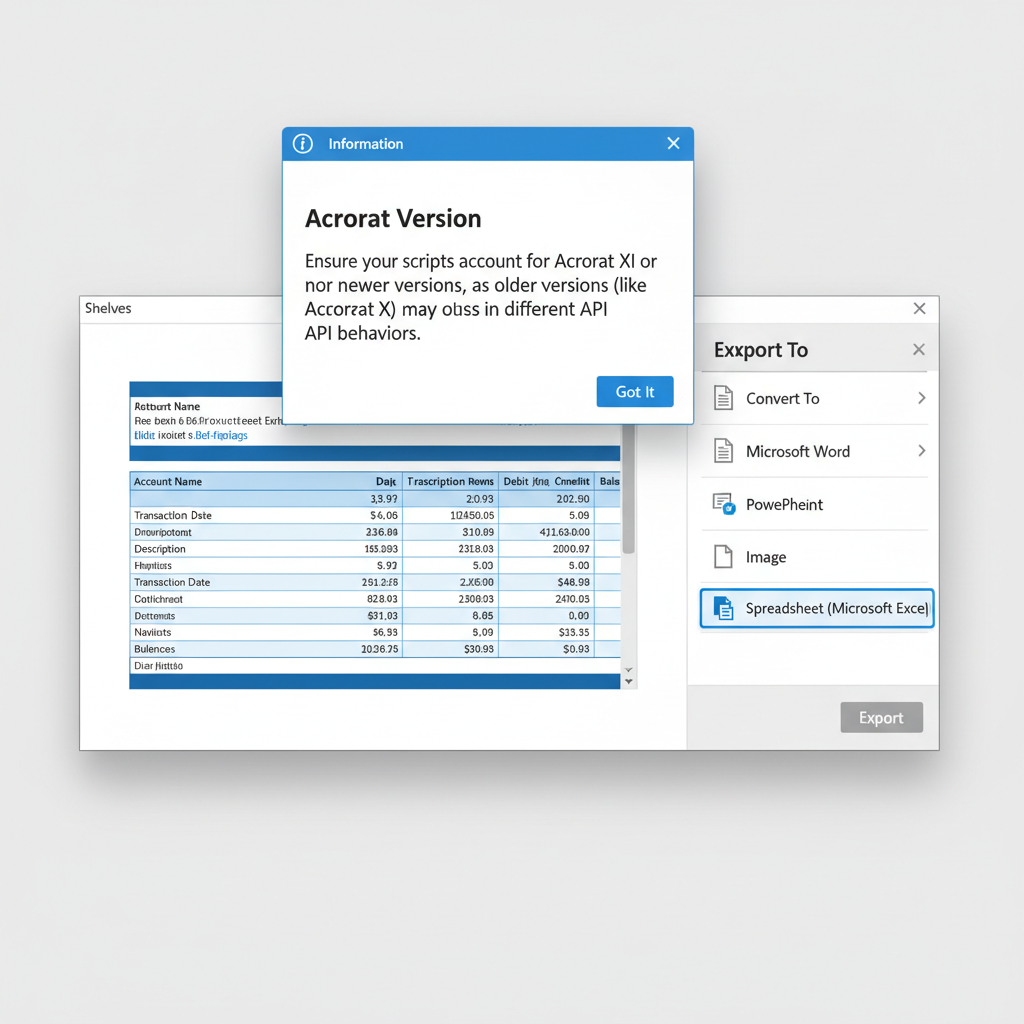
Instead of custom VBA text parsing, use Acrobat's 'Export To' feature (e.g., Export to Excel) via the SDK, which applies Adobe's internal table-recognition algorithms.
Consider integrating dedicated third-party PDF data-extraction libraries (like Tabula, PDFPlumber, or specialized APIs) into your workflow, as they are specifically designed to reconstruct tabular grids.
If you must use Acrobat SDK and VBA, use the JSObject to read the getPageNthWordQuads method. This retrieves the exact coordinates of words, allowing you to mathematically group text into rows and columns based on their Y and X axis alignment.
Extract PDF Tables Instantly with WPS Office
Skip the complicated VBA scripting and Acrobat SDK setups. WPS Office features a powerful built-in 'PDF to Excel' converter that automatically recognizes rows, columns, and headers in your PDF files, allowing you to extract complex table data with just a few clicks.
- 1. Open your PDF: Launch WPS Office and open the PDF file containing the tabular data you want to extract.
- 2. Select PDF to Excel: Navigate to the 'Tools' tab and click on the 'PDF to Excel' button.
- 3. Adjust Conversion Settings: Select the specific pages containing your tables and choose your preferred output location.
- 4. Convert and Edit: Click 'Convert'. Once finished, the newly generated Excel file will open automatically, allowing you to seamlessly edit and analyze the extracted table data.

Frequently Asked Questions
Why is extracting tables from PDFs so difficult?
PDFs are inherently designed for visual presentation, not data structuring. They store text and layout as graphical elements and coordinates, meaning concepts like 'rows' and 'columns' do not exist in the underlying code unless the PDF is specifically tagged.
Can I use the FindText method to extract columns in Acrobat VBA?
The FindText method is useful for locating specific words, but it does not capture tabular relationships. To extract columns, you must read the spatial coordinates of the text (e.g., using bounding boxes) and group them mathematically.
Are there easier alternatives to Adobe Acrobat for extracting PDF tables?
Yes, you can use built-in tools like the WPS Office PDF to Excel converter, which automatically recognizes table structures. For programming, open-source libraries such as Tabula, PDFPlumber, or Python's Camelot are specifically built for table extraction.
Does JavaScript work better than VBA for Acrobat PDF extraction?
JavaScript is often more deeply integrated into the Acrobat API using JSObject. It provides direct access to page content and coordinate methods, making it slightly more versatile than standard VBA for complex PDF parsing.


