

How to Find Duplicate Alphanumeric Serial Numbers in a PDF

Question details
The user needs a method to identify and locate duplicate 12-character alphanumeric serial numbers scattered throughout a large PDF document.
- Product
- Device & OS
- not provided
- Scenario
- Auditing or reviewing a large PDF file containing a massive list of serial numbers to ensure no values are repeated.
- Observed behavior
- Standard PDF readers like Acrobat do not provide a native search command or feature to automatically identify and highlight duplicate strings within a document.
Ensure your PDF contains selectable text rather than a scanned image. If your document is scanned, you must use an OCR (Optical Character Recognition) tool first to make the text readable and copyable.
Extract PDF Text to a Spreadsheet for Duplicate Highlighting
The most practical and user-friendly approach is transferring the PDF data into a spreadsheet program where built-in conditional formatting tools can instantly detect duplicates.
Spreadsheet applications are designed to handle massive amounts of structured data and include native features specifically for finding duplicate values, which PDF viewers lack.
Open your PDF, select all text (Ctrl+A), and copy it. Alternatively, use a dedicated 'PDF to Excel' export tool for cleaner formatting.
Open Excel or your preferred spreadsheet software and paste the extracted data into a single column.
If the serial numbers are mixed with other text, navigate to the Data tab and use the 'Text to Columns' feature to separate the 12-character alphanumeric values into their own distinct column.
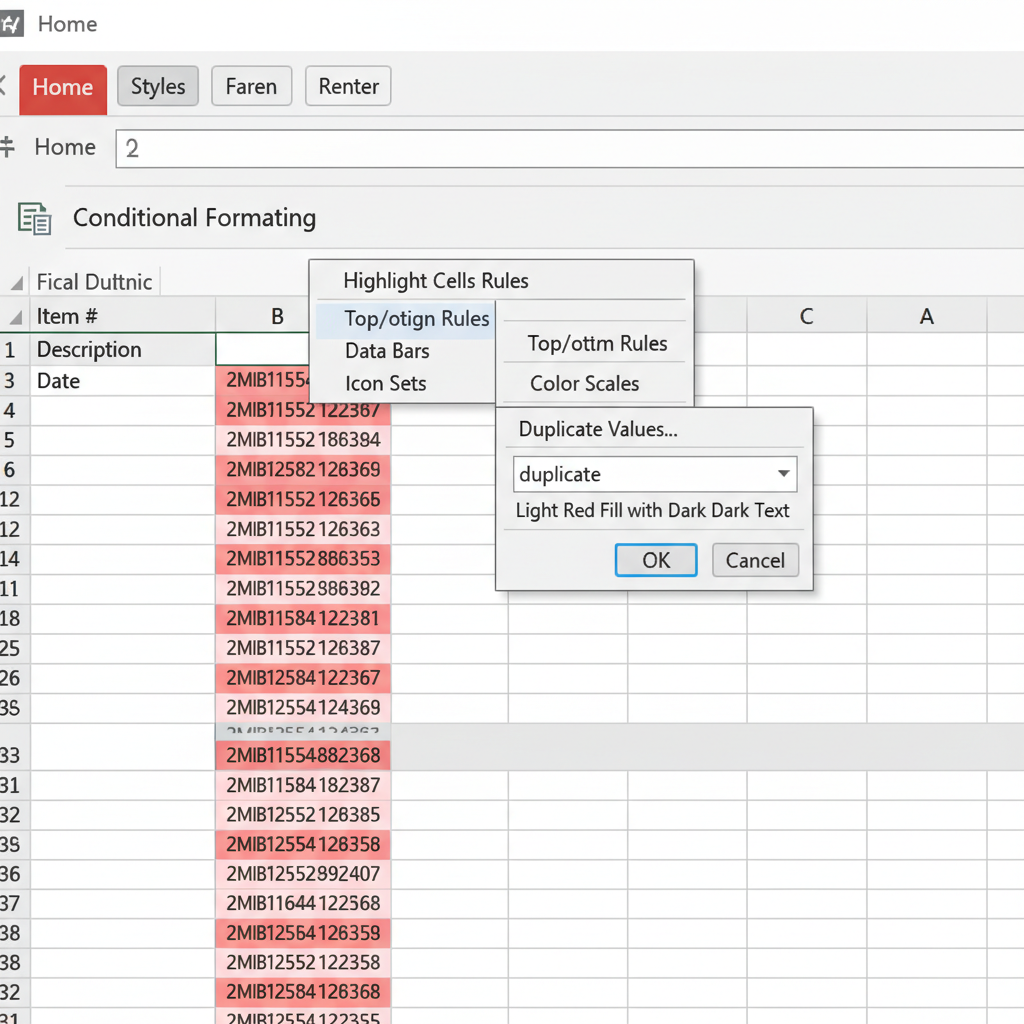
Select the column containing the serial numbers. Go to the Home tab, click 'Conditional Formatting', navigate to 'Highlight Cells Rules', and select 'Duplicate Values' to instantly highlight all repeats in color.
Use a Text Extraction Script for Very Large PDFs
For exceptionally large or complex PDF files where manual copy-pasting causes software crashes or errors, a custom script is the most reliable method.
Use WPS Office to Convert PDFs and Find Duplicates Instantly
WPS Office features an all-in-one workspace that integrates a powerful PDF editor and a robust Spreadsheet application. You can seamlessly convert your PDF into a structured spreadsheet and use native conditional formatting to locate duplicate serial numbers in seconds without juggling multiple apps.
- 1. Open PDF in WPS Office: Launch WPS Office and open the PDF file containing the alphanumeric serial numbers you need to audit.
- 2. Convert to Spreadsheet: Navigate to the 'Tools' tab and click 'PDF to Excel'. Choose your save location and let WPS Office accurately convert the text lists into a structured spreadsheet.
- 3. Highlight Duplicate Values: In the newly created spreadsheet, highlight the column with the serial numbers. On the Home tab, click 'Conditional Formatting', go to 'Highlight Cells Rules', and click 'Duplicate Values' to reveal all repeating numbers.

Frequently Asked Questions
Can I search for duplicates directly inside Adobe Acrobat?
No, Adobe Acrobat and most standard PDF readers do not feature a built-in command to search for and automatically highlight duplicate text values across a document. The data must be exported to a spreadsheet or text analysis tool.
What if my PDF text won't copy properly into a single column?
If manual copy-pasting results in messy or grouped formatting, use a dedicated 'PDF to Excel' converter tool. This approach preserves the document's tabular structure and places data into neat cells, making it much easier to isolate target serial numbers.
Is there a way to automate duplicate finding for multiple PDFs?
Yes, you can use a scripting language like Python to automate this process. A script can iterate through a folder of PDFs, extract all text, utilize a regular expression to capture the 12-character strings, and generate a final CSV report of all duplicates.
Why does my copied PDF text look like random symbols when pasted?
This typically occurs if the PDF was created with custom font encoding or if the document is a flattened scanned image without an active text layer. To resolve this, run an OCR (Optical Character Recognition) tool on the PDF before attempting to copy or export the text.


