

How to Find PDF Producer Metadata and Run OCR in Bulk

Question details
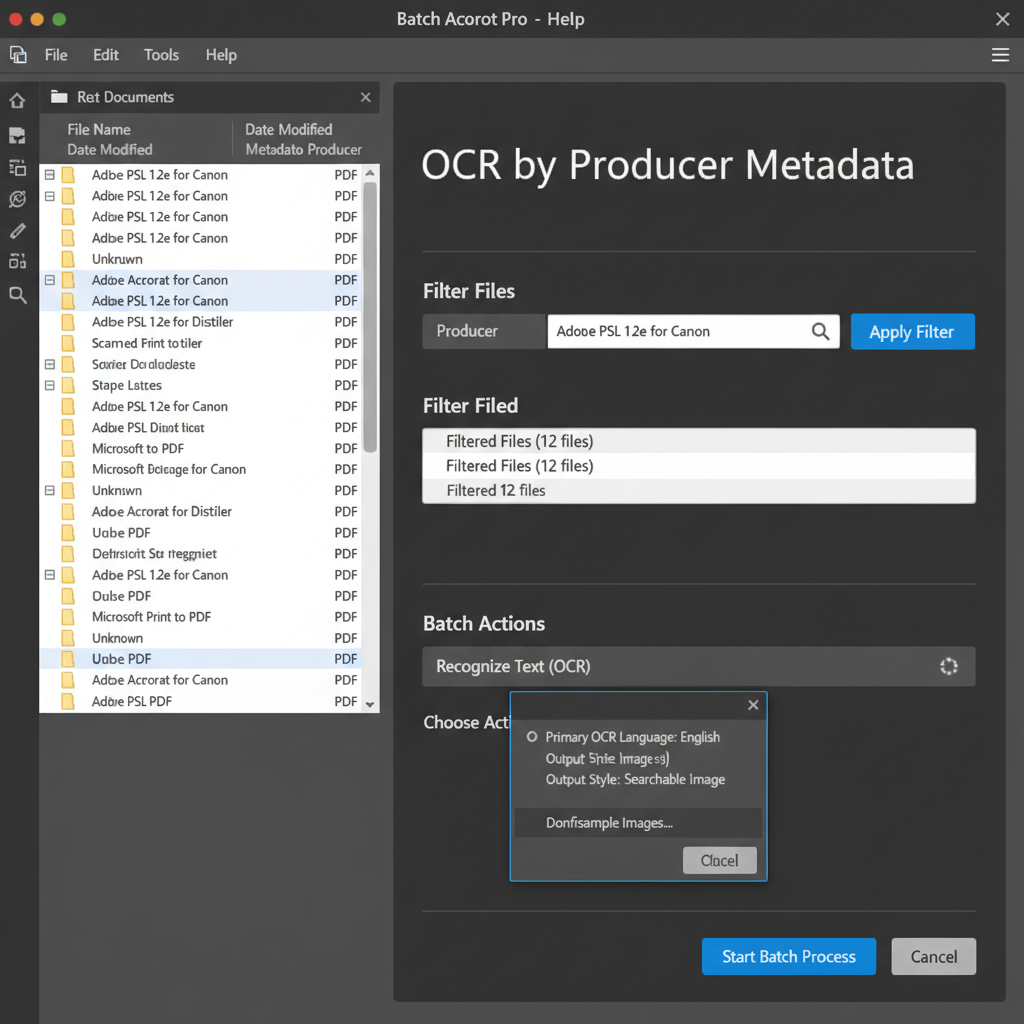
The user needs a method to identify and filter PDF files created by a specific Producer metadata value (such as Adobe PSL 1.2e for Canon) and then batch process those matching files using OCR.
- Product
- Adobe Acrobat Pro
- Device & OS
- not provided
- Scenario
- Managing a large collection of scanned PDF documents where only files generated by a specific scanner or software require text recognition.
- Observed behavior
- The user wants to automate the process of reading the 'Producer' field in the metadata to filter the files, followed by applying Adobe Acrobat Pro's OCR batch processing tools.
Always create a backup copy of your original PDF files in a separate folder before running bulk OCR, as text recognition can permanently alter the file size, searchable text layer, and document structure.
Filter Files by Metadata and Run OCR using Action Wizard
Use a script or metadata extraction tool to filter the PDFs by the Producer field, then process them in bulk using Adobe Acrobat Pro's Action Wizard.
Since Adobe Acrobat Pro does not natively support conditional batch processing based on metadata values, the most reliable workflow involves a two-step process: externally filtering the files, then batch processing the filtered folder.
Use a third-party batch metadata inspector like ExifTool or a custom script (e.g., Python with PyPDF2) to read the 'Producer' field of your PDFs. Move or copy the files matching your target value into a dedicated 'To_OCR' folder.
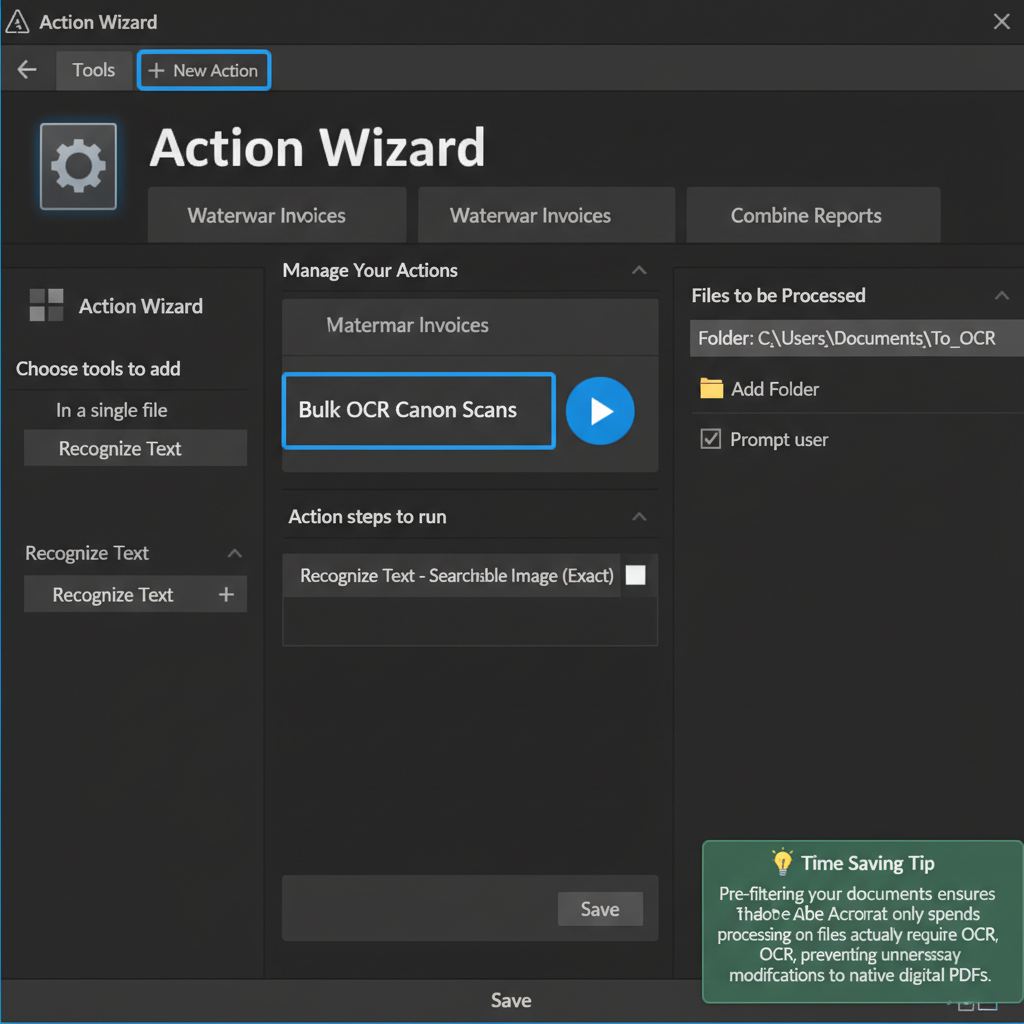
Launch Adobe Acrobat Pro. Navigate to the 'Tools' tab and click on 'Action Wizard' to open the batch processing dashboard.
Click 'New Action' in the toolbar. Under 'Files to be Processed', click 'Add Folder' and select the 'To_OCR' folder containing your pre-filtered PDF files.
In the left pane under 'Choose tools to add', expand 'Recognize Text', select 'Recognize Text', and click the '+' icon to add it to your action steps. Uncheck 'Prompt user' to ensure the process runs automatically.
Click 'Save', give your new Action a descriptive name (e.g., 'Bulk OCR Canon Scans'), and execute it by selecting it from the Action List and clicking 'Start'.
Use WPS PDF for Fast and Accurate OCR
If you are looking for a highly efficient and cost-effective alternative to Adobe Acrobat for handling scanned documents, WPS Office includes a powerful built-in OCR feature. It quickly extracts text from scanned PDFs and images, converting them into editable documents.
- 1. Open the scanned PDF: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and select 'OCR'.
- 3. Configure OCR settings: Choose whether you want to extract the text to a plain text file or convert the document directly into an editable Word file.
- 4. Run text recognition: Select the page range you need to process, choose the document language, and click 'Recognize' to begin the extraction.

Frequently Asked Questions
Does running OCR change the original PDF file size?
Yes, performing OCR typically increases the file size because it generates a hidden, searchable text layer that sits beneath the original scanned image.
How can I view a PDF's Producer metadata without Adobe Acrobat?
You can view basic PDF metadata in Windows by right-clicking the file, selecting 'Properties', and checking the 'Details' tab. Alternatively, you can open the file in standard PDF readers like WPS PDF and check the Document Properties.
Why did the OCR process fail to recognize certain text correctly?
OCR accuracy depends heavily on the source document's quality. Low resolution, poor contrast, handwritten text, or heavy scanning artifacts can cause errors. For optimal results, ensure your original scans are at least 300 DPI.


