

How to Fix Acrobat Cannot Recognize or Edit Text in a Scanned PDF

Question details
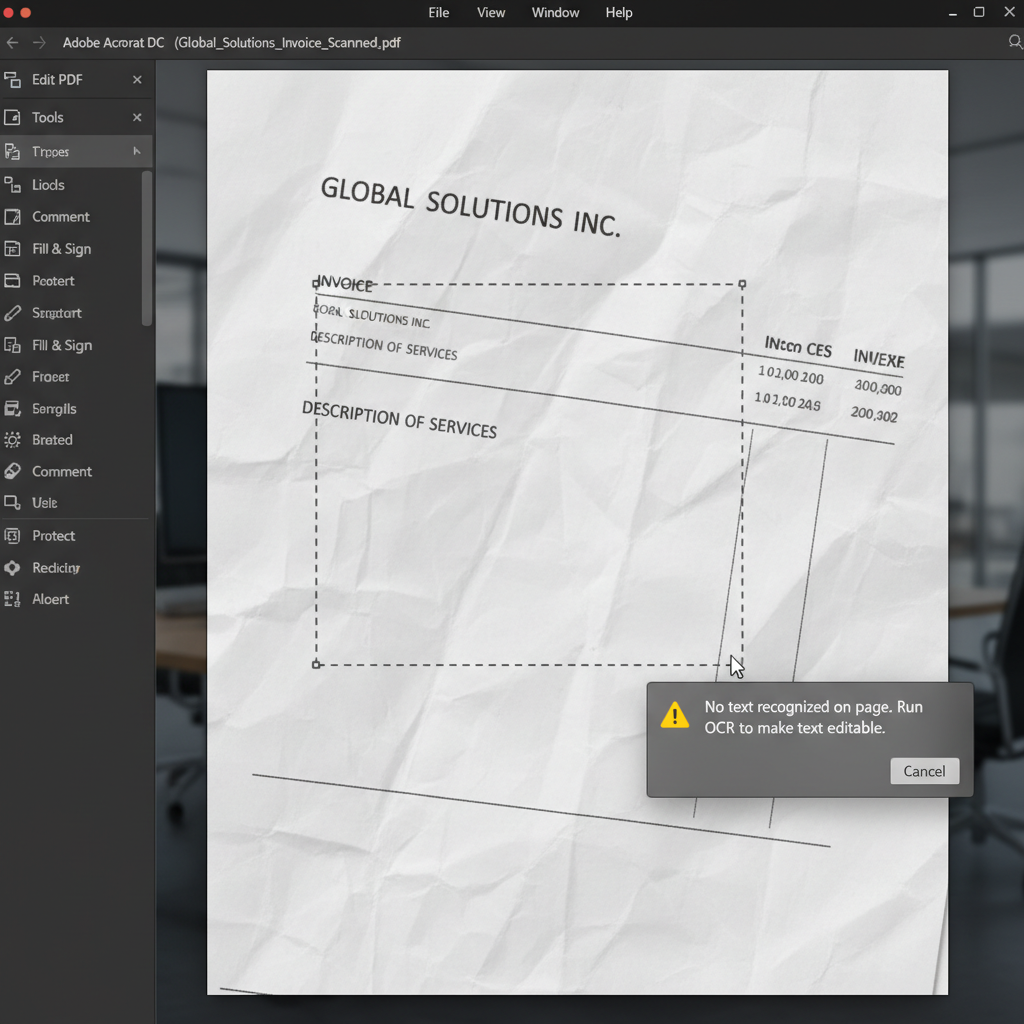
Adobe Acrobat DC is unable to identify or edit text in a scanned PDF document using the Edit Text and Images tool, likely due to low scan quality or improper OCR settings.
- Product
- Adobe Acrobat DC
- Device & OS
- not provided
- Scenario
- Attempting to select, edit, or search text within a scanned PDF document.
- Observed behavior
- The text cannot be selected or edited despite the editing tool being available, which typically occurs with lower-quality scans or un-recognized text layers.
Locate the original physical document if possible, as you may need to rescan it at a higher resolution for the OCR software to process the text accurately.
Run Manual OCR and Adjust Scan Resolution
Use the built-in Scan & OCR tool to manually recognize text and ensure the original scan meets the minimum quality requirements.
Optical Character Recognition (OCR) requires clear, high-contrast images to successfully convert pixels into editable text. Low resolution, skewed angles, blurriness, or heavy file compression will prevent Acrobat from accurately identifying the text.
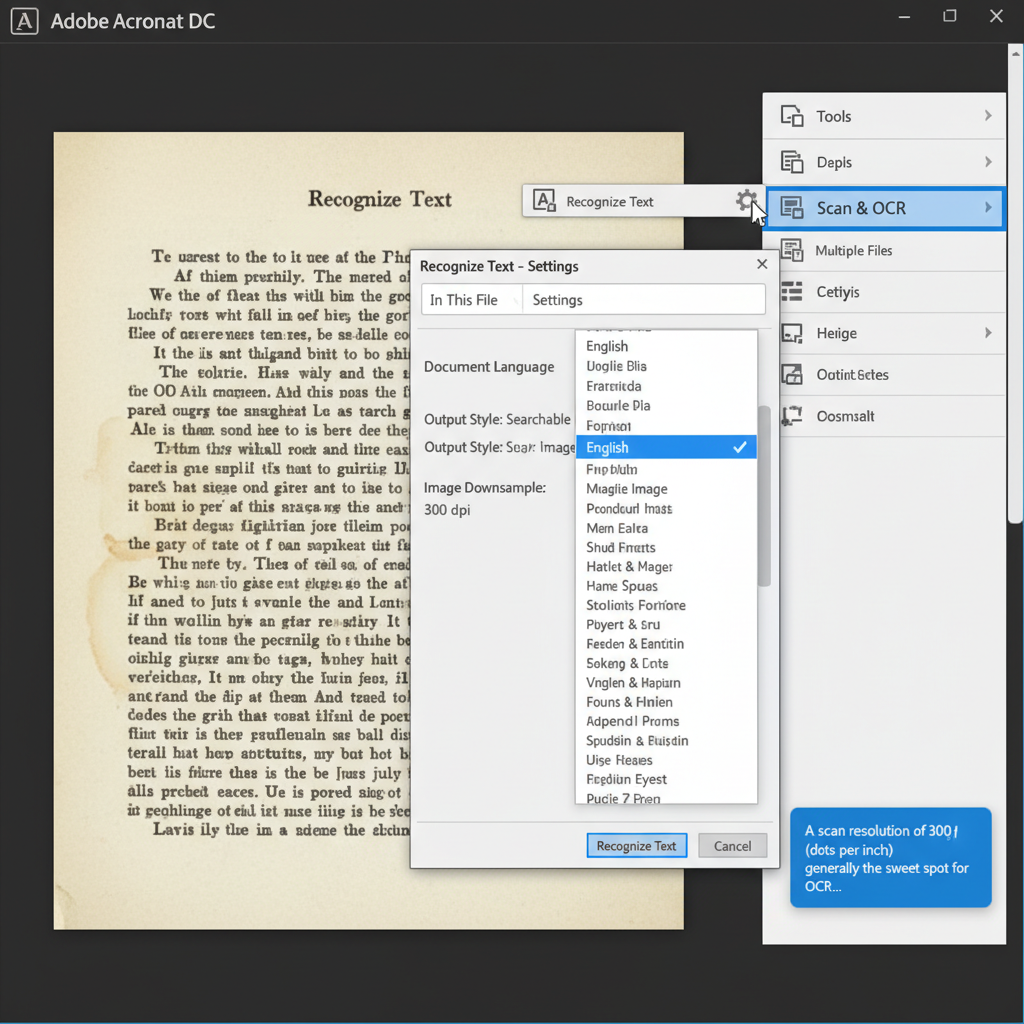
Open your scanned document in Acrobat DC. Navigate to the right pane or the Tools menu and select 'Scan & OCR'.
Click on 'Recognize Text' in the toolbar and choose 'In this File' from the dropdown menu.
Click the 'Settings' gear icon and ensure the correct document language is selected. This significantly improves recognition accuracy. Click 'Recognize Text' to begin the process.
If the text remains uneditable or garbled, the scan quality is too low. Rescan the original physical document at a resolution of approximately 300 dpi, ensuring the page is straight and has high contrast, then repeat the OCR process.
Extract and Edit Text from Scanned PDFs with WPS Office
WPS Office features a highly accurate built-in OCR engine that quickly converts scanned PDFs and images into fully editable text, offering a seamless and lightweight alternative for your PDF editing needs.
- 1. Open the Scanned PDF: Launch WPS Office and open your scanned PDF document in the PDF editor.
- 2. Access the OCR Feature: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Extract and Convert Text: Select the specific area or pages you want to extract, confirm your language settings, and extract the content into an editable text format.

Frequently Asked Questions
Why is the text in my scanned PDF garbled after running OCR?
Garbled text usually occurs when the document language is incorrectly set in the OCR options, or the original scan is too blurry, skewed, or lacks sufficient contrast. Try correcting the language settings or rescanning the physical document at 300 dpi.
Can I run OCR on a password-protected PDF?
If a PDF is protected with a permissions password that restricts editing or content copying, OCR and text editing tools will be disabled. You must enter the permissions password to unlock the document before you can recognize or edit the text.
Does increasing the scan resolution to 1200 dpi improve OCR?
No, scanning documents at extremely high resolutions like 1200 dpi does not significantly improve OCR accuracy and will create excessively large file sizes that slow down processing. Sticking to 300 dpi is highly recommended for standard text documents.


